

Deploying Machine Learning Models at Minimal Cost
This article demonstrates how to deploy a machine learning model on AWS with minimal infrastructure and cost, using Scikit-learn, AWS Lambda, and Lambda Function URLs. This approach eliminates the need for dedicated servers or machine learning endpoints that must remain constantly active, making it a cost-effective option for inference workloads with low traffic.
Deploying machine learning models to production does not always require expensive infrastructure or dedicated machine learning endpoints. For applications with low traffic and lightweight inference workloads, AWS Lambda provides a practical serverless alternative that runs code on demand. By combining Scikit-learn, Jupyter Notebook, AWS SAM, and Lambda Function URLs, developers can expose trained models through an HTTP API while reducing infrastructure management overhead.
In this tutorial, we will train a simple Iris classification model, export its structure to JSON, and deploy a lightweight inference function using AWS Lambda. We will then test the deployed endpoint with a sample HTTP request and discuss the main cost considerations, security implications, and limitations of this approach. The goal is to demonstrate a practical, low-cost deployment workflow for small machine learning models rather than a universal solution for every ML workload.
In this article, I will provide the steps for its implementation.
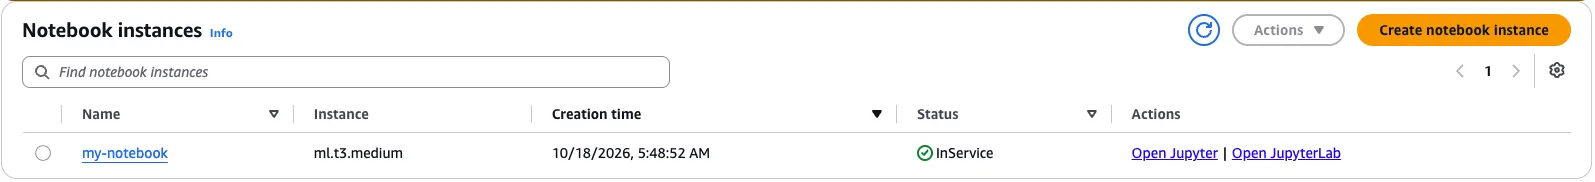
For a notebook in SageMaker, the smallest and cheapest instance is sufficient.
Create machine learning code for any scenario; for this example, I have chosen the prediction of flower species, a common use case when learning machine learning.
Starting with its structure:
1
2
3
4
5
6
7
jupyter/
├── notebooks/
│   └── experiment.ipynb
└── inference/
    ├── lambda_function.py
    └── model.json
    └── template.yaml
Create the model in a notebook, then export it.
The code for the deployment execution (template.yaml) is as follows:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29

AWSTemplateFormatVersion: '2010-09-09'
Transform: AWS::Serverless-2016-10-31
Description: Iris ML Prediction API

Globals:
  Function:
    Runtime: python3.12
    Architectures:
      - x86_64
    MemorySize: 512
    Timeout: 10

Resources:
  IrisPredictFunction:
    Type: AWS::Serverless::Function
    Properties:
      FunctionName: iris-predict
      CodeUri: .
      Handler: lambda_function.handler
      Description: Iris Random Forest prediction API
      FunctionUrlConfig:
        AuthType: NONE
        InvokeMode: BUFFERED

Outputs:
  IrisPredictFunctionUrl:
    Description: HTTPS prediction endpoint
    Value: !GetAtt IrisPredictFunctionUrl.FunctionUrl
In the notebook launcher, select "Terminal" and open it.

Then go to the SageMaker directory and install sam CLI.
1
2
3
4
5
6
7
8
9
10
11
12
# Download AWS SAM CLI for Linux x86_64
curl -Lo aws-sam-cli-linux-x86_64.zip \
  https://github.com/aws/aws-sam-cli/releases/latest/download/aws-sam-cli-linux-x86_64.zip

# Extract
unzip aws-sam-cli-linux-x86_64.zip -d sam-installation

# Instal SAM CLI
sudo ./sam-installation/install

# Check version
sam --version
Enter the inference directory and then run
sam build.
Then, run the following commands to check the CloudFormation status and create a bucket.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
$ aws cloudformation describe-stacks \
--stack-name aws-sam-cli-managed-default \
--region us-east-1 \
--query "Stacks[0].StackStatus" \
--output text

# Result
CREATE_COMPLETE

$ aws s3api create-bucket \
--bucket sam-deploy-iris \
--region us-east-1

# Result
{
    "Location": "/sam-deploy-iris",
    "BucketArn": "arn:aws:s3:::sam-deploy-iris"
}
Edit the contents of samconfig.toml as follows:
nano samconfig.toml1
2
3
4
5
6
7
8
9
10
11
version = 0.1
[default.global.parameters]
region = "us-east-1"
[default.deploy.parameters]
stack_name = "flower-predict"
resolve_s3 = false
s3_bucket = "sam-deploy-iris"
capabilities = "CAPABILITY_IAM"
confirm_changeset = trueThen run the following command:
1
2
3
4
5
6
sam deploy \
  --stack-name flower-predict \
  --s3-bucket sam-deploy-iris \
  --region us-east-1 \
  --capabilities CAPABILITY_IAM \
  --no-confirm-changeset
The process will proceed from CloudFormation to Lambda, and upon success, it will display the following message: "Successfully created/updated stack - flower-predict in us-east-1"
Run this to get the URL:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
$ aws cloudformation describe-stacks \
  --stack-name flower-predict \
  --region us-east-1 \
  --query "Stacks[0].Outputs" \
  --output table

# Result
----------------------------------------------------------------------------------------------------------------------------------
|                                                         DescribeStacks                                                         |
+---------------------------+-------------------------+--------------------------------------------------------------------------+
|        Description        |        OutputKey        |                               OutputValue                                |
+---------------------------+-------------------------+--------------------------------------------------------------------------+
|  HTTPS prediction endpoint|  IrisPredictFunctionUrl |  https://56srxdjoordv434wusncxyorcm0mffpc.lambda-url.us-east-1.on.aws/   |
+---------------------------+-------------------------+--------------------------------------------------------------------------+
after that, run a curl command to that endpoint with the payload:
1
2
3
4
curl -X POST \
  "https://56srxdjoordv434wusncxyorcm0mffpc.lambda-url.us-east-1.on.aws/" \
  -H "Content-Type: application/json" \
  -d '{"features":[5.1,3.5,1.4,0.2]}'
the results will appear:
1
2
3
4
{
  "prediction": 0,
  "class_name": "setosa"
}
we can also do this in the Lambda UI, as shown in the following image:

Ensure that the IAM role for SageMaker also grants permissions for CloudFormation and the S3 bucket.
Cost Analysis
To evaluate the cost-effectiveness of this architecture, we can estimate inference costs based on the number of requests, allocated memory, and execution duration. For example, assume the Iris model receives 1,000 predictions per day, with an average execution duration of 100 milliseconds and 512 MB of allocated memory. Over a 30-day month, this represents 30,000 requests and approximately 1,500 GB-seconds of compute usage.
Using the published AWS Lambda example rates for the US East (N. Virginia) Region, the estimated request and compute charges total approximately $0.031 per month before applicable free-tier benefits, data transfer, logging, storage, and other AWS services. Actual costs may differ depending on measured execution time, region, account eligibility, and workload characteristics.
This estimate covers inference only. Model development also incurs costs when SageMaker notebook instances or other compute resources are running. Therefore, the overall cost should be evaluated using both pricing estimates and actual AWS billing data. For small, infrequently invoked models, Lambda can be a cost-effective alternative to maintaining a continuously running inference endpoint.
Cost Calculation for 1,000 Requests per Day
To estimate the cost of deploying a machine learning model using AWS Lambda, assume the Iris classification API receives 1,000 requests per day. With an average execution duration of 100 milliseconds and 512 MB of allocated memory, the service processes approximately 30,000 requests per month.
1. Compute cost
Lambda compute usage is calculated by multiplying the execution duration by the allocated memory.
- Monthly requests: 1,000 × 30 = 30,000 requests
- Allocated memory: 512 MB = 0.5 GB
- Average execution duration: 100 ms = 0.1 seconds
- Monthly compute usage: 30,000 × 0.1 × 0.5 = 1,500 GB-seconds
Using an illustrative AWS Lambda compute rate of $0.0000166667 per GB-second in the US East (N. Virginia) Region:
1,500 × $0.0000166667 = $0.025 per month
2. Request cost
Assuming a request charge of $0.20 per one million requests:
30,000 ÷ 1,000,000 × $0.20 = $0.006 per month
3. Total estimated inference cost
| Component | Monthly cost |
|---|---|
| Compute | $0.025 |
| Requests | $0.006 |
| Total | $0.031 |
Under these assumptions, the estimated Lambda inference cost is approximately $0.031 per month, before applicable free-tier benefits, data transfer, logging, storage, and other charges.
This estimate covers only the inference workload. It excludes SageMaker notebook usage during model development and other AWS resources. Actual costs depend on the AWS Region, measured execution duration, account eligibility, and current pricing. For a lightweight model processing 1,000 requests per day, AWS Lambda can be an economical option for serving predictions through an HTTP API without maintaining a continuously running inference server.
Deploying machine learning models does not have to involve expensive infrastructure or complex deployment processes. By combining Scikit-learn, Jupyter Notebook, AWS Lambda, and AWS SAM, developers can build and deploy lightweight machine learning APIs with minimal operational overhead. As demonstrated in this tutorial, a simple Iris classification model can be exposed through an HTTP endpoint and serve predictions on demand, making serverless deployment a practical option for applications with relatively low traffic.
However, minimizing cost requires more than choosing a serverless service. Developers should consider execution time, memory allocation, request volume, security, and the cost of supporting resources such as development environments and storage. The estimated inference cost provides a useful starting point, but actual expenses should be validated against AWS pricing and billing data. By measuring usage and selecting infrastructure that matches the workload, developers can build machine learning solutions that are both cost-efficient and reliable.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article