

Keep LLM bills under control on Amazon Bedrock
A tested Lambda gateway that checks each user's daily budget in DynamoDB before it calls Claude, plus the caching settings and the monthly math.
Amazon Bedrock bills every token, so a large language model (LLM) bill grows with every request your users send. For Bedrock cost optimization in code, we built an AWS Lambda gateway that checks each user's daily budget in Amazon DynamoDB before it calls a model. It charges the real cost after the call.
It's for developers who call Claude on Bedrock from a backend and want a hard daily limit per user. You get the reserve-then-settle pattern with the real conditional write, the thinking and caching settings that change the bill, and the monthly math. We haven't deployed the stack, and no real Bedrock call has run. Every result here comes from 83 local tests and CI.
Key takeaways
- Reserve the worst-case cost with one conditional
UpdateItembefore the call, then settle to the real cost fromusage. In our test, 60 concurrent reservations raced for room for 33, and 33 won.
- Claude Haiku 5.5 and Claude Sonnet 5.5 both think by default, and thinking bills as output. Turn it off, or set low effort, in
additionalModelRequestFields.
- Under our assumptions, 600,000 requests cost $6,600 a month on Sonnet 5.5 alone and $1,133.76 routed and cached. Routing saves far more than caching.
- Neither model is on the Bedrock batch inference support list, so the 50% batch discount isn't available for them.
- Claude charges show up under the model provider in Cost Explorer, not under Amazon Bedrock. Three cost-tracking questions have no answer on any AWS page we found.
At a glance | |
|---|---|
Level | Intermediate |
Time to read | 10 minutes |
Cost | About $1,134 a month in model calls for 600,000 requests under our assumptions in us-east-1. DynamoDB writes and Lambda requests add $0.87; we haven't measured Lambda duration |
Code | InfraTales/bedrock-cost-controls |
Tested with | Node.js 24, AWS Cloud Development Kit (CDK) 2.273, 83 tests (23 against DynamoDB Local), 11 mutation checks ( npm run mutate ), cdk-nag |
Deployed | Not yet. No real Bedrock call has run |
Know which prices move the bill
The gateway calls both models through global cross-Region inference profiles,
global.anthropic.claude-haiku-5-5 and global.anthropic.claude-sonnet-5-5 . Claude Sonnet 5.5 launched on Bedrock on 28 September 2026. The AWS Price List API gave these us-east-1 prices on 16 October 2026. All are dollars per million tokens:Model | Input | Output | Cache read | Cache write, 5 min | Cache write, 1 hour |
|---|---|---|---|---|---|
Claude Haiku 5.5 | 0.10 | 0.50 | 0.01 | 0.125 | 0.20 |
Claude Sonnet 5.5 | 2.00 | 10.00 | 0.10 | 2.50 | 4.00 |
Output costs five times input, so
maxTokens caps the worst case more than any other setting. Sonnet 5.5 output costs 20 times Haiku 5.5 output. The US geographic profiles ( us.* ) cost 10% more. Global routing can send a request to any supported commercial Region, so check your data residency rules first.
Two discounts from other models don't apply. Neither model is on the batch inference support list, and both model cards mark Batch unsupported. Batch costs 50% less where it exists. Both cards also mark the Flex and Priority tiers unsupported.
Follow one request through the gateway
Your backend signs each request with AWS Signature Version 4 (SigV4) and sends a user ID, a prompt and a task. A request goes this way:
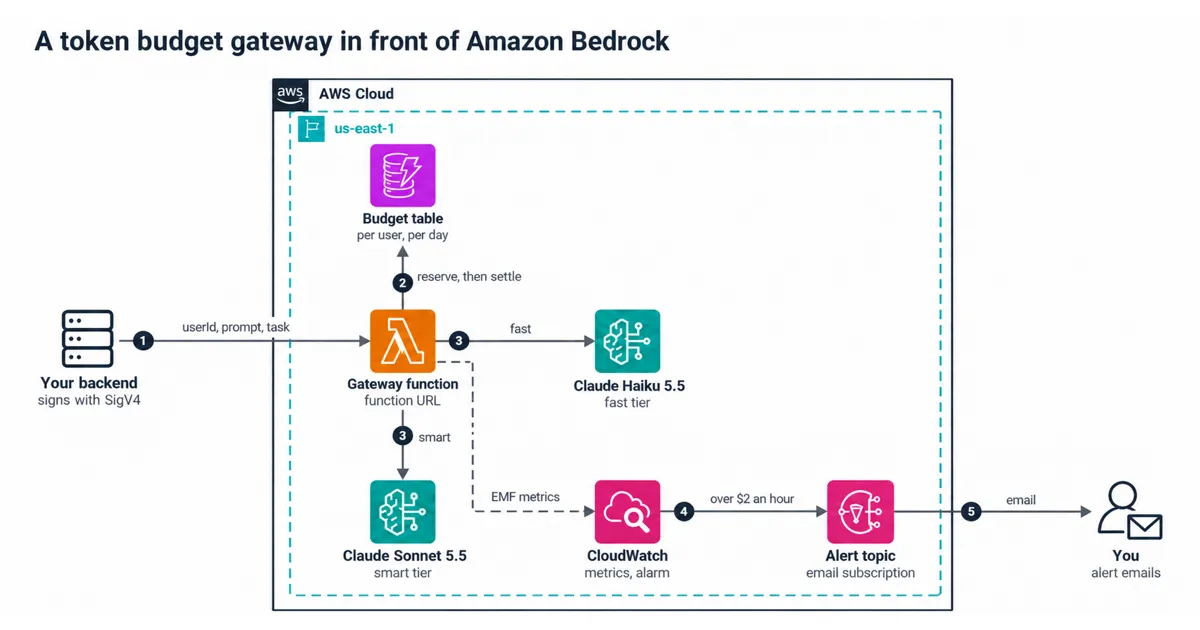
Each call writes to the budget table twice. Chat, classify, extract and summarize go to Haiku 5.5, while code, analysis and planning need Sonnet 5.5. Metrics go to Amazon CloudWatch, and AWS Budgets watches the whole account as a slower backstop.
Enforce an LLM token budget per user
Each user gets one DynamoDB item per day in UTC, holding
used in micro-dollars. A price in dollars per million tokens is the same number in micro-dollars per token, so the math stays in whole numbers. The default limit is 500,000 micro-dollars, or $0.50 a day.
Before each call, the gateway works out the most the call could cost. It counts one input token per byte of text, which errs high, and adds
maxTokens times the output price. For a short question with our 5,296-character system prompt, the reservation is 1,177 micro-dollars on Haiku 5.5 and 33,766 on Sonnet 5.5.
DynamoDB condition expressions can compare but can't add, so
used + amount <= limit isn't valid. We do the subtraction in code and send the ceiling instead. This is the reservation in app/src/budget.ts :TypeScript
const ceiling = this.limitMicroUsd - amount;if (ceiling < 0) return { ok: false, reason: 'over_budget' };const day = dayKey(this.now());try {await this.doc.send(new UpdateCommand({TableName: this.tableName,Key: this.key(userId, day),UpdateExpression: 'ADD used :amount SET expiresAt = if_not_exists(expiresAt, :expiresAt)',ConditionExpression: 'attribute_not_exists(used) OR used <= :ceiling',ExpressionAttributeValues: { ':amount': amount, ':ceiling': ceiling, ':expiresAt': expiresAt(day) },}),);return { ok: true, day, amount };} catch (err) {if (err instanceof ConditionalCheckFailedException) return { ok: false, reason: 'over_budget' };throw err;}
DynamoDB checks the condition and applies the
ADD as one atomic step, so two requests can't both squeeze into the last bit of room. Our DynamoDB Local test races 60 reservations of 30 against a limit of 1,000, and the counter ends at 990. A refused reservation returns a 429 without calling Bedrock. A smart request that doesn't fit falls back to Haiku 5.5 before it gets a 429.Settle each call to its real cost
After the call,
settle adds the difference between the real cost and the reservation. It has no condition, because Bedrock already billed the tokens. It writes to the reservation's day, so a call reserved at 23:59:59 corrects yesterday's counter. If Bedrock fails, the gateway gives the whole reservation back, and DynamoDB time to live (TTL) deletes each counter a week later.
The real cost comes from the response's
usage : inputTokens , outputTokens , cacheReadInputTokens and cacheWriteInputTokens , each at its own rate and rounded up. The prompt caching page says inputTokens counts only tokens not read from or written to the cache. The API reference calls it the tokens sent in the request, and we followed the caching page.What we got wrong first: reading mutant failures
We broke each safeguard once to see whether a test would notice. Our first mutant deleted the
ConditionExpression line, and 18 integration tests failed. That looked like strong coverage.
Then we read the failures. DynamoDB rejected every request with a
ValidationException , because :ceiling was now an unused expression value. The tests failed for a reason unrelated to the budget. The useful mutant kept the request valid and made the condition pass for any value ( :ceiling = :ceiling ). Five tests caught it: the two limit-edge tests and the three concurrency races.
A failing mutant proves nothing until you read why it failed.
npm run mutate now breaks 11 safeguards one at a time against DynamoDB Local, and CI runs it on every pull request. Each mutant must make a test file listed for it fail. Swapping <= for < breaks 2 tests, and settling against today breaks the midnight test.Turn off thinking where you don't need it
Both models think by default. The Haiku 5.5 and Sonnet 5.5 model cards both say adaptive thinking "is on by default". Bedrock bills thinking tokens as output tokens, and
maxTokens caps thinking plus answer together. Left on, thinking spends part of a Haiku call's 1,024 tokens before the answer starts.
Converse takes these settings in
additionalModelRequestFields . Our fast tier turns thinking off. The smart tier thinks at low effort:TypeScript
const system: SystemContentBlock[] = [{ text: systemPrompt }];if (shouldCache(model, systemPrompt)) system.push({ cachePoint: { type: 'default' } });return {modelId: model.modelId,system,messages: [{ role: 'user', content: [{ text: prompt }] }],inferenceConfig: { maxTokens: model.maxTokens },// Model-specific fields go here. Without them, both models think by default.additionalModelRequestFields:model.thinking === 'off'? { thinking: { type: 'disabled' } }: { thinking: { type: 'adaptive' }, output_config: { effort: 'low' } },};
Notice
maxTokens on every call: 1,024 for Haiku 5.5 and 2,048 for Sonnet 5.5. Leave it out, and you get the model's maximum of 128K output tokens, thinking included.Cache the shared system prompt
A cache read costs a tenth of plain input on Haiku 5.5. On Sonnet 5.5 it costs a twentieth, after a 50% cut on 7 October 2026. A 5-minute cache write costs 1.25 times input, so that prefix pays for itself the second time you use it. A 1-hour write costs twice input and needs a third use to break even.
The default TTL is 5 minutes. In Converse, you add
"ttl": "1h" to the cachePoint object for the longer one, and the gateway keeps the default. Each model also has a minimum prefix per cache checkpoint, 512 tokens for both. Below it, the call still succeeds, but Bedrock caches nothing.
Our system prompt is 5,296 characters, which we estimate at 1,324 tokens at four characters per token. CountTokens isn't available for these models on
bedrock-runtime , so the number stays a guess until a real call reports cacheWriteInputTokens .Watch spend you can see today
AWS Budgets updates up to three times a day, with a usual gap of 8 to 12 hours. That's too slow to stop a bad day, so the gateway records its own numbers. Each call writes an Embedded Metric Format (EMF) log line with tokens and cost per tier, eight metrics in all, and refusals get a ninth.
The user ID is a log field, not a dimension, so the count stays at nine as users grow. A CloudWatch alarm sums cost for both tiers each hour and emails you through Amazon Simple Notification Service (SNS) above $2. An account-wide budget of $20 a month alerts at 80% actual and 100% forecast spend.
Check three gaps in Bedrock cost tracking
Claude Haiku 5.5 and Sonnet 5.5 bill through AWS Marketplace. Their model cards say the charges appear in Cost Explorer under the model provider, not under Amazon Bedrock. That raised three questions no AWS page answers:
- Marketplace billing and tags. Application inference profiles carry tags that "flow to AWS Cost Explorer and AWS Cost and Usage Reports." No page says whether those tags reach charges billed through Marketplace.
- The Budgets service name. We found no service name for Claude Marketplace charges in an AWS Budgets filter, so our budget covers the whole account.
- Copying profiles. We planned to copy application profiles from the global profiles, but no page shows that working. The opt-in
costTagsmode copies theus.*profiles, which cost 10% more.
If you try the tags anyway, turn them on before the traffic you want to track. Cost allocation tags aren't retroactive, and keys can take up to 24 hours to appear and another 24 to activate.
Work out the monthly cost
The cost model in
scripts/cost-model.ts runs on assumptions, not measurements: 1,000 users making 20 requests a day for 30 days. Each call carries a 1,300-token system prompt and a 200-token prompt. Output is 300 tokens on Haiku 5.5, which has thinking off, and 800 on Sonnet 5.5, which includes its low-effort thinking. Haiku takes 80% of requests; 95% of calls hit the cache.
Each line below is in micro-dollars per call, then dollars a month:
Item | Math | Result |
|---|---|---|
Haiku 5.5, cache read | 200 × 0.10 + 300 × 0.50 + 1,300 × 0.01 | 183 |
Haiku 5.5, cache write | 200 × 0.10 + 300 × 0.50 + 1,300 × 0.125, rounded up | 333 |
Sonnet 5.5, cache read | 200 × 2 + 800 × 10 + 1,300 × 0.10 | 8,530 |
Sonnet 5.5, cache write | 200 × 2 + 800 × 10 + 1,300 × 2.50 | 11,650 |
Haiku 5.5 month | 480,000 × (0.95 × 183 + 0.05 × 333) = 480,000 × 190.5 | $91.44 |
Sonnet 5.5 month | 120,000 × (0.95 × 8,530 + 0.05 × 11,650) = 120,000 × 8,686 | $1,042.32 |
Total | | $1,133.76 |
Sonnet 5.5 is 92% of that bill on 20% of the requests.
npm run cost prints the same model for other setups:Setup | Per month |
|---|---|
Everything on Sonnet 5.5, no caching, US geo profile | $7,260.00 |
Everything on Sonnet 5.5, no caching | $6,600.00 |
Routed 80/20, no caching | $1,464.00 |
Routed 80/20, with caching (this repo) | $1,133.76 |
Routed 80/20, with caching, US geo profile | $1,247.45 |
Routing takes the bill from $6,600 to $1,464, and caching cuts about another 23%. Two DynamoDB writes per call add about $0.75 and Lambda requests $0.12, plus duration we haven't measured. Nine metrics fit in CloudWatch's 10 free ones. Guardrails content filters would add $0.15 per 1,000 text units, and the gateway uses none.
When this isn't the right fit
- You stream responses. The gateway settles after the full reply, so streaming needs the settle step after the stream ends.
- Your data must stay in one geography. Switch to the
us.*profiles and pay 10% more.
- You bill customers per token. The reservation errs high, and a function that dies after Bedrock answers leaves the reservation on that day's counter.
- You can't trust your callers with user IDs. Anyone with invoke permission can spend any user's budget.
- You run offline bulk jobs. Pick a model that supports batch inference at half price.
Try it yourself
You need Node.js 24 and Docker. The first four commands need no AWS account:
Bash
npm cinpm run checkdocker run -d --rm -p 8022:8000 amazon/dynamodb-local:3.3.2AWS_ENDPOINT_URL_DYNAMODB=http://localhost:8022 npm run test:intnpm run deploy -- -c alertEmail=you@example.com && npm run smoke
The last line needs a CDK-bootstrapped account and the Anthropic first-time use form in the Bedrock console.
The first call to each model also starts its AWS Marketplace subscription. That needs
aws-marketplace:Subscribe , Unsubscribe and ViewSubscriptions , plus a payment method on the account. The gateway's role has none of them, so invoke each model once from the Bedrock console or as an admin before npm run smoke .
The smoke test checks a real call and a cache read on the second call. We haven't run it, so tell us what breaks.
Clean up
Run
npm run destroy -- -c alertEmail=you@example.com . The app needs the email on every CDK command. It removes the function, the budget table, the log group, the alarm, the topic and the monthly budget. In costTags mode, it also deletes the two application inference profiles.
Do you cap LLM spend per user before the call, or catch it afterwards in the bill? Tell us what your limit looks like.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article