
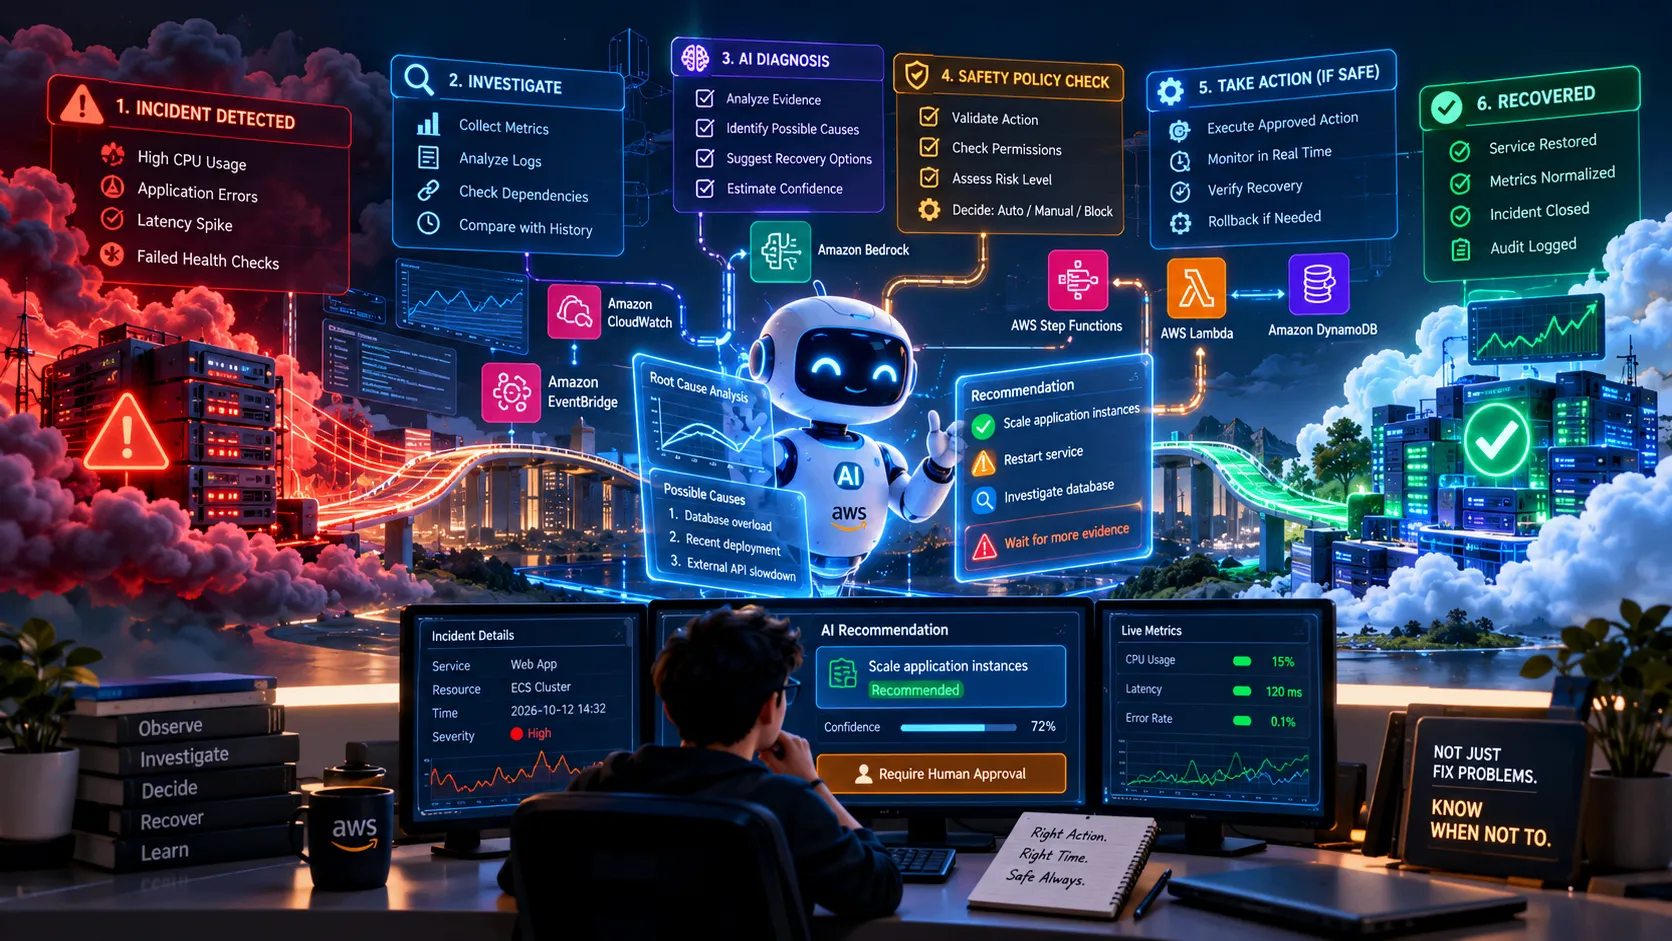
The AI That Knows When Not to Fix Your Cloud
Explore how to build a safety-aware AI recovery system on AWS that detects cloud failures, investigates root causes, recommends evidence-based solutions, and automates approved recovery actions while enforcing security policies, human oversight, and post-recovery verification.
9. Verifying Recovery Instead of Assuming Success
One of the most important mistakes in automated incident response is assuming that an action succeeded simply because the API returned a successful response.
Suppose the system restarts an application instance. The restart operation may complete successfully, but the application could still be unhealthy because its database remains unavailable. A reliable recovery system must therefore verify the outcome independently.
After an action executes, the workflow should monitor relevant health checks, application error rates, latency, and dependency status. The verification stage should compare these observations against predefined recovery criteria.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
Recovery Action Executed
          |
          v
Check Resource Status
          |
          v
Evaluate Application Health
          |
     +----+----+
     |         |
   Healthy   Unhealthy
     |         |
     v         v
 Close Case   Stop Repeated Actions
     |         |
     v         v
 Record       Escalate to
 Success      Human Operator
If the system cannot confirm recovery within the configured time limit, it should record the failure and escalate the incident. It should not repeatedly execute the same action without checking whether the situation has changed.
A recovery action should also have a defined verification window and a clear rollback or containment strategy where appropriate. The verification process is what distinguishes a controlled recovery workflow from a script that merely executes commands.
10. Maintaining an Audit Trail with Amazon DynamoDB
Every investigation should produce a record of what happened and why.
Amazon DynamoDB can store structured incident metadata, workflow state, approval decisions, and recovery outcomes. For each incident, the system can record the incident identifier, affected resource, relevant metric references, model version, diagnosis, evidence references, proposed action, policy decision, approval identity, execution result, and verification outcome.
The incident lifecycle might include states such as
DETECTED, INVESTIGATING, PENDING_APPROVAL, APPROVED, EXECUTING, VERIFIED, REJECTED, and ESCALATED.State transitions should be validated so that an incident cannot move directly from detection to execution without satisfying the required controls. DynamoDB conditional writes can help enforce expected state transitions and prevent conflicting updates.
For stronger auditability, the design should also consider retaining detailed execution logs and approval records in a suitably protected storage system. Access controls, retention policies, and monitoring should prevent unauthorized modification or deletion of important records.
This audit trail provides value beyond compliance. It allows engineers to investigate failed recoveries, compare recommendations with actual outcomes, identify recurring incidents, and improve future policies.
11. Security and Least-Privilege Access
An AI recovery agent introduces additional security considerations because its recommendations may eventually lead to infrastructure modifications.
The first requirement is to give each component only the permissions it needs. A diagnostic Lambda function should generally have read-only access to the resources it investigates. An execution function should have permission to perform only explicitly approved operations on the intended resources.
For example, a function responsible for restarting a particular application service should not automatically receive unrestricted access to terminate instances, delete databases, or modify IAM policies.
Other important controls include protecting credentials, encrypting sensitive data, restricting access to logs, validating all action parameters, and separating development and production environments.
The AI model should not receive unrestricted shell access or arbitrary AWS credentials. Instead, it should return a structured recommendation that passes through an independently enforced authorization layer.
A useful security boundary is:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
AI Model
   |
   v
Structured Recommendation
   |
   v
Application Validation
   |
   v
Policy and Authorization Checks
   |
   v
Restricted Execution Function
   |
   v
AWS Resource
The execution layer should reject malformed requests, unknown actions, unauthorized targets, and operations that exceed predefined limits. These checks must remain effective even when the model produces an incorrect or manipulated recommendation.
12. Evaluating the System
A successful demonstration should prove that the system can recover from appropriate failures while refusing unsafe operations.
Testing should cover several scenarios. First, simulate a recoverable application health-check failure and verify that the system identifies the affected resource, recommends an allowed action, executes it under the configured policy, and confirms that health has been restored.
Second, simulate a dependency failure in which restarting the application would not solve the underlying issue. The expected behavior is to investigate the dependency and avoid repeatedly restarting the application.
Third, provide incomplete diagnostic information. The system should identify the missing evidence and escalate the case instead of inventing a root cause.
Fourth, test a high-impact action without approval. The expected result is that the operation remains blocked.
Finally, test repeated events, workflow timeouts, failed recovery attempts, stale approvals, and duplicate execution requests.
The following table summarizes useful evaluation measures.
| Metric | What it measures |
|---|---|
| Diagnosis accuracy | Whether identified causes match verified incident evidence |
| Recovery success rate | Percentage of eligible recovery attempts that restore service |
| Mean time to recovery | Time from incident detection to verified recovery |
| False action rate | Frequency of unnecessary or inappropriate actions |
| Escalation rate | Percentage of incidents requiring human intervention |
| Policy violation rate | Frequency of attempts to bypass configured safety rules |
| Duplicate execution rate | Frequency of repeated execution of the same intended action |
These metrics should be measured during controlled experiments and compared with an appropriate baseline, such as the existing manual or rule-based recovery process.
A particularly important measure is the false action rate. Faster recovery is not an improvement if the system achieves it by executing unnecessary or dangerous operations.
The goal is to improve recovery efficiency without compromising reliability or control.
13. Cost Considerations
The cost of the system depends on the volume of monitoring events, diagnostic operations, model requests, workflow transitions, data retention, and recovery activity.
Amazon CloudWatch generates costs depending on the metrics, logs, alarms, and other features used. Amazon Bedrock costs depend on the selected model and its usage-based pricing. AWS Lambda and AWS Step Functions also have pricing models tied to their respective usage. Amazon DynamoDB costs depend on the selected capacity or request mode, storage, and additional features.
A prototype can keep costs manageable by using a small test environment, limiting model calls, collecting only necessary diagnostic context, and avoiding unnecessary execution of long-running workflows.
The system should also avoid invoking a language model for every routine metric update. Deterministic monitoring and simple rules can filter events first, reserving AI-assisted diagnosis for incidents where additional interpretation is useful.
A cost-aware architecture uses AI where it adds value while relying on ordinary application logic for repetitive validation, authorization, and state management.
14. Future Improvements
The architecture can be extended into a more advanced cloud operations platform.
One improvement is to incorporate historical incident knowledge so that the system can retrieve previous failures, their verified causes, and the recovery procedures that successfully resolved them. Another is to add automated anomaly detection over infrastructure metrics to identify unusual behavior before conventional thresholds are exceeded.
The system could also support controlled canary recovery, in which a proposed change is applied to a limited environment before wider deployment. Where appropriate, it could integrate deployment metadata and infrastructure configuration information to improve diagnostic context.
A further improvement is to evaluate multiple possible recovery strategies against predefined safety and operational constraints. Rather than automatically choosing the first recommendation, the system could compare available options and present the expected benefits, risks, and uncertainties to an authorized operator.
However, increasing autonomy should not mean removing safeguards. Every additional capability should have explicit permissions, measurable success criteria, failure handling, and a way to stop or reverse its operation when appropriate.
Conclusion
Building an AI system that can repair cloud infrastructure is not simply a matter of connecting a language model to AWS APIs. The difficult problem is deciding when an action is justified, ensuring that the action is authorized, and verifying that it actually resolves the incident.
By combining Amazon CloudWatch, Amazon EventBridge, AWS Lambda, AWS Step Functions, Amazon Bedrock, and Amazon DynamoDB, engineers can design a cloud recovery workflow that separates monitoring, diagnosis, decision-making, execution, and auditing.
The key design principle is that AI-generated recommendations should never become infrastructure changes without appropriate validation. Verified evidence should support the diagnosis, deterministic policies should govern the permitted actions, and human approval should remain available for high-impact or uncertain situations.
A mature system should also recognize that not every incident can be solved automatically. Sometimes the safest response is to collect more evidence, stop a potentially harmful operation, or escalate the problem to an experienced engineer.
The future of cloud operations is not necessarily a cloud in which AI fixes everything. It is a cloud in which automation can act confidently within defined boundaries, explain its decisions, verify its results, and recognize the limits of its own knowledge.
The most reliable AI recovery system is not the one that takes the most actions. It is the one that knows which actions are justified, which actions require permission, and when doing nothing is the safest decision.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article