
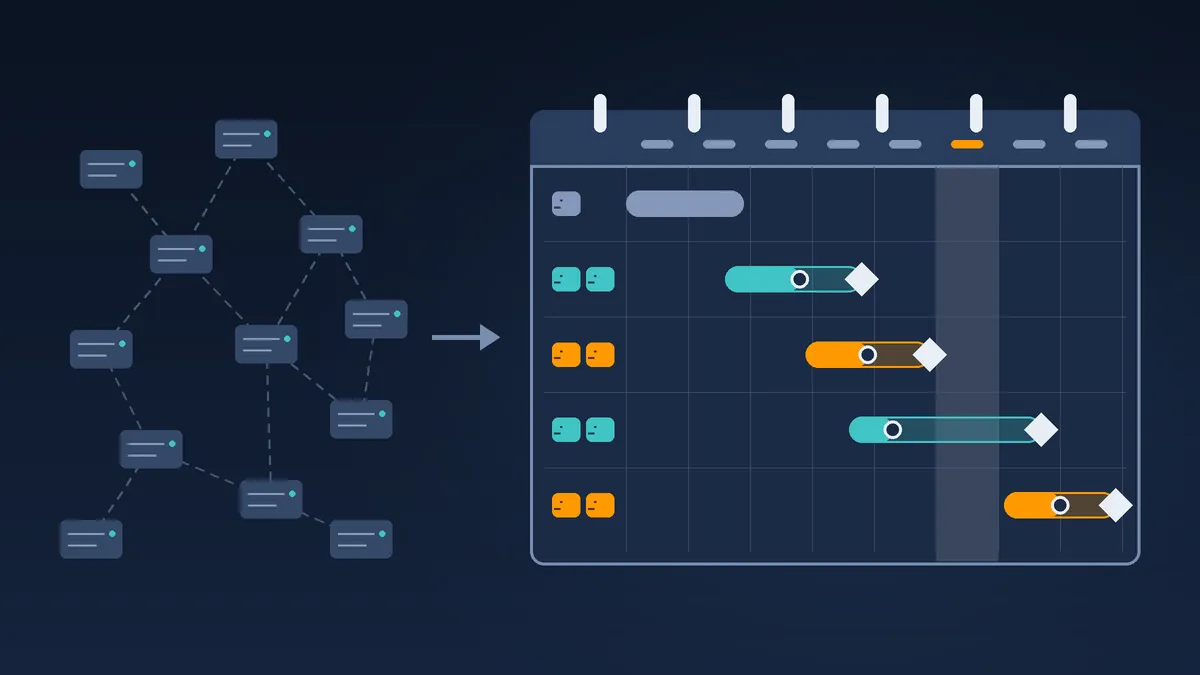
Wave planning when nobody can tell you what talks to what
How I build a migration wave plan on AWS Transform MGN without a dependency map: sprint zero, bandwidth arithmetic, application owner availability, DR as a parallel track, and test cutovers two weeks ahead of the real one.
Cloud Architect - AWS migrations, disaster recovery and VMware security hardening
Wave planning when nobody can tell you what talks to what
What this article covers
This is a guide to planning migration waves for a rehost (lift and shift) of on-premises servers to AWS. It is for the architect or migration lead who has to produce a cutover schedule for tens or hundreds of servers and has no reliable dependency map to build it from.
The replication service is AWS Transform MGN. It was called AWS Application Migration Service until June 2026, and the rename did not change how any of this works. I call it MGN in the rest of the article.
The terms I use:
- Wave. A group of applications that cut over together in one window.
- Application. A group of source servers that only work together, such as a web tier, an app tier and a database.
- Test cutover. Launching the replicated servers in AWS in an isolated subnet while the source keeps running.
- Cutover. Stopping the source, launching the final instances in AWS and pointing users at them.
- UAT. The application owner confirming that the application works after a test or a cutover.
How MGN works, in the detail that matters for planning:
- You install the AWS Replication Agent on each source server. The agent needs outbound TCP 443 to the MGN endpoint and TCP 1500 to the replication servers.
- The agent copies every disk at block level to a staging area subnet in the target account. This initial sync takes days for a large wave and is limited by bandwidth.
- After the initial sync, replication is continuous. Changes on the source reach AWS with a lag of seconds to minutes.
- Each source server moves through a lifecycle: Not ready, Ready for testing, Test in progress, Ready for cutover, Cutover in progress, Cutover complete.
- You launch test instances, validate, mark the server as ready for cutover, then launch cutover instances in the cutover window.
MGN moves the servers. It does not tell you which servers belong together, in what order they should go, or who has to be awake when they do. That is the wave plan, and the rest of this article is how I build one: sprint numbering, the three constraints that set dates, grouping, DR, test cutovers, replication checkpoints, UAT, and the spreadsheet that holds it together.
Where every plan starts
The first wave should be small and boring. That is easy to agree with and hard to do, because the customer wants the important thing moved first, and the important thing is usually the one with the most dependencies nobody has written down.
Every large migration I have worked on has started from the same position: there is no CMDB, or there is one and it is three years stale, which is worse because people trust it. The dependency map you need does not exist and will not exist in time. Wave planning is the discipline of building a schedule anyway, and then being honest about which parts of it are arithmetic and which are guesses.
Sprint zero is not wave one
Number your sprints from zero.
Sprint 0 is discovery, landing zone build, and the security posture work that has to exist before a single server replicates. It produces no migrated workloads. If you number it Sprint 1, the first status report shows a sprint completed with nothing migrated, and you spend the next meeting explaining why that is fine instead of talking about the plan.
Numbering from zero makes the plan readable to anyone who does not attend the standups. The platform gets built, then waves start.
The work that belongs in sprint zero, in the order it has to happen:
- Discovery and planning
- Security and compliance requirements
- Design discussion and finalization with the customer
- Landing zone security posture update
That fourth item is the one that slips. The landing zone gets built early, then the security review lands late and changes the guardrails, and every server already replicated into the account inherits a configuration that no longer matches the standard. Do the hardening before the first wave replicates, not in parallel with it.
Work backwards from three constraints
The planned cutover date is the obvious constraint. Everyone has it. These are the two people forget.
Available bandwidth. Replication is not instant. Initial sync for a wave is measured in days, and the total storage in a wave, plus how many waves you are replicating concurrently, decides whether your dates are real. This is arithmetic:
initial sync days = used storage in the wave (GB) x 8,000                    / usable bandwidth (Mbps)                    / 86,400
Example: 4,000 GB over 100 Mbps of usable bandwidth         = 32,000,000 Mb / 100 Mbps         = 320,000 seconds         = 3.7 days, before change rate and retries
You can compute it, and you should, before agreeing to anything.
Application owner availability. Somebody has to validate the application after cutover, and that person has a job. They are not assigned to your migration. They have a release of their own, or annual leave, or they are the only person who understands two systems and you have scheduled both in the same window.
Of the three, owner availability is the one that most often sets the real date. Bandwidth is arithmetic you can plan around. A person with a day job is not. That is the constraint I now solve for first, because it is the least elastic.
Put public holidays in the plan as a column
In every version of a wave plan I have built, public holidays sit in the sprint calendar as a first-class column, next to the sprint dates. Not as a note. Not as something checked at the end.
The reason is specific. A cutover weekend that collides with a public holiday costs more than a working day. It loses the application owner who is supposed to validate, and the customer-side approver who signs off, and often the third-party vendor support you were relying on if something does not come up. All three disappear at once, and you find out on the Friday.
Putting holidays in the calendar column means the collision is visible while dates are still being negotiated, which is the only time it is cheap to fix.
If the estate spans countries, this compounds. The holiday that matters is the one where the approver sits, not where the servers are.
Group by application, not by server
A wave is a set of applications, not a set of servers.
MGN supports this directly. You associate source servers with an Application, and applications with a Wave. That hierarchy exists because servers are not independently migratable. A wave built from servers that happen to be adjacent in a spreadsheet delivers nothing you can hand back to a user. A wave built from applications delivers something that works.
This is also why discovery output matters more than an inventory. An inventory tells you what exists. You need to know what breaks when a given box moves. In the absence of a dependency map, that knowledge lives with the application owners, which is another reason their availability binds so hard.
Where I have no dependency data at all, I group by what the owners tell me, then validate with a test cutover rather than trusting the grouping. The test cutover is the dependency map.
The rule that saves an application owner
Never put two sets of applications with the same owner in the same cutover window.
An owner who is asked to be in two places at 3am signs off on both and finds the problem on Monday.
Environment and criticality drive the same decision. Production servers need a defined cutover window, a rollback window, and an owner present. Test and UAT servers do not, which is what makes them good first-wave candidates. They let the team learn the process before anything depends on the rollback plan.
Plan DR as a parallel track
This is the structural point most plans get wrong, and it is expensive to correct.
Every application in a serious plan appears twice: once as a production workstream, and once as a matching DR workstream. Not "migrate everything, then build DR." The DR track is sized, sequenced, and cut over alongside production, wave by wave.
The reason is that DR design decisions are made during the migration, whether or not you acknowledge them. Which AMIs you take, whether the recovery site is pre-provisioned, what the identity path looks like from the DR network. Those get decided when you build the wave. If DR is a later phase, you re-open every wave you have already closed, and you make those decisions again with less context and a customer who considers the project finished.
Practically, the DR track for a wave looks like this: take AMIs of the production servers, launch servers in the DR site from those AMIs, and test the launch. That work sits in the same sprint as the production cutover for those applications.
It also changes your capacity arithmetic. A wave is N production servers plus M DR servers, and the replication bandwidth you need covers both. Sizing a wave on the production count alone is how a schedule that looked achievable stops being achievable in month three.
Complete the test cutover two weeks before the real one
Two weeks is the time it takes to find a problem, fix it at source, and let replication re-establish before the real cutover. Compress it to two days and a test failure becomes a cutover slip, because you no longer have room to re-sync.
MGN supports this directly: launch test instances into a prepared subnet, verify, then mark the servers as ready for cutover. The test launch is also where you discover the boot-order assumption nobody documented, the licensing that is bound to a MAC address, and the agent that was installed but never actually replicating.
Fix at source, not in the target. A fix applied only to the launched test instance is a fix you will make again on cutover night, under time pressure, from memory.
Set replication checkpoints
Set checkpoints that monitor replication across a wave. Asking for status in a call does not catch a stalled server.
Replication drifts quietly. A server that stalled a week ago is discovered on the night nobody was watching lag. The failure mode is silent and the dashboard is green at the wave level while one server inside it has stopped.
Weekly is enough while a wave is replicating. Daily in the fortnight before a cutover, checking lag and lifecycle state per server rather than reading a wave summary.
Wire the stalled-state event to an alert rather than relying on someone opening the console. MGN publishes a
MGN Source Server Data Replication Stalled Change event to Amazon EventBridge. An EventBridge rule on that detail type with an Amazon SNS topic as the target is enough:{ "source": ["aws.mgn"], "detail-type": ["MGN Source Server Data Replication Stalled Change"]}The console will not tell you at 2am.
UAT is the step that repeats
In the plans I have built, customer UAT is the most frequent task in the entire schedule. More frequent than cutover itself.
Every wave carries a customer-validation step, and it is the step most likely to run twice, because validation finds something, it gets fixed, and validation runs again. Cutover happens once per wave if it goes well. UAT happens as many times as it needs to.
Plan for it as a repeating step with owner time attached. A plan that budgets one UAT pass per wave is a plan that slips the first time someone finds a defect.
Documentation and project signoff get the same treatment. They are scheduled tasks with their own rows and their own capacity.
The spreadsheet
Every migration I have seen runs on one, whatever tooling sits underneath.
At minimum it carries these columns:
Column | Why it is there |
|---|---|
Server | The unit that replicates |
Application | The unit that migrates |
Environment | Decides whether a rollback window is needed |
Owner | The person whose calendar sets the date |
Wave | The cutover group |
Replication state | Checked per server at every checkpoint |
Sprint dates and public holidays | Makes collisions visible while dates are negotiable |
Production and DR server counts per wave | The real replication load |
When there is no CMDB, this document becomes the CMDB, and it is usually the most accurate record the customer has ever had of their own estate.
The plan should make the two things that actually bind, bandwidth arithmetic and owner availability, visible on the same screen.
For a large estate
Above roughly a dozen servers per wave, configuring launch templates by hand in the console stops being reasonable. It is an afternoon of clicking with no audit trail, and no way to prove afterwards what a given server was configured with.
There are three documented ways out:
- Set an account-level default launch template.
- Script the copying of settings between servers.
- Use the MGN import and export feature to load source servers, applications, waves and launch template attributes from a CSV built during discovery.
The third is the one I use, because discovery data becomes launch configuration without being re-typed. I build that CSV in the same spreadsheet the wave plan lives in, which means the plan and the configuration cannot drift apart.
For the scripted paths I use Ansible and shell, driven from the same inventory. Any tool works as long as the configuration is derived from a record you can inspect afterwards, rather than from what someone remembered to click.
Cadence
Two-week sprints track a wave through test and cutover inside a single sprint. Four-week sprints batch more waves per sprint and report less often.
Both work. The trade-off is reporting frequency against ceremony overhead, and it is worth deciding deliberately rather than inheriting whatever the customer's delivery team already runs. On a program with 14 sprints, the difference compounds into a materially different number of checkpoints.
What actually decides it
Bandwidth and dependencies decide what can be in a wave. Owner availability decides what should be.
Most plans I have seen fail on the second.
The first wave should be small and boring because it is where the team learns the process: the handover between whoever runs replication and whoever validates the application, the escalation path at 3am, how long the customer's approval actually takes as opposed to how long it is supposed to take. Learn that on something that does not matter.
Then the second wave is where you find out whether the plan is real.
If you have run a large migration, I would be interested in which constraint set your schedule.
References
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article