
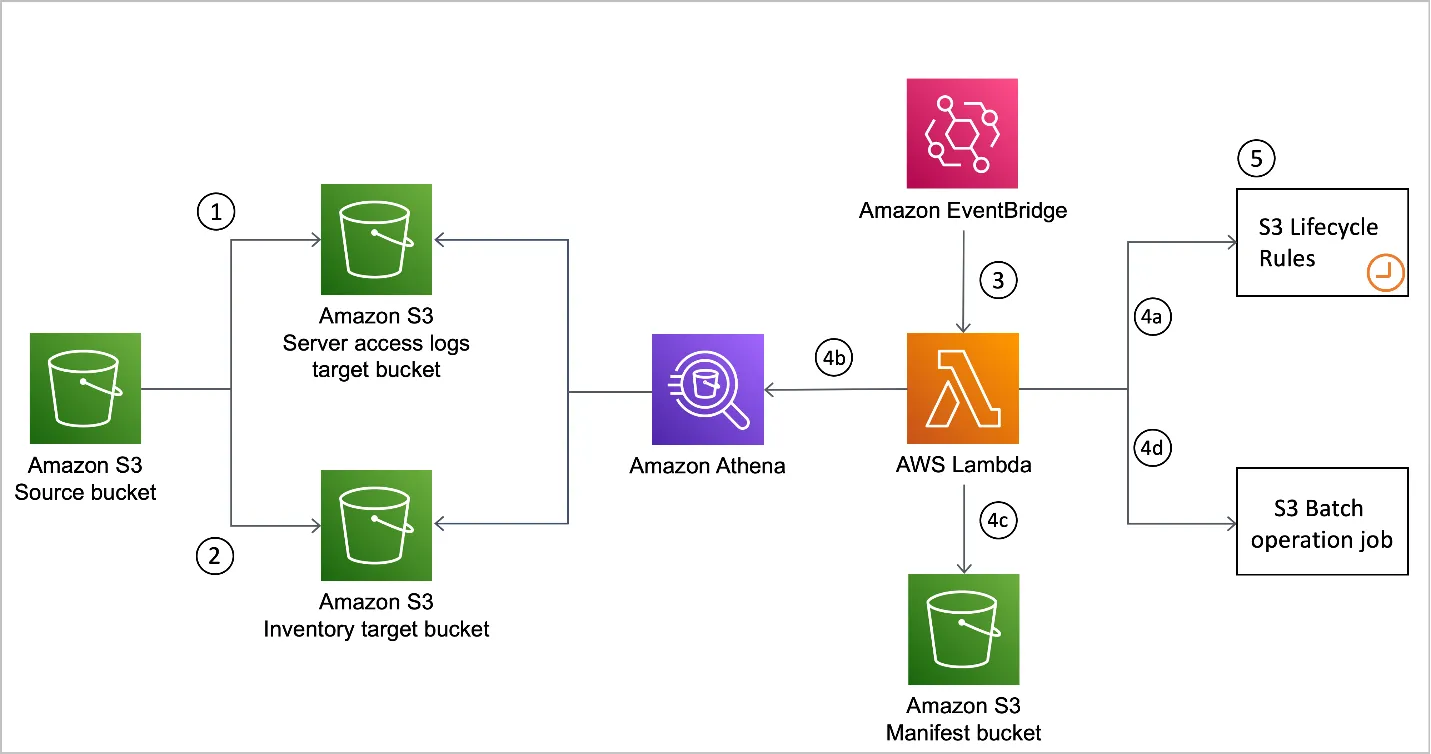
What Actually Happens When You Upload a File to Amazon S3?
Have you ever wondered what actually happens when you upload a file to Amazon S3?
You select a file.
You click Upload.
A few seconds later, the file is available.
But behind that simple action, several cloud concepts are involved.
Let's break it down.
1. Your File Becomes an Object
Amazon S3 is an object storage service.
When you upload a file, S3 stores it as an object.
An object consists of:
- The actual data
- Metadata
- A unique key
For example, suppose you upload:
1
sales_report.csv
Your S3 object might look conceptually like:
1
2
3
Bucket: company-data
Key: reports/2026/sales_report.csv
Data: sales_report.csv
The key acts like the object's identifier inside the bucket.
2. The Object Lives Inside a Bucket
Before storing objects, you create an S3 bucket.
Think of a bucket as a container for objects.
For example:
1
2
3
4
5
6
7
8
9
10
11
12
company-data
│
├── reports/
│   ├── sales.csv
│   └── customers.csv
│
├── images/
│   ├── product1.jpg
│   └── product2.jpg
│
└── backups/
    └── database.zip
The bucket is not simply a traditional folder on your computer.
S3 uses an object-storage model.
3. What Happens During Upload?
A simplified flow looks like this:
1
2
3
4
5
6
7
8
9
Your Computer
      ↓
   Internet
      ↓
   Amazon S3
      ↓
    Bucket
      ↓
    Object
Your application or AWS console sends an HTTP request to Amazon S3.
S3 receives the request, verifies whether you have permission to perform the operation, and stores the object.
4. IAM Decides Whether You're Allowed
This is where AWS security becomes important.
Suppose your application tries to upload:
1
sales.csv
AWS needs to determine:
"Is this user or application allowed to upload this object?"
IAM policies can control access to AWS resources.
For example, an application might have permission to:
1
s3:PutObject
This allows it to upload objects to a specified location.
But another user might only have permission to read objects.
So authentication and authorization are separate concepts:
Authentication: Who are you?
Authorization: What are you allowed to do?
5. S3 Doesn't Just Store Your File
S3 provides several capabilities around your objects.
Versioning
If versioning is enabled and you replace:
1
report.csv
S3 can retain previous versions.
This can help protect against accidental deletion or overwriting.
Lifecycle Policies
You might not need every file in the same storage class forever.
For example:
1
2
3
4
5
6
7
8
9
10
11
Day 0
 ↓
S3 Standard

After 30 days
 ↓
Infrequent Access

After 180 days
 ↓
Archive
Lifecycle rules can automatically transition objects between storage classes according to your requirements.
6. What About Durability?
One of the major reasons organizations use S3 is its extremely high durability design.
AWS is designed to protect S3 data against infrastructure failures by redundantly storing data across multiple devices and facilities within an AWS Region.
This doesn't mean you should ignore backups or access controls.
Durability and backup are not the same thing.
That's an important distinction.
7. S3 Is Not a Database
This is a common beginner mistake.
Suppose you have:
1
2
3
4
5
customer_id
name
email
salary
department
You might think:
"I'll just put everything into S3."
You can store the data there, but S3 itself isn't a relational database.
For structured transactional workloads, services such as Amazon RDS may be more appropriate.
S3 is excellent for storing objects such as:
- CSV files
- Images
- Videos
- Logs
- Backups
- Documents
- Data-lake files
8. S3 Can Become the Starting Point of a Data Pipeline
This is where S3 gets really interesting for data engineers.
Imagine a company receives thousands of CSV files every day.
A simplified architecture could be:
1
2
3
4
5
6
7
8
9
Data Sources
     ↓
   Amazon S3
     ↓
 AWS Glue
     ↓
 Amazon Athena
     ↓
 Analytics / Dashboard
S3 becomes the storage layer for raw data.
AWS Glue can help discover and transform the data.
Athena can query data stored in S3 using SQL.
This is one reason S3 is so common in data engineering architectures.
9. S3 + Lambda = Event-Driven Architecture
You can also trigger actions when objects are created.
For example:
1
2
3
4
5
6
7
8
9
User uploads CSV
       ↓
      S3
       ↓
   S3 Event
       ↓
     Lambda
       ↓
Process the CSV
The Lambda function could:
- Validate the file
- Transform the data
- Extract information
- Move the processed file
- Trigger another workflow
This allows applications to react automatically to new data.
A Simple Real-World Example
Imagine a college receives student documents through a website.
The architecture could look like:
1
2
3
4
5
6
7
8
9
Student
   ↓
Website
   ↓
Backend API
   ↓
Amazon S3
   ↓
Student Documents
The backend doesn't need to store every PDF directly on its application server.
Instead, S3 can handle object storage while the application manages the business logic and metadata.
The Bigger Picture
S3 looks simple from the outside:
Upload → Store → Download
But once you combine it with other AWS services, it becomes a fundamental building block for:
- Data lakes
- Backup systems
- Static websites
- Analytics pipelines
- Machine learning workflows
- Event-driven applications
- Application asset storage
That's the real value of understanding AWS.
Don't just memorize:
S3 = Storage
Understand the bigger question:
"Where does S3 fit into an actual architecture?"
Once you start thinking that way, AWS becomes much easier to understand.
What AWS service should I explain next — EC2, Lambda, VPC, RDS, or IAM?
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article