
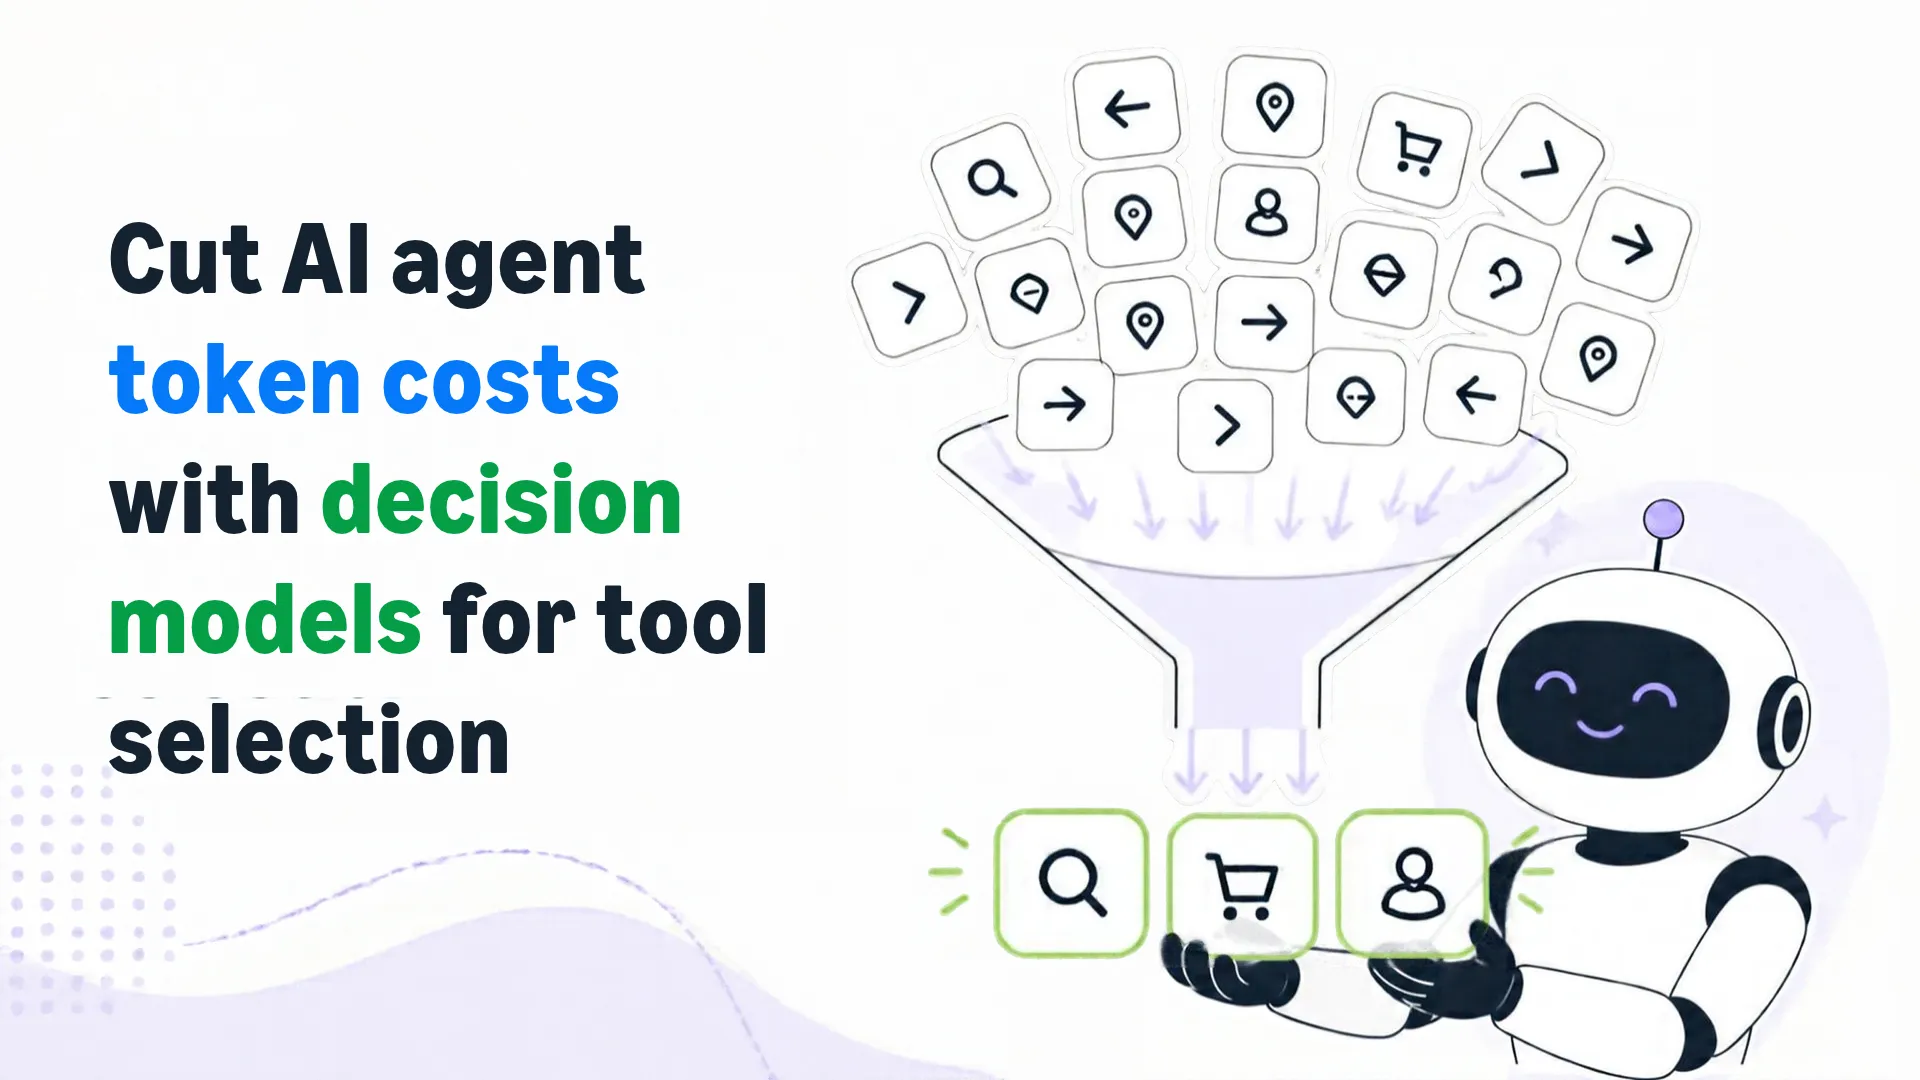
Cut AI agent token costs with decision models for tool selection
Give an AI agent a real toolset (25, 40, more) and every call pays for it. The agent reads every tool description to use one, so input tokens grow with each tool you add. And with many similar tools in view, the model picks the wrong one more often. Two costs on every turn: tokens you did not need to spend, and picks you did not want. Giving the agent fewer tools is not the fix, because different turns need different tools.
Series: Resilient Harness (7 articles)
- …
- 7Cut AI agent token costs with decision models for tool selection This article
Give an AI agent a real toolset (25, 40, more) and every call pays for it. The agent reads every tool description to use one, so input tokens grow with each tool you add. And with many similar tools in view (
search, search_hotels, search_flights...), the model picks the wrong one more often. Two costs on every turn: tokens you did not need to spend, and picks you did not want. Giving the agent fewer tools is not the fix, because different turns need different tools. You want the full toolset available but only the relevant few in front of the model each turn.In an earlier post I solved this with semantic tool selection over a vector store: embed every tool description into an index (FAISS), embed the query, and keep the nearest few. It works, and that walkthrough covers it in depth. But it has a cost of its own: you maintain an embedding index for your tools, every query pays an embedding call, and the index has to stay in sync as tools change.

A new class of model changes this. A decision model reads the request and the list of tools and returns a calibrated choice directly, with no embeddings and no index. It generates no text, so there is nothing to parse, and the choice comes with a confidence score. Two have arrived recently: Strands Decider , an open-source 2B model that runs locally, and Jev (TypeSafe), a hosted one; and the OpenAI Decisions API (
vector store entirely. You get the token and accuracy win of tool selection without building or maintaining an index. Both answer the same bounded question, which tool fits this request?, and both skip the vector store entirely. You get the token and accuracy win of tool selection without building or maintaining an index.
gpt-6-luna, public beta since Oct 2026), also hosted. All three answer the same bounded question, which tool fits this request?, and all three skip thevector store entirely. You get the token and accuracy win of tool selection without building or maintaining an index. Both answer the same bounded question, which tool fits this request?, and both skip the vector store entirely. You get the token and accuracy win of tool selection without building or maintaining an index.

How Strands fits in
Strands lets you plug any of these in the same way, through a hook that runs before the model and swaps the agent's tools for the turn. The selector inside the hook can be the vector store or a decision model, and the same idea extends to model routing, choosing which model serves the request.
1
2
3
4
5
6
7
8
9
class ToolFilterHook(HookProvider):
    def register_hooks(self, registry):
        registry.add_callback(BeforeModelCallEvent, self.filter)

    async def filter(self, event):
        tools = await self.select(query)      # vector, decider, or Jev
        swap(event.agent, tools)              # the model now sees only these

agent = Agent(tools=ALL_TOOLS, hooks=[ToolFilterHook(select)])
The agent is built once with every tool; the hook trims the registry per request. This is where Strands earns its place: it swaps tools on the live agent at runtime, so the conversation survives. Frameworks that force you to rebuild the agent to change its tools lose that history. Here you keep the memory, and you switch strategy by swapping
select in one line.The swap itself is a few lines against the agent's tool registry. Clear it and register the chosen tools; the running agent and its message history stay intact:
1
2
3
4
5
6
7
def swap(agent, tools):
    reg = agent.tool_registry
    reg.registry.clear()          # drop the previous turn's tools
    reg.dynamic_tools.clear()
    for t in tools:               # register only the ones picked this turn
        reg.register_tool(t)
    # agent.messages is untouched — the conversation is preserved
Keeping the live conversation is memory within a session. For memory that lasts across sessions, Strands has a dedicated memory library : pluggable memory stores on a unified storage interface. You attach a store, a local file store for prototyping or Amazon Bedrock Knowledge Bases with semantic search for production (or your own backend), and the agent gets recall, automatic injection into the prompt, and extraction of new memories. So the hook keeps this turn's context, and the memory store carries durable knowledge between runs.
Model routing
The hook decides which tools. Strands model routing decides which model. Give a
ModelRouter a few candidates and a strategy; the strategy picks one per request. A decision model fits this role well: it chooses the model with a calibrated vote instead of a chat call. Either decision model works as the strategy. The example below uses Jev (hosted), which is the one in the demo; Strands Decider (local) plugs into the same RoutingStrategy interface the same way, so you pick based on whether you want a hosted call or a local model.1
2
router = ModelRouter(models=[small, large], strategy=JevRoutingStrategy())
agent = Agent(model=router)
Same shape as the tool hook: a cheap decision in front, the expensive model only when it is needed.
The comparison
Same 12 queries, same ~25-tool pool, one demo run (AWS Bedrock Claude Haiku as the agent):
| Approach | Accuracy | Chat tokens | Latency (end to end) |
|---|---|---|---|
| Send all tools | 10 / 12 | ~56k | ~1.1s, fastest |
| Hook + vector | 11 / 12 | ~20k | ~1.8s (+ an embedding call) |
| Hook + decision model | 11 / 12 | ~16k | ~2.3s (+ a decision call) |
Both selectors reach the same accuracy and cut chat tokens by about two-thirds. But each adds a call before the model: vector embeds the query (and pays embedding tokens), the decision model runs one choice, so here they are slower end to end, not faster. At 25 tools, sending everything is the quickest.
That ordering flips as the toolset grows. The model's prefill (reading the prompt before it answers) scales worse than linearly with input length, so a bigger pile of tool descriptions makes every call slower, and an agent makes many calls. Past some tool count the baseline's growing prefill overtakes the fixed cost of one selection step, and selecting first becomes the faster path, not just the cheaper one. So the real takeaway is not a fixed latency winner; it is that you spend a small, constant selection cost to keep the prompt, the token bill, and the prefill small, and that pays off more as you add tools.

Where the delay is
Follow the request through the pipeline and you can see exactly where each approach spends time:
- Send all tools: one step, the model call. No selection, so nothing extra, but the model reads all ~25 tool descriptions.
- Hook + vector: three steps before the answer: embed the query (a network call to the embedding model), search the index (local, microseconds), then the model call. The added delay is the embedding round-trip.
- Hook + decision model: two steps before the answer: the decision (local inference for Strands Decider, or a network call for Jev), then the model call. The added delay is that one decision.
So the extra latency lives in the selection step, before the model runs. The model call itself is cheaper afterwards (a short tool list), but not cheap enough at this scale to beat skipping selection entirely.
They are not exclusive. The hook makes them interchangeable in one line.
A quick selection benchmark
Measuring only the pick, which tool each selector returns, over 20 labelled
queries against a ~25-tool pool (warm, single run on 2026-10-07):
queries against a ~25-tool pool (warm, single run on 2026-10-07):
| Selector | Accuracy | Mean | p50 | Cost |
|---|---|---|---|---|
| Vector (FAISS/Titan) | 95% | 155 ms | 144 ms | — (embedding call) |
| Jev (hosted) | 100% | 210 ms | 200 ms | — |
OpenAI Decisions (gpt-6-luna) | 100% | 275 ms | 258 ms | $0.054 / 1k picks (538 input tok each) |
Small set, one run — treat it as an early signal, not a verdict. Both decision
models matched the right tool on every query here; vector missed one. (This is
the selection step in isolation; the end-to-end table above measures a
different 12-query run including the agent's answer.)
models matched the right tool on every query here; vector missed one. (This is
the selection step in isolation; the end-to-end table above measures a
different 12-query run including the agent's answer.)
Which selector should I use?
- Already embedding things? Vector is the smallest add.
- Want a calibrated pick and no index? A decision model.
- Run a small model locally? Strands Decider 2B. Prefer a managed endpoint? Jev.
They are not exclusive. The hook makes them interchangeable in one line.
Try it
All of this runs in the open-source demo (Demo 02), why-agents-fail-sample-for-amazon-agentcore . It has
chat.py (vector), chat_decider.py (decision model), model_routing_with_jev.py (model routing), and a notebook that measures accuracy and tokens for each.FAQ
Does trimming tools hurt accuracy? No. In the demo it raised accuracy, because fewer similar tools means less confusion. The risk is dropping the right tool; tune how many you keep.
Why a hook instead of rebuilding the agent? Rebuilding loses the conversation. The hook changes the tools on the live agent, so memory survives and you switch strategy in one line.
Does a decision model save tokens? It sends fewer tool descriptions to the agent and generates no text itself. It is a separate, cheap call, not a chat turn.
Is this tied to Strands? The idea (filter before the model) is general. Strands makes it first-class: hooks, the tool-registry swap, and model routing are built in.
Series: Resilient Harness (7 articles)
- …
- 7Cut AI agent token costs with decision models for tool selection This article
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article