
Your RAG Chatbot Is Only as Smart as Its Search 🔎
Building a RAG chatbot is more than connecting an LLM to your documents. This practical guide explores how Amazon Bedrock Knowledge Bases can power a serverless RAG workflow and why chunking, retrieval quality, reranking, and cost matter. See how S3, Lambda, API Gateway, Bedrock, embeddings, and vector stores come together to build smarter, scalable AI applications.
Building a Serverless RAG Chatbot with
Amazon Bedrock Knowledge Bases 🤖☁️
RAG sounds simple:
Ask a question → Search documents → Generate an answer
But while building a RAG chatbot, I learned that the real challenge is not only choosing a good foundation model. Chunking, retrieval quality, architecture, and cost all matter.
🏗️ The Architecture
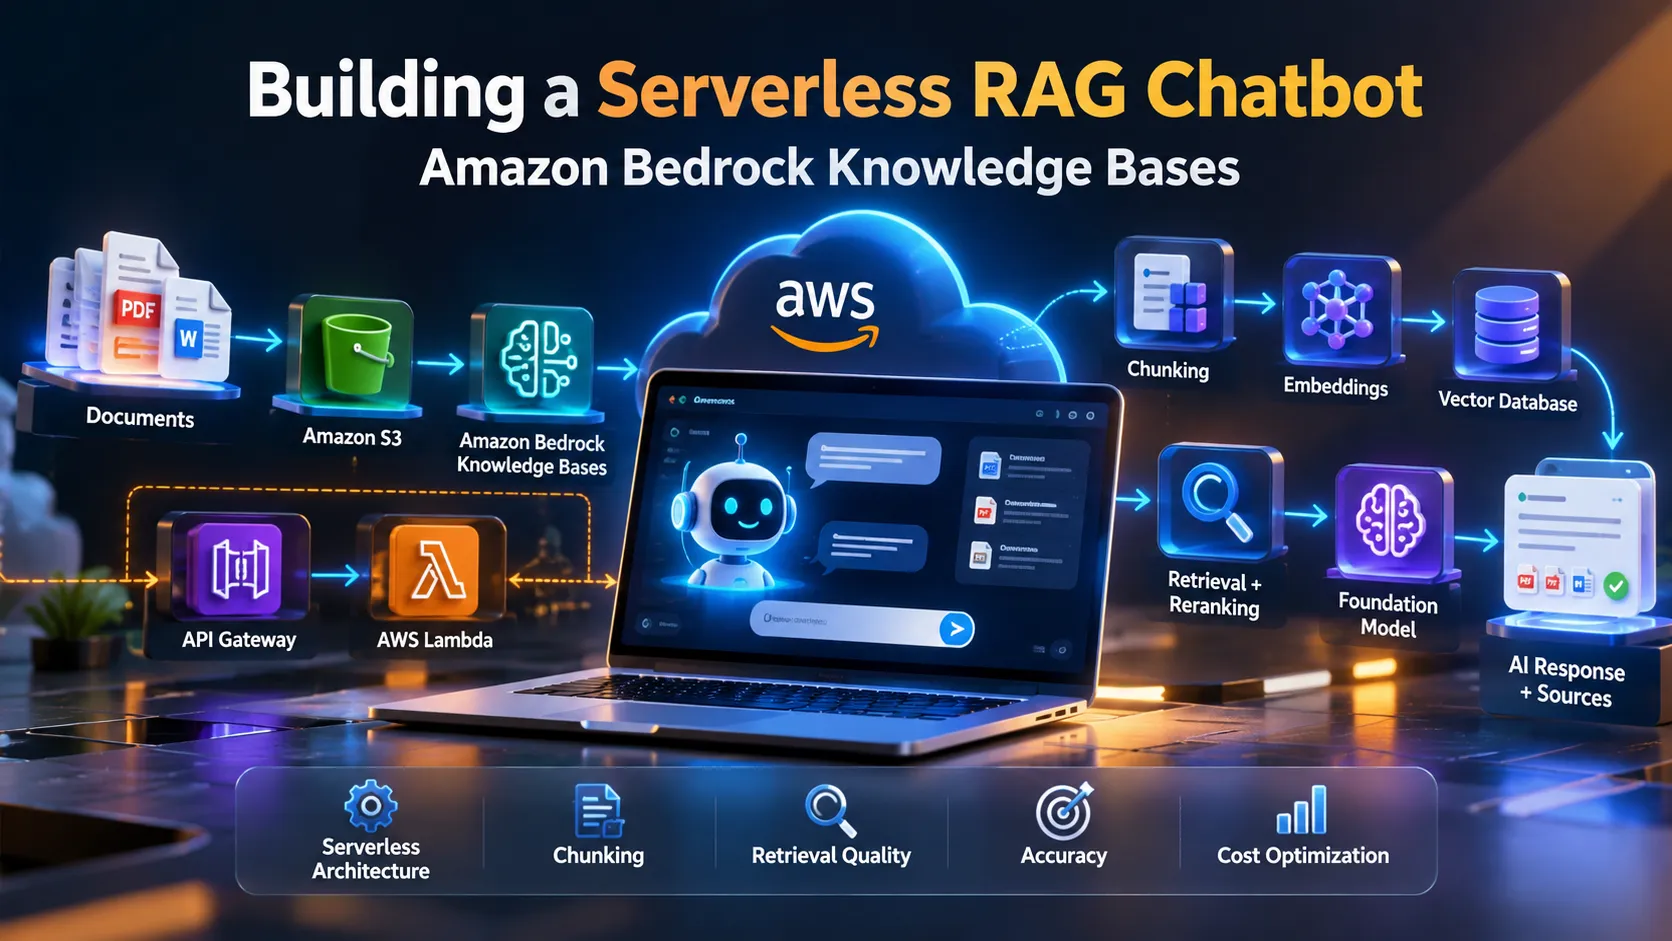
A simple serverless RAG workflow can look like:
User → API Gateway → AWS Lambda → Amazon Bedrock Knowledge Base → Foundation Model → Response
Documents can be stored in Amazon S3. During ingestion, Amazon Bedrock parses the documents, splits them into chunks, converts those chunks into embeddings, and stores the embeddings in a supported vector store. AWS Documentation
This means we can build a RAG application without manually implementing every part of the ingestion and retrieval pipeline.
🧩 1. Chunking Matters More Than I Expected
A large document cannot simply be sent to the model as one giant block. Bedrock splits the content into smaller chunks before creating embeddings.
Depending on the data, you can use strategies such as:
- Fixed-size chunking
- Hierarchical chunking
- Semantic chunking
The goal is simple: create chunks that contain enough context to be useful without becoming too large or mixing unrelated information. AWS Documentation
Poor chunks → poor retrieval → poor answers.
🔎 2. Retrieval Quality Controls Answer Quality
This was one of the biggest lessons.
Your foundation model might be excellent, but if the knowledge base retrieves the wrong chunks, the final response can still be weak.
Amazon Bedrock Knowledge Bases provides APIs such as Retrieve and RetrieveAndGenerate.
Retrieve lets you work directly with retrieved source chunks, while RetrieveAndGenerate combines retrieval with model generation and can provide citations to the source content. AWS Documentation You can also use reranking to reorder retrieved results based on relevance. This can help you pass fewer but more useful chunks to the generation model, potentially improving both quality and efficiency. AWS Documentation
💾 3. Your Data Source Matters
Amazon Bedrock Knowledge Bases can connect to different data sources, including Amazon S3, Confluence, Google Drive, Microsoft SharePoint, OneDrive, and web crawler sources, depending on supported configurations. AWS Documentation
For a beginner project, S3 is a simple starting point:
PDFs / Documents → S3 → Knowledge Base → Embeddings → Vector Store
This also makes it easy to update your knowledge base as documents change.
🧠 4. Don't Blame the LLM First
Suppose your chatbot answers:
“I couldn't find that information.”
The first instinct might be to change the foundation model.
But the actual problem could be:
Bad document → Bad chunk → Bad embedding → Poor retrieval → Weak answer
So when debugging a RAG system, I would check the pipeline from the beginning rather than immediately changing the model.
💰 5. Serverless Doesn't Mean Free
A serverless architecture means you don't manage traditional servers, but AWS services can still generate costs.
Your RAG application may involve:
S3 + Lambda + API Gateway + Bedrock + Embeddings + Vector Store + Monitoring
So I would always consider:
Accuracy ↔ Performance ↔ Cost
For example, increasing retrieval results or adding reranking should be based on whether it actually improves the application's results.
⚙️ 6. A Simple RAG Flow
The complete process can be visualized as:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
📄 Documents
     ↓
🪣 Amazon S3
     ↓
🔍 Bedrock Knowledge Base
     ↓
✂️ Chunking
     ↓
🧮 Embeddings
     ↓
🗄️ Vector Store
     ↓
❓ User Question
     ↓
🔎 Retrieval / Reranking
     ↓
🤖 Foundation Model
     ↓
💬 Final Answer + Sources
Amazon Bedrock currently supports multiple vector-store options, including Amazon OpenSearch Serverless, Aurora, Neptune, supported third-party stores, and Amazon S3 Vectors. AWS Documentation
🚀 What I Learned
Building a RAG chatbot changed how I think about AI applications.
Good RAG ≠ Just a Good LLM
It is closer to:
Good Data + Good Chunking + Good Retrieval + Good Model + Cost Awareness
The foundation model generates the response, but the quality of the context you retrieve determines what the model has to work with.
🎯 Final Thought
Amazon Bedrock Knowledge Bases makes it much easier to build managed RAG applications, but the real learning comes from understanding what happens before the model generates the answer. AWS Documentation
When your RAG chatbot gives a bad answer, don't immediately blame the model. Check the data, chunking, and retrieval first. 🤖
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article