
From Dataset to Deployment: A Beginner’s Guide to Building an AI/ML Project on AWS
Learn how to build a practical machine learning project on AWS, from storing your dataset to training, deploying, and monitoring a model. This beginner-friendly guide explains the workflow using AWS services and shows how students can turn a data science project into a cloud-based application.


Learn how to build a practical machine learning project on AWS, from storing your dataset to training, deploying, and monitoring a model. This beginner-friendly guide explains the workflow using AWS services and shows how students can turn a data science project into a cloud-based application.
From Dataset to Deployment: A Beginner’s Guide to Building an AI/ML Project on AWS
Artificial Intelligence and Machine Learning are no longer limited to research laboratories. Students and developers can now build, deploy, and scale machine learning applications using cloud platforms such as Amazon Web Services (AWS).
For students learning Data Science, one of the best ways to understand machine learning is to build an end-to-end project instead of only training models inside a Jupyter Notebook.
In this article, we will explore a beginner-friendly workflow for building an AI/ML project on AWS.
1. What Does an End-to-End ML Project Look Like?
A typical machine learning project consists of several stages:
- Collect the dataset
- Store the data
- Clean and preprocess the data
- Explore the dataset
- Train a machine learning model
- Evaluate the model
- Deploy the model
- Monitor the application
AWS provides services that can support different stages of this workflow.
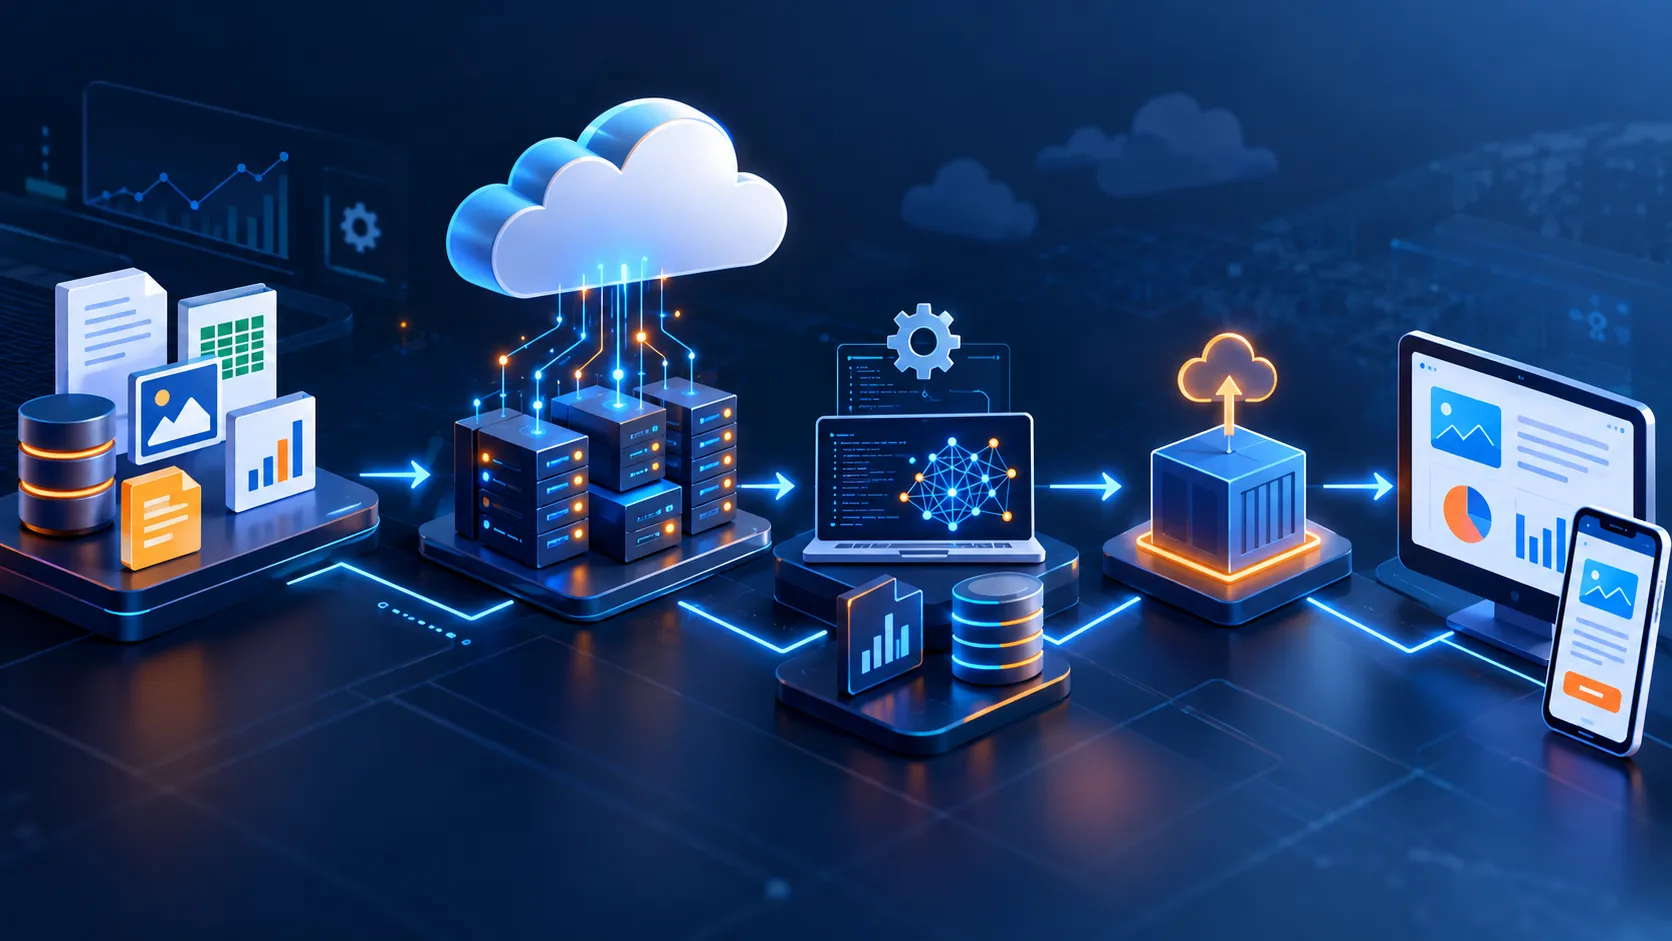
A simplified architecture can look like this:
Dataset → Amazon S3 → Data Processing → Model Training → Model Deployment → Application
The exact services can vary depending on the project requirements.
2. Store Your Dataset with Amazon S3
The first step is to store the dataset in a reliable location.
Amazon Simple Storage Service (Amazon S3) provides object storage that can be used to store datasets, trained models, images, CSV files, and other project resources.
For example, a project could have an S3 structure like:
1
2
3
4
5
6
7
8
9
my-ml-project/

│

├── data/

│   ├── train.csv

│   └── test.csv

│

├── models/

│

└── results/
3. Prepare and Explore the Data
Before training a model, data needs to be cleaned and analyzed.
Common tasks include:
- Handling missing values
- Removing duplicate records
- Detecting outliers
- Encoding categorical variables
- Scaling numerical features
- Splitting data into training and testing sets
Python libraries such as Pandas, NumPy, Matplotlib, and Scikit-learn are useful for these tasks.
For example:
import pandas as pd
df = pd.read_csv("train.csv")
print(df.head())
print(df.shape)
print(df.isnull().sum())
print(df.describe())
print(df.shape)
print(df.isnull().sum())
print(df.describe())
4. Train a Machine Learning Model
Once the data is prepared, we can train a machine learning model.
For example, a classification project could use algorithms such as:
- Logistic Regression
- Decision Tree
- Random Forest
- Support Vector Machine
A simple Scikit-learn example is:
from sklearn.model_selection import train_test_split
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score
X = df.drop("target", axis=1)
y = df["target"]
y = df["target"]
X_train, X_test, y_train, y_test = train_test_split(
X, y, test_size=0.2, random_state=42
)
X, y, test_size=0.2, random_state=42
)
model = RandomForestClassifier(random_state=42)
model.fit(X_train, y_train)
predictions = model.predict(X_test)
accuracy = accuracy_score(y_test, predictions)
print("Accuracy:", accuracy)
5. Use Amazon SageMaker for Machine Learning Workflows
Amazon SageMaker is designed to help developers and data scientists build, train, and deploy machine learning models.
A typical SageMaker workflow can include:
Prepare Data
↓
Upload Data to S3
↓
Build/Select ML Algorithm
↓
Train Model
↓
Evaluate Model
↓
Deploy Model
↓
Make Predictions
↓
Upload Data to S3
↓
Build/Select ML Algorithm
↓
Train Model
↓
Evaluate Model
↓
Deploy Model
↓
Make Predictions
6. Deploy the Model
Training a model is only one part of an AI/ML project.
The model becomes more useful when other applications can send data to it and receive predictions.
For example:
User
↓
Web Application
↓
API
↓
ML Model
↓
Prediction
↓
User
↓
Web Application
↓
API
↓
ML Model
↓
Prediction
↓
User
7. Build a Real-World Student Project
Students can apply this workflow to many practical problems.
Some examples include:
Student Performance Prediction
Input:
- Attendance
- Previous marks
- Assignment scores
- Study hours
Output:
- Predicted performance category
Crop Disease Detection
Input:
- Plant leaf image
Output:
- Predicted disease
Customer Churn Prediction
Input:
- Customer activity
- Subscription information
- Usage statistics
Output:
- Churn prediction
House Price Prediction
Input:
- Location
- Area
- Number of rooms
- Property features
Output:
- Estimated price
The important point is not simply achieving high model accuracy. A strong project should demonstrate the complete process from data collection to deployment.
8. Monitor the Application
After deployment, an ML application should be monitored.
Monitoring helps identify problems such as:
- Application errors
- Unexpected traffic
- Performance issues
- Changes in prediction behavior
AWS provides monitoring and logging services that can help developers understand how their applications are behaving.
9. Security Should Be Considered From the Beginning
Security is an important part of every cloud project.
Some basic practices include:
- Use IAM permissions carefully.
- Give users and applications only the permissions they need.
- Avoid putting AWS credentials directly inside source code.
- Protect sensitive datasets.
- Keep secrets outside public repositories.
- Monitor cloud resources and access.
Never upload AWS access keys or other credentials to GitHub or public repositories.
10. What Students Can Learn From This Workflow
Building an ML project on AWS helps students develop multiple skills at the same time:
- Python programming
- Data analysis
- Machine learning
- Cloud computing
- AWS services
- APIs
- Application deployment
- Security fundamentals
- Project documentation
These skills can also make academic projects more useful for internships and entry-level roles.
11. A Simple Learning Path
If you are completely new to AWS and machine learning, you can follow this sequence:
Python
↓
NumPy + Pandas
↓
Data Visualization
↓
Scikit-learn
↓
Machine Learning Fundamentals
↓
AWS Fundamentals
↓
Amazon S3
↓
Amazon SageMaker
↓
Model Deployment
↓
Build an End-to-End Project
↓
NumPy + Pandas
↓
Data Visualization
↓
Scikit-learn
↓
Machine Learning Fundamentals
↓
AWS Fundamentals
↓
Amazon S3
↓
Amazon SageMaker
↓
Model Deployment
↓
Build an End-to-End Project
Conclusion
An AI/ML project becomes much more valuable when we move beyond model training and understand the complete workflow.
AWS provides cloud services that can help developers store data, build machine learning workflows, deploy applications, and monitor their systems.
For students, an excellent approach is to start with a simple machine learning project, understand every stage, and gradually move it from a local notebook to the cloud.
The goal should not be to use as many AWS services as possible. Instead, choose the services that solve the actual requirements of your project.
Start small, build something useful, document your work, and keep improving it.
# artificial-intelligence# machine-learning# aws-ambassador# aws-student-builders-groups# amazon-sagemaker
Any opinions in this article are those of the individual author and may not reflect the opinions of AWS.Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article