
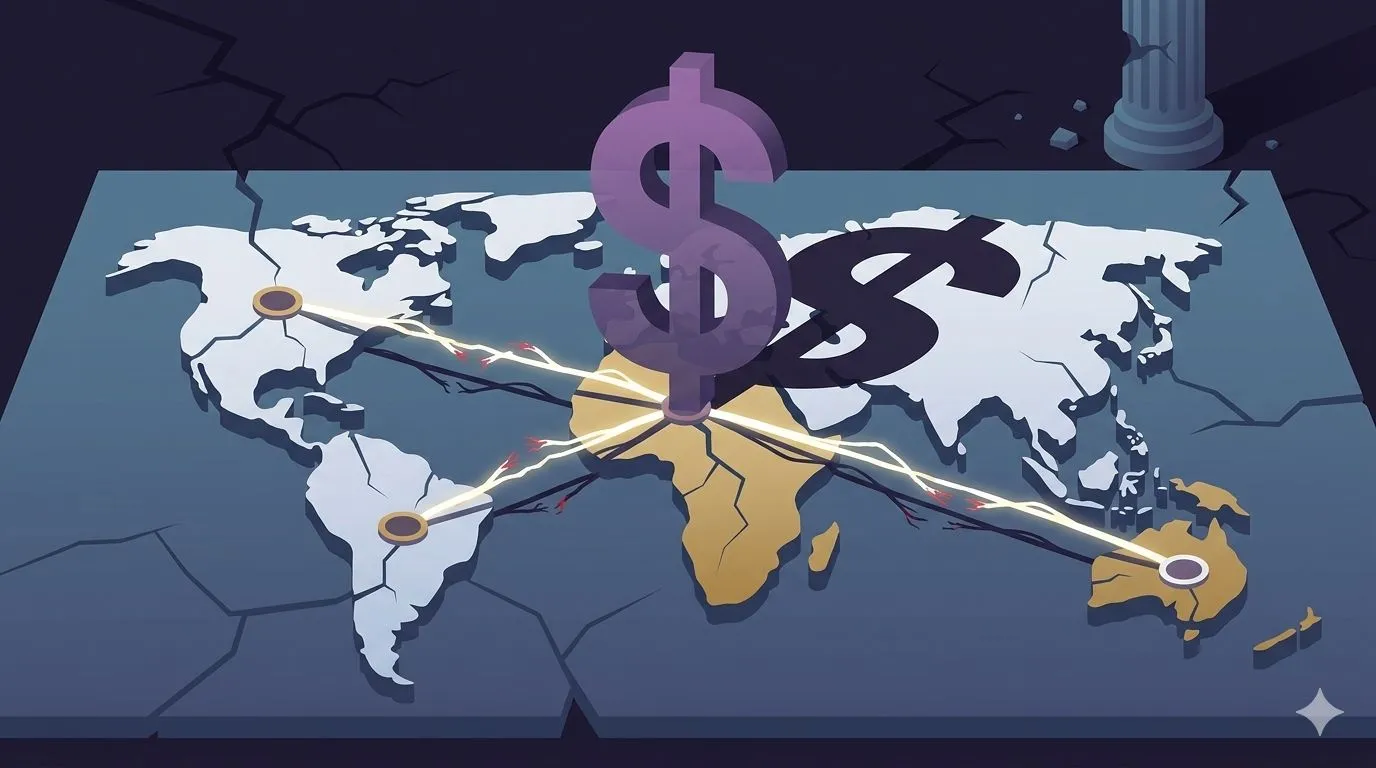
The Multi-Region High Availability Illusion: How I Spent $5,000 to Prepare for the Apocalypse
Congratulations! You've optimized databases, silenced alarms, and conquered microservice challenges. Then a question arises: What if an entire AWS region fails? A cable cut, natural disaster, or major outage could bring everything down. Your university quiz platform cannot tolerate downtime, so you design a Multi-Region, Active-Active, Globally Replicated Architecture. This article explores the gap between the perfect whiteboard design and its real-world behavior.
Phase 1: The Global Conquest (The Plan)
In your head, multi-region deployment is the ultimate flex. Your application will sit simultaneously in London (
eu-west-2), Tokyo (ap-northeast-1), and Virginia (us-east-1). If one continent loses power, Route 53 latency-based routing will seamlessly deflect traffic to the other side of the planet without a single user noticing.- The Vision: You deploy duplicate application stacks across three continents. You set up DynamoDB Global Tables or Amazon Aurora Global Databases to replicate your data worldwide at the speed of light.
- The Pride: You update your status to "Distributed Systems Architect" and confidently wait for a global infrastructure collapse just to watch your failover script run.
Phase 2: The Speed of Light Problem (The Reality)
You hit deploy, spin up your global endpoints, and test the app from your laptop. A student in London answers a quiz question.
The application freezes for three full seconds before saving the answer.
- The CAP Theorem Revenge: You realize that while cloud marketing promises magic, it cannot break the laws of physics. Data takes time to travel through undersea cables from London to Tokyo. Because you configured your global database to use Synchronous Replication (to ensure data consistency), your application refuses to confirm the student's answer until it has physically traveled around the globe and verified itself on three different continents. You have achieved 100% data security by making your app entirely unusable.
- The Split-Brain Nightmare: Defeated by latency, you switch to Asynchronous Replication. Now, changes sync quietly in the background. Success! Until two users update the exact same quiz record at the exact same millisecond—one in Virginia and one in Tokyo. The databases accept both writes, look at each other across the ocean, and begin a permanent architectural argument over who got there first. You are now spending your afternoon writing custom conflict resolution algorithms like a math professor.
1
2
3
4
5
6
7
8
9
       Perfect Synchronized Plan
                 ↓
     [Undersea Fiber Optic Cable]
                 ↓
        3,000ms Network Delay
                 ↓
     [Asynchronous Failover Attempt]
                 ↓
   Databases: "We are both the source of truth."
Phase 3: The True Cost of Paranoia
A month passes. No regions have gone down. The global internet is completely fine. You open your billing dashboard to check the price of absolute peace of mind.
Your jaw drops. Your monthly budget has been completely vaporized.
You forgot the Data Transfer Out (DTO) tax. AWS charges you to hold your data, they charge you to read your data, but they charge you a premium to move data between regions. Because your app was constantly syncing heavy background files and logs between Europe, Asia, and America, your background synchronization costs more than the actual compute power of the application. You are paying an enterprise lease price to host a quiz app that has zero active users at 4:00 AM.
Phase 4: The Irony of the Failover Test
Determined to prove the architecture is worth the cost, you decide to run a controlled Disaster Recovery Simulation. You log into the console and manually shut down your primary region (
us-east-1) to simulate a total outage.You sit back, cross your arms, and watch your global routing dashboard.
- The traffic safely routes to Europe! The frontend stays online!
- But wait... your secondary region's auto-scaling group was set to a low baseline to save money. The sudden influx of millions of global requests instantly chokes the European instances.
- The European servers crash, triggering a secondary failover to Tokyo. Tokyo gets overwhelmed and crashes three minutes later.
- You have successfully engineered a Cascading Failure Loop that knocked out three entire continents sequentially. You brought down your own global architecture faster than a real solar flare ever could.
The Summary for the Grand Finale
- Multi-Region Active-Active: The most expensive way possible to discover that light does not travel through glass fibers fast enough to satisfy a modern web browser.
- Disaster Recovery: A corporate ritual where you spend thousands of dollars trying to prevent a 0.001% infrastructure failure, only to create a 100% human error failure during the testing phase.
- The Single Region: A beautifully simple, highly efficient architecture where if the data center goes down, you simply close your laptop, stretch your legs, go outside, and tell your boss it’s a cloud issue out of your hands.
The Final Golden Rule: Before you build a system capable of surviving a nuclear winter, ask yourself: Does the business actually care if the website goes offline for twenty minutes? 99% of the time, the answer is no. Keep your code simple, host it in one solid region, take regular database backups, and enjoy your weekends. True operational peace isn't found in a complex reference diagram—it’s found in knowing when to stop engineering.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article