
From Data to Prediction: Building a Machine Learning Workflow with Amazon SageMaker AI
Explore the key stages of a machine learning workflow and how Amazon SageMaker AI can help developers prepare data, train models, evaluate performance, and deploy machine learning solutions on AWS.
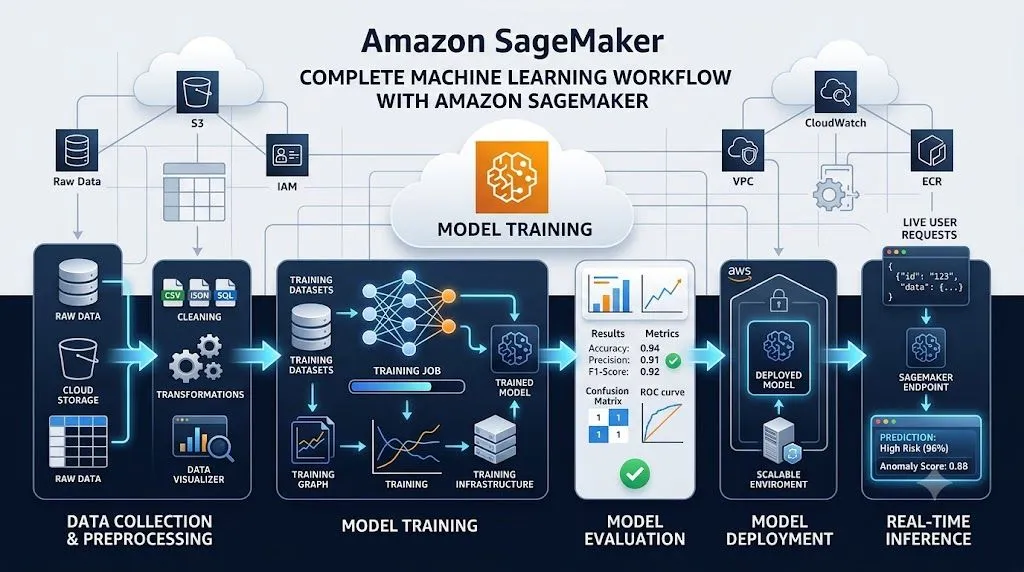
Machine Learning (ML) is not just about selecting an algorithm and training a model. A successful ML solution involves several stages, including preparing data, selecting features, training a model, evaluating its performance, and deploying it for predictions.
For developers who want to build machine learning solutions in the cloud, Amazon SageMaker AI provides tools and capabilities that support different stages of the machine learning lifecycle.
What Is Amazon SageMaker AI?
Amazon SageMaker AI is an AWS service designed to help developers and data scientists build, train, and deploy machine learning models.
Instead of managing every component of an ML environment manually, developers can use SageMaker AI capabilities to support tasks such as:
- Preparing and processing data.
- Developing and experimenting with machine learning models.
- Training models.
- Evaluating model performance.
- Deploying models for inference.
- Monitoring machine learning applications.
This makes SageMaker AI useful for projects ranging from learning experiments to production machine learning applications.
The Machine Learning Workflow
A typical machine learning project can be viewed as a sequence of steps.
1. Collect and Understand the Data
The first step is obtaining relevant data for the problem.
For example, suppose we want to predict house prices. Our dataset could contain features such as:
- Area of the house.
- Number of bedrooms.
- Location-related information.
- Age of the property.
- Historical selling price.
Before training a model, the data needs to be explored and understood.
2. Prepare the Data
Real-world datasets are often incomplete or inconsistent.
Data preparation may involve:
- Handling missing values.
- Removing duplicate records.
- Converting categorical information into numerical representations.
- Scaling numerical features when required.
- Splitting the dataset into training and testing sets.
Good data preparation can significantly affect the quality of a machine learning model.
3. Select a Machine Learning Algorithm
The appropriate algorithm depends on the problem.
For example:
| Problem | Possible Approach |
|---|---|
| Predict house prices | Regression |
| Predict whether an email is spam | Classification |
| Group similar customers | Clustering |
| Detect unusual behavior | Anomaly detection |
Choosing an algorithm should be based on the characteristics of the problem and the available data.
4. Train the Model
During training, the machine learning algorithm learns patterns from the training data.
For a regression problem, the model attempts to learn a relationship between input features and the target value.
For example:
Input: House features
Model: Machine learning algorithm
Output: Predicted house price
The training process adjusts the model parameters so that its predictions become more suitable for the training data.
5. Evaluate the Model
A model should not be evaluated only on the data it has already seen during training.
A separate test dataset can be used to measure how well the model performs on unseen data.
Depending on the problem, different evaluation metrics can be used.
For regression:
- Mean Absolute Error (MAE)
- Mean Squared Error (MSE)
- Root Mean Squared Error (RMSE)
For classification:
- Accuracy
- Precision
- Recall
- F1-score
The appropriate metric depends on the specific business or application requirement.
6. Deploy the Model
After evaluating the model, a trained model can be made available for predictions.
For example, a house-price prediction application could send the details of a house to a deployed model and receive a predicted price.
This stage is commonly referred to as inference.
A machine learning system can then be integrated with an application, website, or other software that needs predictions.
Where SageMaker AI Fits
Amazon SageMaker AI can support multiple stages of this workflow.
A simplified workflow can be represented as:
Data → Preparation → Training → Evaluation → Deployment → Inference
The exact architecture depends on the project requirements, but the overall idea is to provide tools that help developers move from experimentation toward usable machine learning applications.
A Simple Example
Consider a student building a house-price prediction project.
The workflow could look like this:
- Collect a house-price dataset.
- Explore the dataset and identify useful features.
- Clean and prepare the data.
- Split the data into training and testing datasets.
- Train a regression model.
- Evaluate the model using an appropriate metric.
- Improve the model if necessary.
- Deploy the trained model for inference.
- Connect the model to an application that sends house information and receives predictions.
This example demonstrates that machine learning is a complete workflow rather than simply training an algorithm.
Important Considerations
When developing machine learning solutions, several factors should be considered:
- Data quality: Poor or biased data can negatively affect model performance.
- Overfitting: A model that performs well on training data may perform poorly on unseen data.
- Evaluation: Use appropriate metrics that reflect the actual objective of the application.
- Security: Protect training data, model artifacts, and access credentials.
- Cost: Monitor the resources used for training, storage, and inference.
- Monitoring: A deployed model may need monitoring as data and real-world conditions change.
Conclusion
Machine learning involves much more than choosing an algorithm. Data preparation, training, evaluation, deployment, and monitoring are all important parts of developing a reliable ML solution.
Amazon SageMaker AI provides capabilities that can help developers and data scientists work through different stages of the machine learning lifecycle on AWS.
For students learning machine learning, building a small prediction project is a practical way to understand how concepts such as data preprocessing, model training, evaluation, and inference connect together in a real-world workflow.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article