
What Amazon DocumentDB Actually Knows About Your Data
You added an index and the query's still slow...now what? A look at how DocumentDB's query planner actually decides which index to use, and three production patterns (ESR order, partial indexes, and index bloat) that quietly cost you seconds instead of milliseconds - each with a fix that doesn't involve a bigger instance.
What Amazon DocumentDB Actually Knows About Your Data
You added an index (Yay!). But your queries are still slow (Boo!). You have no idea why (Uh-oh...).
I, too, have stared at an
explain() output for way longer than a normal human should, convinced the database was personally out to get me. The usual solution you hear (because rarely do you get an explanation first) is:> "You need more indexes." …or… "You need a bigger instance."
Both are crutches and usually miss the real problem. The database isn't guessing - it's making deliberate decisions based on what it knows about your data. Understanding how it decides, even at a high level, changes how you design schemas and indexes from day one.
Let's go through three patterns that reliably find their way into production. All three get more expensive to ignore as your data grows. The good news: each one has an easy fix, and none of them involve a bigger bill.
Unless your name is Bill and you reward database fixes with celebratory donuts (basically me, except in name).
How DocumentDB Forms a Picture of Your Data
DocumentDB doesn't scan every document to decide how to run your query. Instead it periodically samples your collections and builds statistical models, tracking things like:
- how many distinct values live on a field
- which values show up most often
- how these values are spread across a range
When a query arrives, the engine uses that model to estimate the cost of each available index, then picks the cheapest plan.
Two properties of that model drive everything we'll go through below:
- Statistics aren't refreshed continuously. The model updates periodically, not on every write. On large, busy collections, the engine's picture of your data can lag behind reality, and that lag can grow with collection size.
- The model is a sample, not a census. Statistics come from a random sample of your collection. A value that appears in only a small fraction of your documents might show up rarely in that sample, or not at all. When that happens, the engine falls back to a rough estimate instead of an observed frequency.
So why is this important? A bad estimate on a small collection costs you milliseconds. On a large one, it costs you seconds - three orders of magnitude different.
What the Engine Sees
Selectivity is key. It's the fraction of documents a predicate matches. You can see it in the output of
explain("executionStats") by comparing two values:nReturned- documents that matched all predicatestotalDocsExamined- documents the engine actually read
A 1:1 ratio is great. It means every document the index returned was one you needed. But the further that ratio drifts above 1:1, the more work DocumentDB is doing that produces nothing.
Example - you have an
orders collection with 2,000,000 documents and individual indexes on status, region, and customerId. You can see a distribution of status values via an aggregation:1
2
3
4
5
6
7
8
9
10
11
12
db.orders.aggregate([
{ $group: { _id: "$status", count: { $sum: 1 } } },
{ $sort: { count: -1 } }
])
// Output
[
{ _id: 'ACTIVE', count: 1199009 }, // ~60%
{ _id: 'PENDING', count: 359873 }, // ~18%
{ _id: 'CLOSED', count: 341443 }, // ~17%
{ _id: 'HOLD', count: 99675 } // ~5%
]The engine knows confidently that filtering for
ACTIVE means reading 60% of the collection. Even though stats are built from a sample, a value that dominates your data dominates the sample too.Now you combine the filter on
status with one on region (500,000 docs, ~25%) and one on customerId (40,000 docs, ~2%). The database engine ignores the status and region indexes entirely and stays with the one on customerId because positioning on 2% is cheaper than 25% or 60%. The order you wrote the filters is irrelevant - DocumentDB evaluates every available index and picks the lowest estimated cost. The remaining unused predicates become residual filters, checked one-by-one against every document the index returns.A compound index on
{customerId: 1, status: 1, region: 1} lets the engine use all three at once: 2% × 60% × 25% ≈ 0.3% of the collection. Documents examined drops from ~40,000 to ~6,000 with no residual filtering required. That's roughly a 6.7x cut in work from one index definition.Hold onto this selectivity logic - it's the foundation for all three patterns below.
Pattern 1 - Order is very relevant for your indexes
Your app shows a customer's recent orders,. sorted by priority:
1
2
3
4
const results = await orders
  .find({ customerId: "c-017", createdAt: { $gt: new Date("2026-10-01") } })
  .sort({ priority: -1 })
  .toArray();
You reason: "I've got 10 years of orders. The date filter throws away most of the collection, so
createdAt should lead the index."1
2
3
4
db.orders.createIndex(
{ createdAt: 1, customerId: 1, priority: -1 },
{ name: "idx_createdAt_leading" }
)The logic is sound, but it also backfires.
A B-tree index is sorted hierarchically - entries are ordered by
createdAt first, then by customerId within each createdAt value, then by priority within each pair. An equality match on the leading field (createdAt) takes you to one contiguous group of index entries that all share that value, so everything after it is already in order. But a range spans multiple groups. customerId is sorted within each group, not across all of them. So the moment the engine hits createdAt: {$gt: ...}, it can no longer use any following field for positioning or ordering. customerId degrades into a per-document check against every entry in the date range, and because the index can't return rows in priority order, every match gets pulled into memory and sorted before a single result comes back.Side note -
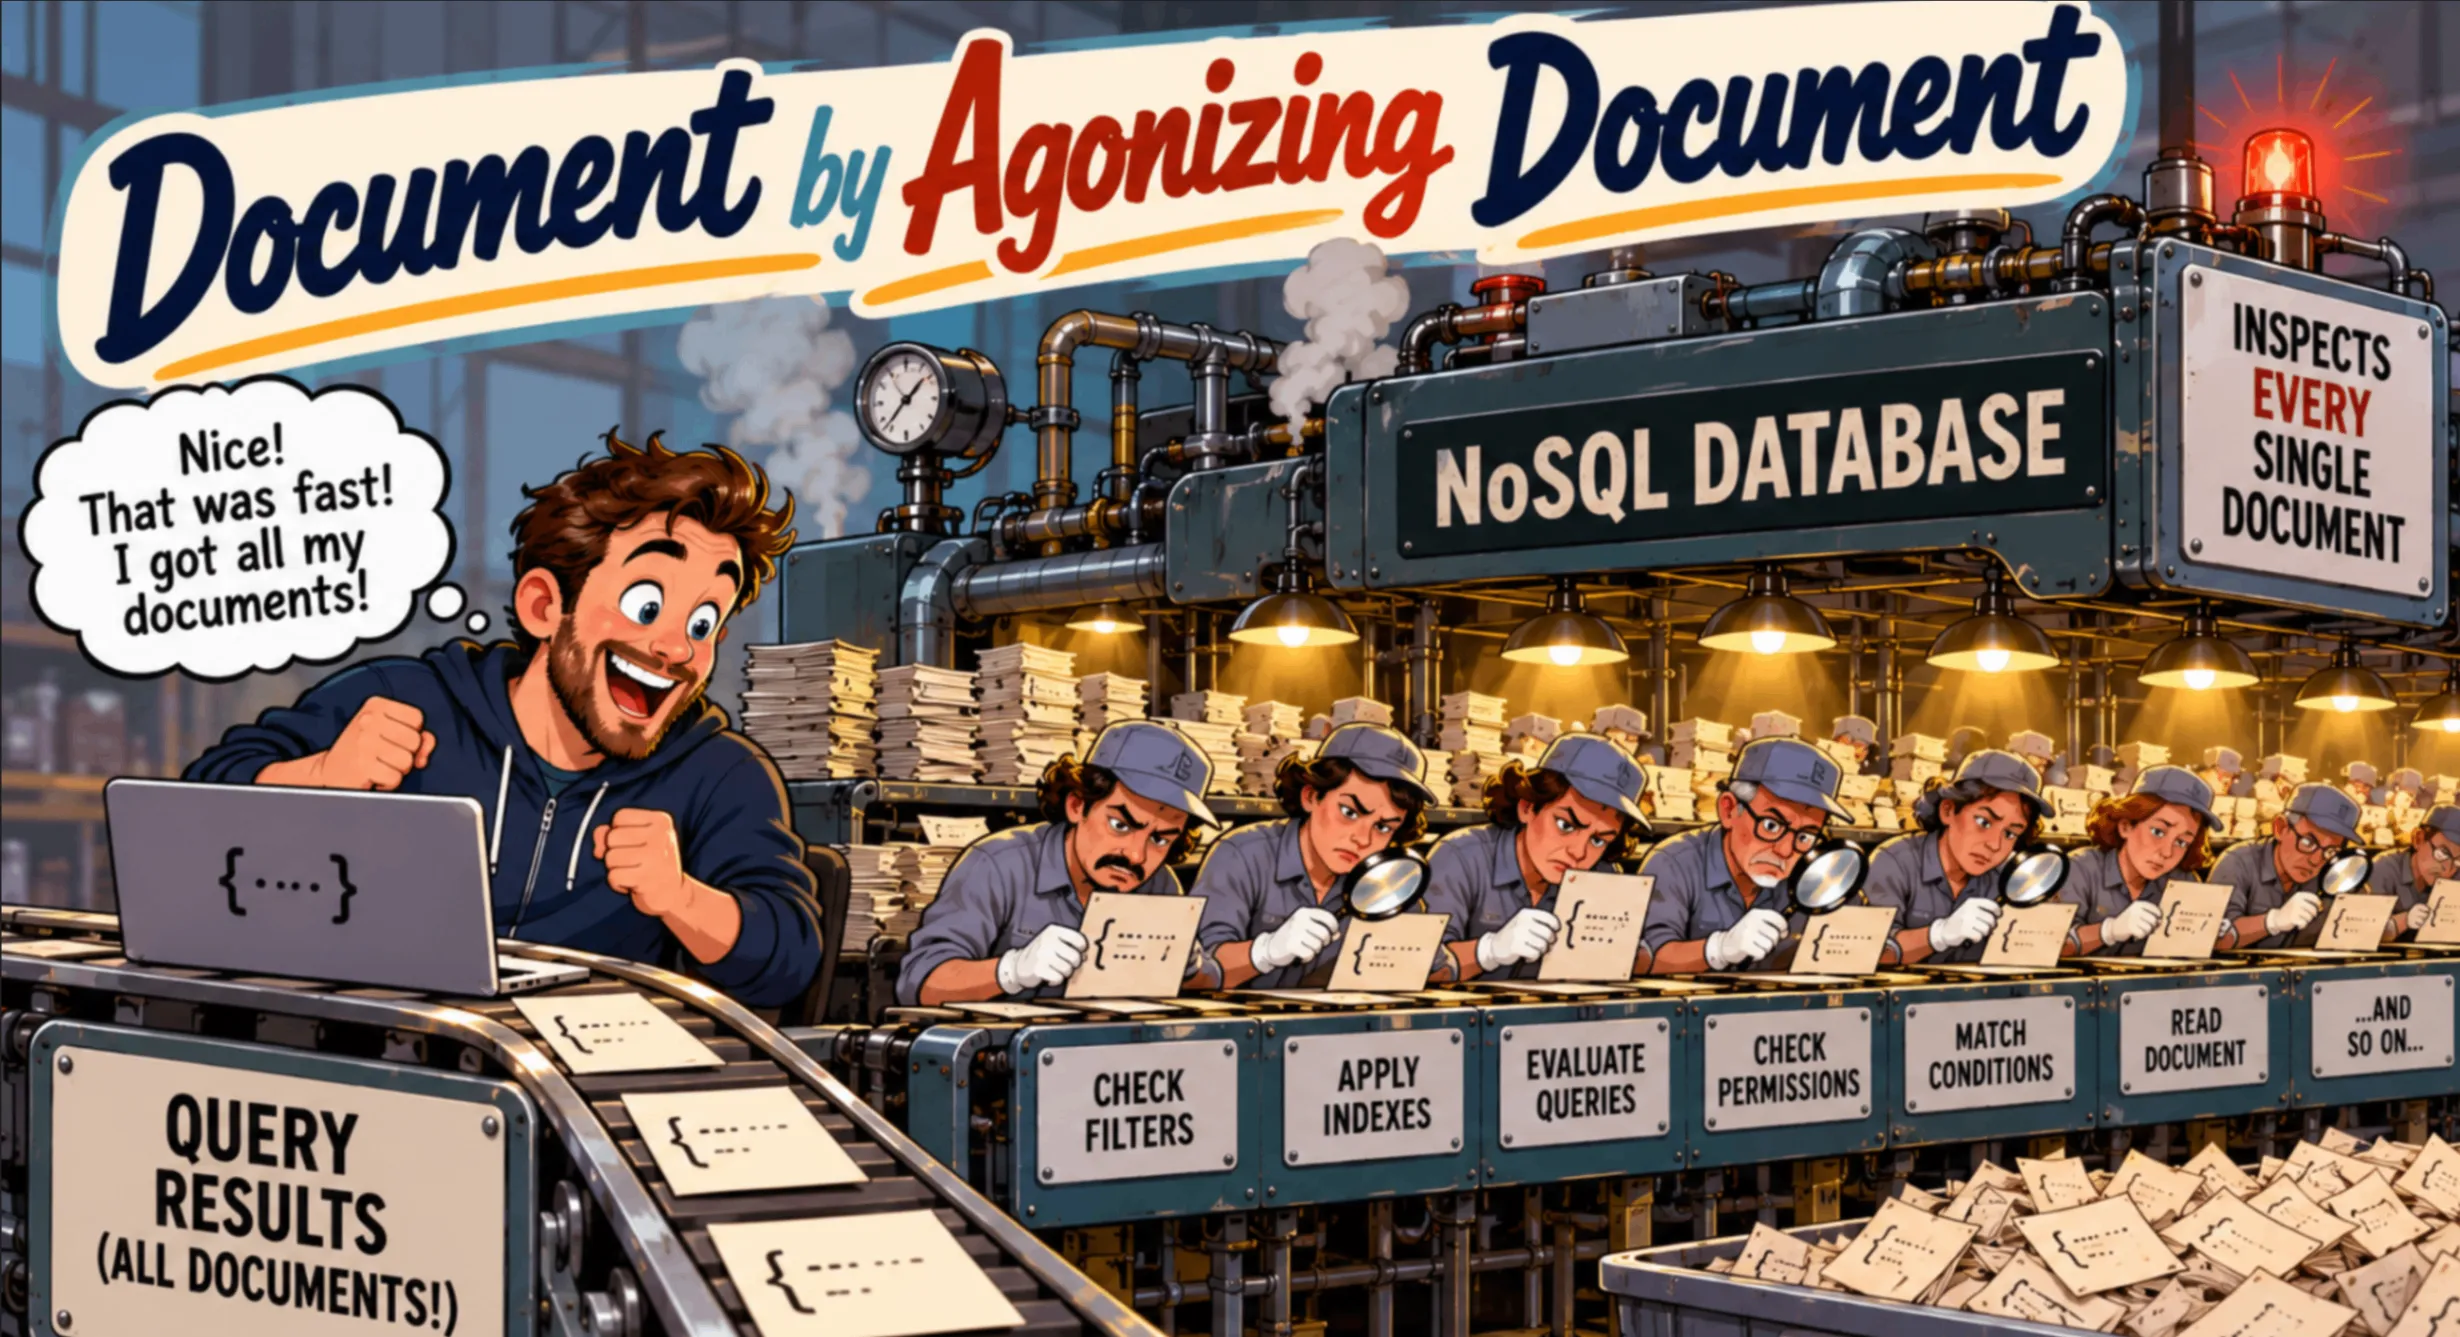
RBAR (row by agonizing row) doesn't really work for us since we don't have rows. So I propose a new phrase for NoSQL - DBAC (document by agonizing document). The Venn diagram of database nerds and Arizona baseball fans is now complete.
As a customer's orders pile up, the response time increases. And when your highest-volume customer (you know, that guy - the one with 40,000 orders and apparently no concept of archiving) loads the page, the query stalls while the engine buffers and sorts the whole set.
The fix is the ESR rule : Equality, Sort, Range, in that order:
1
2
3
4
db.orders.createIndex(
  { customerId: 1, priority: -1, createdAt: 1 },
  { name: "idx_esr" }
)
Same three fields, just reordered. The engine starts at
customerId (equality narrows the scan immediately), walks the index in descending priority order (which is pre-sorted), then uses createdAt (the range condition) to terminate the scan early. The in-memory sort disappears entirely.Against the same 2,000,000 orders, both indexes examine the same ~40,000 documents for customer
"c-017". But look at executionTimeMillis:1
2
3
4
5
6
7
8
9
10
11
// Range-leading index
executionStats: {
executionTimeMillis: '9184.354',
indexName: 'idx_createdAt_leading'
}
// ESR index
executionStats: {
executionTimeMillis: '300.725',
indexName: 'idx_esr'
}Same documents, same result, set but ~30x faster with only a field reorder in your index.
Pattern 2 - A queue’s worst enemy is itself
Background job queues follow a predictable lifecycle - jobs are created as
PENDING, get processed, and end up DONE or FAILED. Your poller grabs the oldest pending jobs:1
2
3
4
const nextJobs = await jobs
.find({ state: "PENDING" })
.sort({ createdAt: 1 })
.toArray();Early on, you indexed
{createdAt} because "find the oldest jobs" obviously means sort by date. And it seemed to work so nobody touched it.Then some time passes. After months of steady operation, 97% of your jobs are
DONE, 2% FAILED, and only 1% are still PENDING. The {createdAt} index covers every job but knows nothing about the values for state, so the engine scans the entire index and checks each entry against state = "PENDING" (we can use our new phrase DBAC - already useful). With 5,000,000 job entries, it examines all 5,000,000 to find the ~50,000 that are actually pending. A poller that runs every few seconds now takes over 30 seconds per run. Which is a little ironic and comical, right up until your pager starts going off.1
2
3
4
5
6
executionStats: {
nReturned: '49690',
executionTimeMillis: '34507.332',
totalDocsExamined: '5000000',
indexName: 'idx_created_full'
}This is a great fit for a partial index :
1
2
3
4
db.jobs.createIndex(
  { createdAt: 1 },
  { name: "idx_created_pending_partial", partialFilterExpression: { state: "PENDING" } }
)
A partial index only stores entries for documents matching its filter, so the 97% that are
DONE never make it in. The engine examines only the ~50,000 pending entries, and the same query drops from >30 seconds to <300 milliseconds:1
2
3
4
5
6
executionStats: {
nReturned: '49690',
executionTimeMillis: '289.937',
totalDocsExamined: '49690',
indexName: 'idx_created_pending_partial'
}That's a ~119x improvement...AND the index is physically smaller on top of it. Less memory, less I/O.
This is the one pattern where a full-size index gets worse the more successful you are. Every job you complete becomes dead weight in the original index. The partial index stays lean no matter how much history you pile up behind it.
Pattern 3 - Dead Weight
High-update workloads come with a hidden cost. When a document is updated or deleted, the old index entry isn't immediately removed. It lingers as a stale entry until a background cleanup process reclaims it. On a busy collection with heavy churn, those entries can pile up faster than cleanup clears them.
And the engine's cost model doesn't see them. Its cost estimates are built on live document counts and the stats it last collected. So if a query is estimated to touch 100,000 documents, the engine budgets for 100,000. But at runtime, the index scan has to walk past the stale entries (confirming each one is dead) before it reaches the live ones. An index that looked like 100,000 entries at plan time might walk 500,000 when it actually runs.
Example - you have a
catalog collection with millions of products. You add an index on updatedAt to support the "Recently Updated" section of your storefront:1
2
3
4
5
6
7
8
db.catalog.createIndex({ updatedAt: 1 }, { name: "idx_updatedAt" })
// Your storefront query
const recentlyUpdated = await catalog
.find({ updatedAt: { $gt: new Date(Date.now() - 24 * 60 * 60 * 1000) } })
.sort({ updatedAt: -1 })
.limit(50)
.toArray();During the day (e.g. 9AM - 5PM, you know, when you tumble outta bed and stumble to the kitchen to pour yourself a cup of ambition ...), updates trickle in and cleanup keeps pace. But every night your suppliers push full catalog refreshes: price changes, availability updates, new descriptions across millions of products. Each change updates
updatedAt, and each update orphans the previous index entry. A nightly sync touching 1,000,000 products creates 1,000,000 stale entries in idx_updatedAt within minutes, inflating its physical size by 44% with zero change in live document count.By the time customers start browsing the next morning, cleanup hasn't caught up. The "Recently Updated" query (which the engine estimated as cheap) now walks through hundreds of thousands of stale entries to find the 50 it needs. Pages crawl, and there's no clear culprit. Your code hasn't changed, your data looks correct, and the index covers exactly the right field.
If you have a known bulk-update window, make
reIndex part of that workflow. Run it after the sync finishes and before morning traffic shows up:1
db.runCommand({ reIndex: "catalog", index: "idx_updatedAt" })The size difference before and after is your dead weight:
1
2
3
db.runCommand({ collStats: "catalog" }).indexSizes.idx_updatedAt
// Before reIndex: ~11.4 GB (bloated)
// After reIndex:  ~7.9 GB  (back to baseline)
That's 3.5 GB of pure overhead (for the astute readers wondering where 44% came from above) that the engine was dragging a scan through every morning.
How These Patterns Compound
Performance problems are rarely one bad decision - they come in bundles. A query on a high-frequency
status value, run against an ESR-violating index, on a collection carrying dead weight, with statistics that haven't refreshed since the last bulk load, can be 100x slower than the exact same query without that baggage. The individual costs don't add. They multiply.- Selectivity + non-ESR indexes compound because a poorly ordered index can't narrow the scan efficiently even when selectivity is reasonable. You pay once for the extra range traversal, and once for the in-memory sort.
- Queue patterns + bloat compound when queue jobs are updated before deletion (marked
FAILED, then retried). Every retry cycle creates new dead entries, and a bloated collection behind a full index is the worst of both worlds. - Skewed distributions + stale statistics compound when a bulk operation shifts your data distribution faster than the model refreshes. The engine confidently picks a plan that used to be right and is now wrong.
None of the fixes required scaling to a larger instance or rewriting application code. They required understanding what the engine knows about your data, and designing indexes to work with that knowledge instead of against it. The engine has a model, it makes estimates, and it picks the cheapest plan it can find. Give it good options and it makes good choices. Give it bad ones and it does its honest best with what you handed it.
---
Join the Community
If you are working with DocumentDB or other NoSQL databases, come join the AWS NoSQL Launchpad ! This is where developers help each other figure out NoSQL design decisions, and it's filled with AWS NoSQL experts.
People share real scenarios, discuss when to use which service, and work through access pattern design together. Practical discussions about the decisions that matter.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article