
Amazon EKS Autoscaling Is Two Problems Not One
In this hands-on workshop, we follow application demand from rising CPU usage to new pods and finally new EC2 capacity. Along the way, we compare how Cluster Autoscaler and Karpenter respond when Amazon EKS runs out of room.
Series: Workshops (2 articles)
- 2Amazon EKS Autoscaling Is Two Problems Not One This article
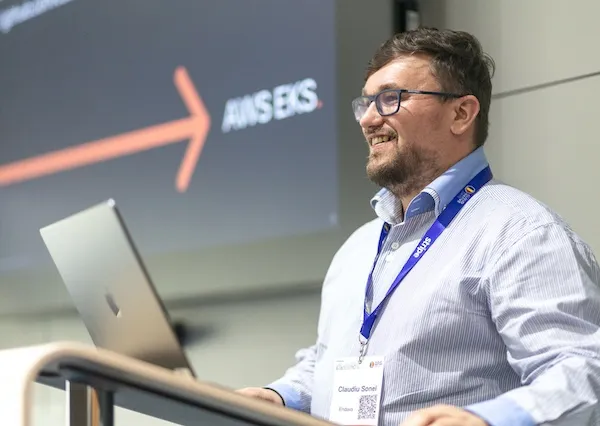
A short companion to my Cloud Native Days Romania 2025 workshop, where we used the Horizontal Pod Autoscaler, Cluster Autoscaler and Karpenter to follow application demand from rising CPU usage to new pods and, finally, new EC2 capacity.
When we say that a Kubernetes cluster scales, it can sound like one controller makes one decision. In practice, there are two different questions:
- How many copies of the application should be running?
- Does the cluster have enough capacity to run them?
That distinction was the main idea behind my Amazon EKS Autoscaling workshop at Cloud Native Days Romania 2025 .
This is not a workshop about the newest feature in Kubernetes. It is a small lab that makes the relationship between workload scaling and infrastructure scaling visible. I am adding it to my workshop collection because that mental model is still useful.
The application can scale before the cluster does
The workshop starts with a deliberately simple application on Amazon EKS. Each pod has CPU and memory requests, and a Horizontal Pod Autoscaler keeps CPU utilization around a target value.
We then generate load.
The first reaction happens exactly where we expect it: the HPA increases the number of replicas. More pods appear because the application needs more capacity.
But creating pods does not create nodes. If the existing nodes no longer have enough room, some of those new pods remain
Pending. The HPA has done its job, but the scheduler still needs somewhere to place the replicas.That is where the second scaling loop begins.
The second loop creates room for the pods
In the first part of the lab, we install Kubernetes Cluster Autoscaler . It watches for pods that cannot be scheduled and adjusts the desired capacity of the EC2 Auto Scaling group behind the EKS managed node group.
The complete chain looks like this:
1
2
3
4
5
6
7
8
9
10
11
12
13
Application load increases
          |
          v
HPA creates more pods
          |
          v
Some pods cannot be scheduled
          |
          v
Cluster Autoscaler or Karpenter adds nodes
          |
          v
The scheduler places the pending pods
This is the moment I wanted participants to see rather than only read about. We watched the HPA, the pods and the nodes at the same time, using
kubectl, the autoscaler logs and Kube Ops View.Autoscaling became much easier to understand once it stopped looking like one mechanism.
Repeating the experiment with Karpenter
The second part of the workshop keeps the application and the HPA unchanged. We remove Cluster Autoscaler, install Karpenter, create a
NodePool and an EC2NodeClass, and then run the same load test again.The application-side decision is still the same: the HPA creates more replicas. What changes is how the cluster responds when those replicas cannot be scheduled.
Cluster Autoscaler works with the capacity boundaries already described by node groups and Auto Scaling groups. Karpenter looks at the requirements of unschedulable pods and provisions matching EC2 capacity directly. Those requirements can include CPU, memory, architecture, Availability Zone, taints, tolerations and other scheduling constraints.
Running the same experiment twice makes the difference concrete. The demand did not change. The pods did not change. The mechanism responsible for turning pending pods into compute capacity changed.
This is not a winner takes all comparison
I do not think the useful conclusion is that one autoscaler simply replaces the other in every cluster.
Cluster Autoscaler fits naturally when a platform is already organized around a small, well-defined set of managed node groups. Karpenter is especially interesting when workloads have diverse or rapidly changing compute requirements and the platform should choose capacity closer to scheduling time.
Both approaches also have an operational cost. Cluster Autoscaler depends on node-group design and sizing. Self-managed Karpenter gives the platform more flexibility, but the team is responsible for installing, upgrading and operating its controller and for setting safe provisioning and disruption policies.
The better question is not which one has the longest feature list. It is:
What kind of capacity model do I want the platform team to operate?
Try the workshop yourself
The complete material is available in the workshop-cndro-2025 repository . It includes the Terraform configuration for the VPC and EKS cluster, the IAM prerequisites, Kube Ops View, the Cluster Autoscaler setup and the Karpenter resources used in the lab.
If you run it, pay attention to the transitions rather than only the final state:
- Watch the HPA create replicas.
- Notice when pods become
Pending. - Observe which autoscaler reacts.
- Follow the new node until it becomes ready.
- Stop the load and watch the system scale back down.
That sequence is the workshop.
A note about the 2025 lab
The repository is a historical record of the workshop, not a production reference architecture. Review the Kubernetes, Terraform provider, module and Karpenter versions before running it. The lab also uses a moving Bottlerocket AMI alias for convenience; for production clusters, AWS recommends pinning an AMI that you have tested .
The Amazon EKS compute story has also continued to evolve. EKS Auto Mode now provides managed cluster compute and builds on Karpenter. That does not make the workshop obsolete, but it does add another operational model to consider.
The original lesson remains the same: pod scaling and node scaling are related, but they are not the same decision.
The next time someone says that an EKS cluster scales automatically, I would ask one more question:
Which part is scaling?
I am also curious how teams are solving the second problem today. If you work with Amazon EKS, vote in this Builder Center poll and share what primarily manages your worker-node capacity. If you use a mixed or different approach, I would be interested in the details in the comments.
Series: Workshops (2 articles)
- 2Amazon EKS Autoscaling Is Two Problems Not One This article
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article