
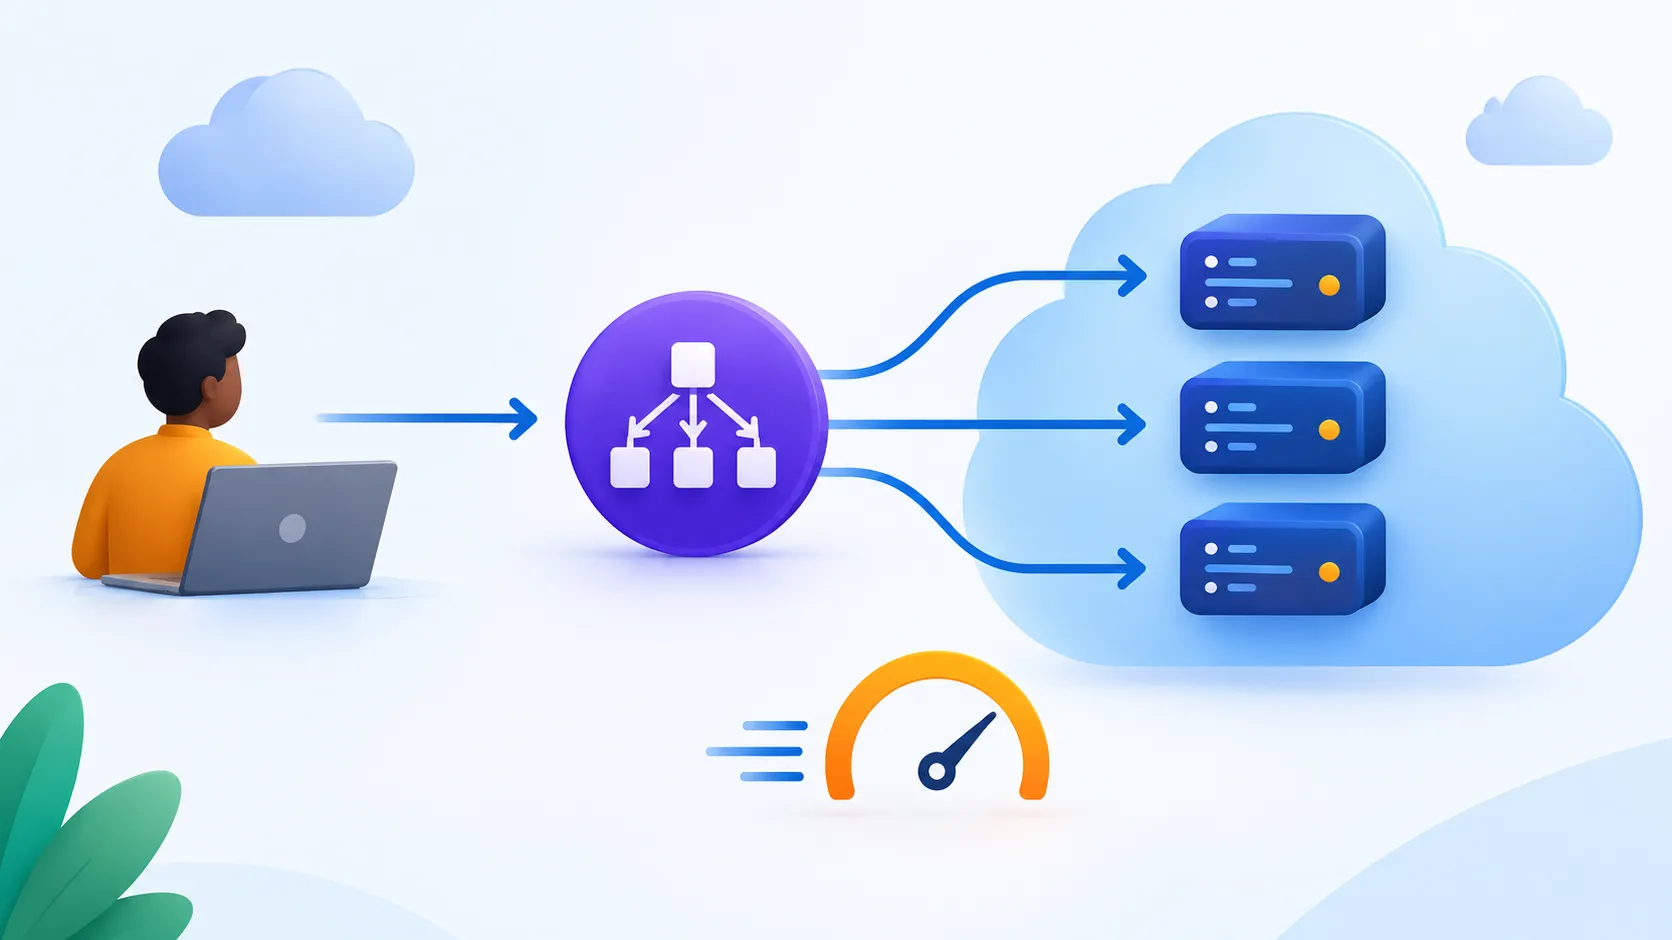
A Load Balancer Adds Latency. So Why Use One?
A practical look at traffic distribution and AWS Application ELB
When building applications in the cloud, it is tempting to think of performance in simple terms:
Fewer layers = less latency.
If an EC2 instance can respond directly to a request, why introduce another component between the user and the server?
That question became particularly interesting during one of my cloud networking projects.
I built an AWS environment with an Application Load Balancer (ALB), EC2 instances distributed across Availability Zones, Auto Scaling, health checks, and Security Groups. I then compared requests sent directly to an EC2 instance with requests routed through the load balancer.
The result was interesting.
The first request through the ALB was measurably slower than direct access to the instance. But subsequent requests were almost identical in average latency.
So, if the load balancer introduces some overhead, why use one at all?
The answer has less to do with making a single request faster and more to do with how an application behaves when you introduce multiple servers, failures, changing traffic, and the need for controlled access.
This article walks through that experiment and what it taught me about designing resilient AWS architectures.
The architecture I built
The practical deployment was built in the AWS Europe (Stockholm) Region (
eu-north-1) using a custom Amazon VPC spanning two Availability Zones.The architecture included:
- An Amazon VPC
- Two Availability Zones
- EC2 instances
- An EC2 Auto Scaling Group
- An internet-facing Application Load Balancer
- An ALB target group
- Health checks
- Security Groups
- An Internet Gateway
Instead of allowing users to connect directly to individual EC2 instances, the Application Load Balancer becomes the entry point for the application.
It receives incoming HTTP traffic and distributes requests to healthy instances in the target group.

AWS architecture showing the Internet Gateway, Application Load Balancer, Availability Zones, EC2 instances, and Security Groups.
The important part of this architecture is that the EC2 instances are no longer treated as individual public endpoints.
The ALB sits in front of them and becomes the component responsible for distributing incoming application traffic.
Why use a load balancer?
At first glance, a load balancer might look like an unnecessary extra hop.
A simple architecture could look like this:

There is very little between the client and the application.
But what happens when the application needs to run on multiple instances?

Now something has to decide where each request should go.
This is where a load balancer becomes useful.
The architecture becomes:

The ALB provides a single entry point while distributing traffic across the available targets.
More importantly, it can use health checks to determine whether a target is healthy enough to receive traffic.
That distinction became important during my experiment.
Building the web tier
For the web tier, I configured an EC2 Auto Scaling Group across two Availability Zones.
The instances hosted a simple web application and were placed behind the Application Load Balancer.
The Security Group configuration was deliberately restrictive.
The instances were configured to accept HTTP traffic on port 80 from the load balancer, rather than treating the instances themselves as unrestricted public endpoints.
This creates a useful separation:

The ALB acts as the public-facing entry point, while the instances form the application tier behind it.

EC2 instances participating in the web tier.
Health checks: the part that changes the architecture
One of the most important features of the setup was the target group health check.
The ALB continuously checks the registered instances.
In my configuration, the health check used HTTP requests to determine whether an instance was responding successfully.
If an instance failed to return the expected response — for example, because its web server had stopped responding — the load balancer could stop routing traffic to that unhealthy target.
This is important because the architecture is no longer simply:
“Send traffic to a server.”
It becomes:
“Send traffic to a healthy server.”

Target group showing the health status of the EC2 instances.
This is one of the reasons the load balancer should not be evaluated purely by asking whether it makes an individual request faster.
It is part of a larger availability strategy.
Now for the interesting part: measuring latency
This is where I wanted to move beyond simply configuring AWS services.
I wanted to see what the extra network layer actually meant for request latency.
I tested two paths.
Test 1: Direct EC2 access
The client connected directly to the EC2 instance through its public IP address.
Test 2: Load-balanced access
The client accessed the application through the ALB’s DNS name.
The results were:
| Access path | Average latency |
|---|---|
| Direct EC2 access | 0.320 seconds |
| ALB — initial request | 0.441 seconds |
| ALB — subsequent requests | 0.321 seconds |
These numbers came from my particular coursework environment and test conditions, so they should not be interpreted as general AWS performance benchmarks.
But they were useful for understanding the architectural trade-off.
Direct access was faster — initially
The direct EC2 request averaged approximately 0.320 seconds.
There was no load balancer between the client and the instance.

Latency measurement when accessing the EC2 instance directly.
When I introduced the ALB, the first measured request increased to approximately 0.441 seconds.
That’s a difference of around 0.121 seconds compared with the direct request.

Latency measurement when accessing the application through the Application Load Balancer.
At first, that seems to support a simple conclusion:
The load balancer makes the application slower.
But that would be an incomplete interpretation.
The subsequent requests settled at approximately 0.321 seconds, almost the same as the direct-access measurement.
So the more interesting question became:
What exactly are we optimizing for when we introduce a load balancer?
Performance is not the same as availability
This was probably the most important lesson from the experiment.
A direct connection to one EC2 instance can be very simple and fast.
But that architecture also creates a dependency on that particular instance.
If that instance becomes unavailable, the application becomes unavailable.
With a load-balanced architecture, the application can operate across multiple instances.
The traffic path becomes:
1
2
3
4
5
                         ┌── EC2 Instance A
                         │
User → ALB ──────────────┼── EC2 Instance B
                         │
                         └── EC2 Instance C
If one of those targets becomes unhealthy, the ALB’s health-check mechanism can prevent traffic from being routed to that unhealthy target.
This is where the architectural value becomes clearer.
The purpose isn’t simply:
“Make this request faster.”
It is also:
“Give the application multiple healthy places to handle requests.”
The role of Auto Scaling
The load balancer was not operating alone.
The architecture also used an EC2 Auto Scaling Group.
This introduces another important cloud architecture concept.
Application demand can change over time.
Instead of permanently relying on a single server, an Auto Scaling Group can manage a fleet of EC2 instances according to the configured scaling behaviour.
The ALB then provides a consistent entry point to that fleet.
Conceptually:
1
2
3
4
5
6
7
8
9
10
                    ┌── EC2
                    │
                    ├── EC2
User → ALB ─────────┤
                    ├── EC2
                    │
                    └── EC2
                         ▲
                         │
                    Auto Scaling
The result is a separation of responsibilities:
ALB
Distributes incoming application traffic.
Distributes incoming application traffic.
Auto Scaling
Manages the EC2 instance fleet according to scaling configuration.
Manages the EC2 instance fleet according to scaling configuration.
EC2
Runs the application workload.
Runs the application workload.
Health checks
Help determine whether registered targets are healthy.
Help determine whether registered targets are healthy.
This separation is one of the things I found particularly useful when thinking about AWS architecture as a system rather than a collection of individual services.
Security is part of the traffic flow
The networking configuration also reinforced something I have encountered repeatedly in cybersecurity:
Connectivity and security cannot really be separated.
The EC2 Security Group was configured so that HTTP traffic to the web tier was allowed from the load balancer rather than simply opening the application server broadly to the internet.
That gives us a traffic model closer to:
1
2
3
4
5
6
7
8
Internet
 │
 ▼
 ALB
 │
 │ Allowed application traffic
 ▼
EC2 Web Tier
This is more deliberate than giving every component unrestricted connectivity.
It also demonstrates an important cloud security principle:
Allow communication based on what actually needs to communicate.
A technically functional network is not automatically a well-designed network.
What happens when something fails?
This is where the architecture becomes more interesting than the latency measurement.
Imagine one of the EC2 instances stops responding.
Without a load balancer:
1
User → Failed EC2 Instance
The user is still attempting to reach the failed resource.
With the load-balanced architecture:
1
2
3
4
5
                         ┌── Healthy EC2
                         │
User → ALB ──────────────┼── Unhealthy EC2 ✕
                         │
                         └── Healthy EC2
The health check provides the information the load balancer needs to distinguish between healthy and unhealthy targets.
The traffic can therefore continue toward healthy targets rather than treating every instance as equally available.
This is where the additional architectural layer starts to justify its existence.
The trade-off: more architecture, more responsibility
The experiment also reminded me that cloud architecture is rarely about finding a single “best” component.
Adding an ALB introduces another layer into the request path.
That means additional configuration, monitoring, troubleshooting, and potentially additional latency.
My experiment measured that difference in a very specific environment.
At the same time, the ALB provides capabilities that direct EC2 access does not provide by itself — particularly centralized traffic distribution and health-aware routing across multiple targets.
So the architectural decision should not be reduced to:
ALB = slower
or
ALB = better
The more useful question is:
What does the application need from its architecture?
For a simple development environment, direct access might be perfectly adequate.
For an application requiring multiple instances, traffic distribution, and health-aware routing, the architecture has different requirements.
What I learned from building it
The most valuable part of this project wasn’t configuring the load balancer.
It was seeing how several AWS components work together to solve a larger problem.
I started with individual services:
VPC.
EC2.
Auto Scaling.
Application Load Balancer.
Security Groups.
Target Groups.
But the actual architecture was the relationship between them.
The VPC provided the network foundation.
The EC2 instances provided compute.
The Auto Scaling Group managed the web-tier fleet.
The ALB provided the traffic entry point and distribution layer.
The target group and health checks provided awareness of target health.
And the Security Groups controlled which traffic was allowed to reach the application tier.
That is a very different way of looking at AWS.
Instead of asking:
“What does this service do?”
I am increasingly asking:
“What problem does this service solve, and what does it need to work with?”
That shift in thinking is one of the most useful things this project gave me.
A final look at the architecture

Final AWS network topology showing external HTTP traffic entering through the Internet Gateway and Application Load Balancer before reaching EC2 instances across Availability Zones.
The architecture demonstrates a simple but important cloud design principle:
High availability isn’t achieved simply by creating more servers.
Those servers need to be placed within a properly designed network, monitored for health, protected by appropriate access controls, and connected through a traffic-distribution mechanism that understands the state of the application.
Final thoughts
This project started as a coursework exercise in cloud networking.
It ended up giving me a much better appreciation of the trade-offs involved in cloud architecture.
The latency experiment was particularly useful because it challenged a very simple assumption:
More infrastructure doesn’t necessarily mean better performance.
The ALB introduced an additional step in the request path, and my measurements captured that overhead during the initial request.
But the architecture was designed for something broader than a single fast request.
It was designed to distribute traffic across multiple compute resources, monitor their health, and provide a consistent entry point to the application.
That is perhaps the bigger lesson I took from the project:
Good cloud architecture isn’t about removing every layer. It’s about understanding why each layer exists.
And sometimes, the layer that adds a little overhead is the one that makes the whole system more resilient.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article