
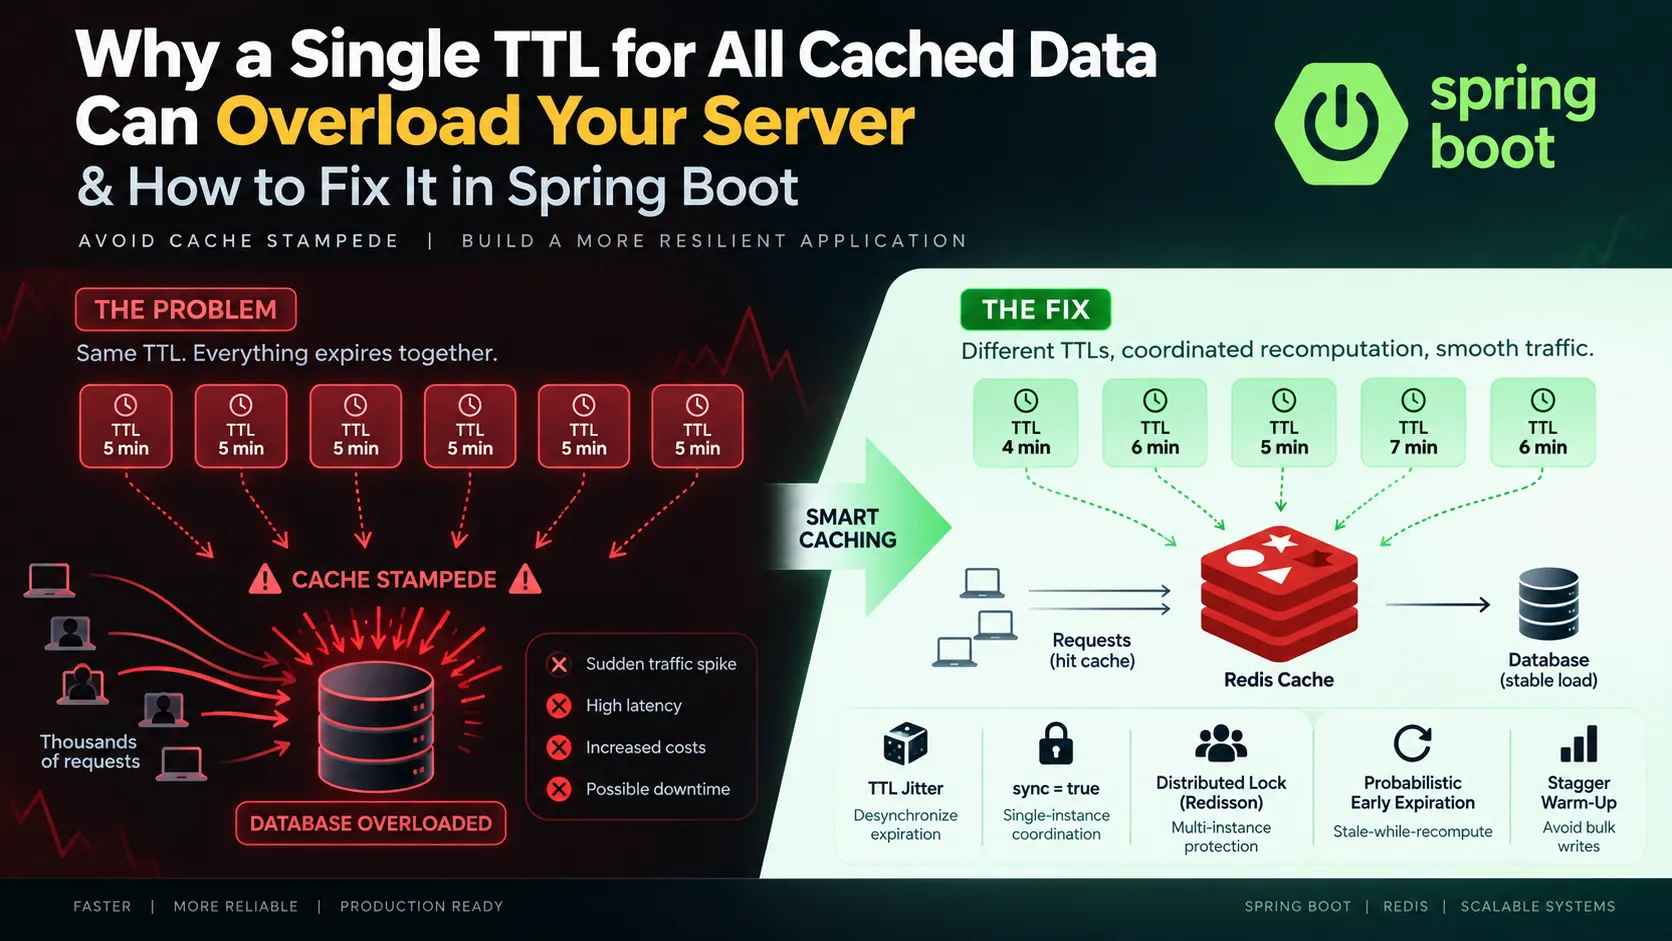
Why a Single TTL for All Cached Data Can Overload Your Server & How to Fix It in Spring Boot
Learn why using a single TTL for all Redis cache entries can cause cache stampedes and overload your database. This guide covers practical Spring Boot solutions including TTL jitter, sync = true, Redisson distributed locks, early expiration, and staggered cache warm-up.
Series: WILT- What I Learned today (2 articles)
- 1Why a Single TTL for All Cached Data Can Overload Your Server & How to Fix It in Spring Boot This article
Introduction
Caching is one of the simplest ways to make an application faster and cheaper to run. Add a Time-To-Live (TTL) to every cached entry, and you're done—right?
Not quite. A common but costly mistake is assigning the same TTL to every cache entry. It looks harmless in development, but under real production load it can create sudden, synchronized spikes of traffic against your database or backend service. This pattern is widely known as the cache stampede (or thundering herd) problem.
In this article, we'll look at why uniform TTLs cause this issue, and walk through several practical ways to solve it in a Java Spring Boot application.
The Problem: What Happens When Everything Expires Together
Imagine you cache product details, user sessions, or API responses, and you set
TTL = 5 minutes for all of them, starting at roughly the same time (e.g., during a deployment, a cache warm-up, or a traffic burst that populates many keys together).Five minutes later, all of those keys expire at almost the same instant. If your application receives steady traffic, every one of those now-missing keys triggers a fresh call to the database or origin service — at the same time. The result:
- A sudden burst of duplicate, expensive queries hitting your database.
- Increased latency for users whose requests coincide with the expiry window.
- In severe cases, the backend gets overwhelmed and the whole system slows down or fails — ironically, the exact scenario caching was meant to prevent.
This becomes worse at scale: microservices with shared cache layers (Redis, Memcached), high-traffic endpoints, and horizontally scaled instances all amplify the effect, because many application nodes may try to recompute the same expired value simultaneously.
Why This Happens
Two root causes combine to produce the stampede:
- Synchronized expiration — entries populated around the same time, with identical TTLs, expire together.
- No coordination on cache miss — when a key expires, every concurrent request that misses the cache independently goes to the backend to recompute the value, instead of one request recomputing it while others wait or use a stale value.
The fix, therefore, has two parts: desynchronize expiration, and coordinate recomputation.
Solution 1: Add Jitter (Randomized TTL)

Instead of a fixed TTL, add a small random offset so entries don't all expire at once.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
import java.time.Duration;

import java.util.concurrent.ThreadLocalRandom;


public class TtlUtils {


    private static final Duration BASE_TTL = Duration.ofMinutes(5);

    private static final Duration JITTER = Duration.ofSeconds(30);


    public static Duration withJitter() {

        long jitterMillis = ThreadLocalRandom.current()

                .nextLong(-JITTER.toMillis(), JITTER.toMillis());

        return BASE_TTL.plusMillis(jitterMillis);

    }

}
When using Spring's
RedisCacheManager, you can apply per-cache TTL configuration and generate jitter at write time:1
2
3
4
5
6
7
8
9
public RedisCacheManager cacheManager(RedisConnectionFactory connectionFactory) {
RedisCacheConfiguration config = RedisCacheConfiguration.defaultCacheConfig()
.entryTtl(TtlUtils.withJitter());
return RedisCacheManager.builder(connectionFactory)
.cacheDefaults(config)
.build();
}This alone significantly reduces the chance of mass simultaneous expiration.
Solution 2: Synchronize Recomputation with sync = true
Spring's
@Cacheable annotation supports a sync attribute. When multiple threads request the same missing key concurrently, only one thread executes the method; others wait for the result instead of all hitting the database.1
2
3
4
5
public Product getProduct(String id) {
return productRepository.findById(id)
.orElseThrow(() -> new ProductNotFoundException(id));
}Limitation:
sync = true only coordinates threads within a single JVM instance. In a distributed, multi-instance deployment, each instance can still independently recompute the value. For that, you need distributed locking.Solution 3: Distributed Locking with Redisson

For multi-instance deployments sharing a Redis cache, use a distributed lock so only one instance recomputes an expired value while others either wait briefly or serve a stale value.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
public class ProductService {
private final RedissonClient redisson;
private final RedisTemplate<String, Product> redisTemplate;
private final ProductRepository repository;
public Product getProduct(String id) {
String cacheKey = "product:" + id;
Product cached = redisTemplate.opsForValue().get(cacheKey);
if (cached != null) {
return cached;
}
RLock lock = redisson.getLock("lock:" + cacheKey);
try {
if (lock.tryLock(200, 5000, TimeUnit.MILLISECONDS)) {
try {
// Double-check after acquiring the lock
cached = redisTemplate.opsForValue().get(cacheKey);
if (cached != null) {
return cached;
}
Product fresh = repository.findById(id)
.orElseThrow(() -> new ProductNotFoundException(id));
redisTemplate.opsForValue().set(cacheKey, fresh, TtlUtils.withJitter());
return fresh;
} finally {
lock.unlock();
}
} else {
// Could not get the lock quickly — fall back to DB or a slightly stale value
return repository.findById(id)
.orElseThrow(() -> new ProductNotFoundException(id));
}
} catch (InterruptedException e) {
Thread.currentThread().interrupt();
throw new RuntimeException("Interrupted while waiting for cache lock", e);
}
}
}This pattern ensures only one instance recomputes the value, while the rest wait briefly for the freshly populated cache entry.
Solution 4: Probabilistic Early Expiration (Stale-While-Recompute)
A more advanced technique — popularized as the XFetch algorithm — has each request probabilistically decide to refresh the cache before it actually expires, with probability increasing as the entry nears expiration. This spreads out recomputation over time instead of concentrating it at the exact expiry moment.
1
2
3
4
5
public boolean shouldRecomputeEarly(long ttlRemainingMillis, long totalTtlMillis, double beta) {

    double delta = /* time taken to recompute the value, tracked historically */ 50;

    double random = ThreadLocalRandom.current().nextDouble();

    return (delta * beta * Math.log(random)) >= ttlRemainingMillis - totalTtlMillis;

}
This is more complex to implement but is highly effective for very hot keys with expensive recomputation costs.
Solution 5: Stagger Cache Warm-Up
If you pre-populate cache entries in bulk (e.g., on application startup or via a scheduled job), avoid writing them all with the same timestamp and TTL. Spread the writes over a short window, or assign TTLs relative to each entry's actual last-access or last-update time rather than a single batch job's start time.
Putting It Together: A Practical Configuration
For most Spring Boot + Redis applications, a solid baseline is:
- Jitter on every TTL (Solution 1) — cheap, always-on protection.
sync = trueon@Cacheablemethods for single-instance coordination (Solution 2).- Distributed locks (Redisson) for hot keys shared across instances (Solution 3).
- Reserve probabilistic early expiration (Solution 4) for your highest-traffic, most expensive-to-recompute keys.
Conclusion
A uniform TTL across all cache entries is a subtle trap: it works fine at low traffic but creates synchronized load spikes as usage grows. By adding jitter, coordinating recomputation with
sync = true or distributed locks, and staggering cache population, you can keep your Spring Boot application's cache layer smooth and predictable — protecting your database from the very bursts caching was supposed to prevent.Series: WILT- What I Learned today (2 articles)
- 1Why a Single TTL for All Cached Data Can Overload Your Server & How to Fix It in Spring Boot This article
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article