
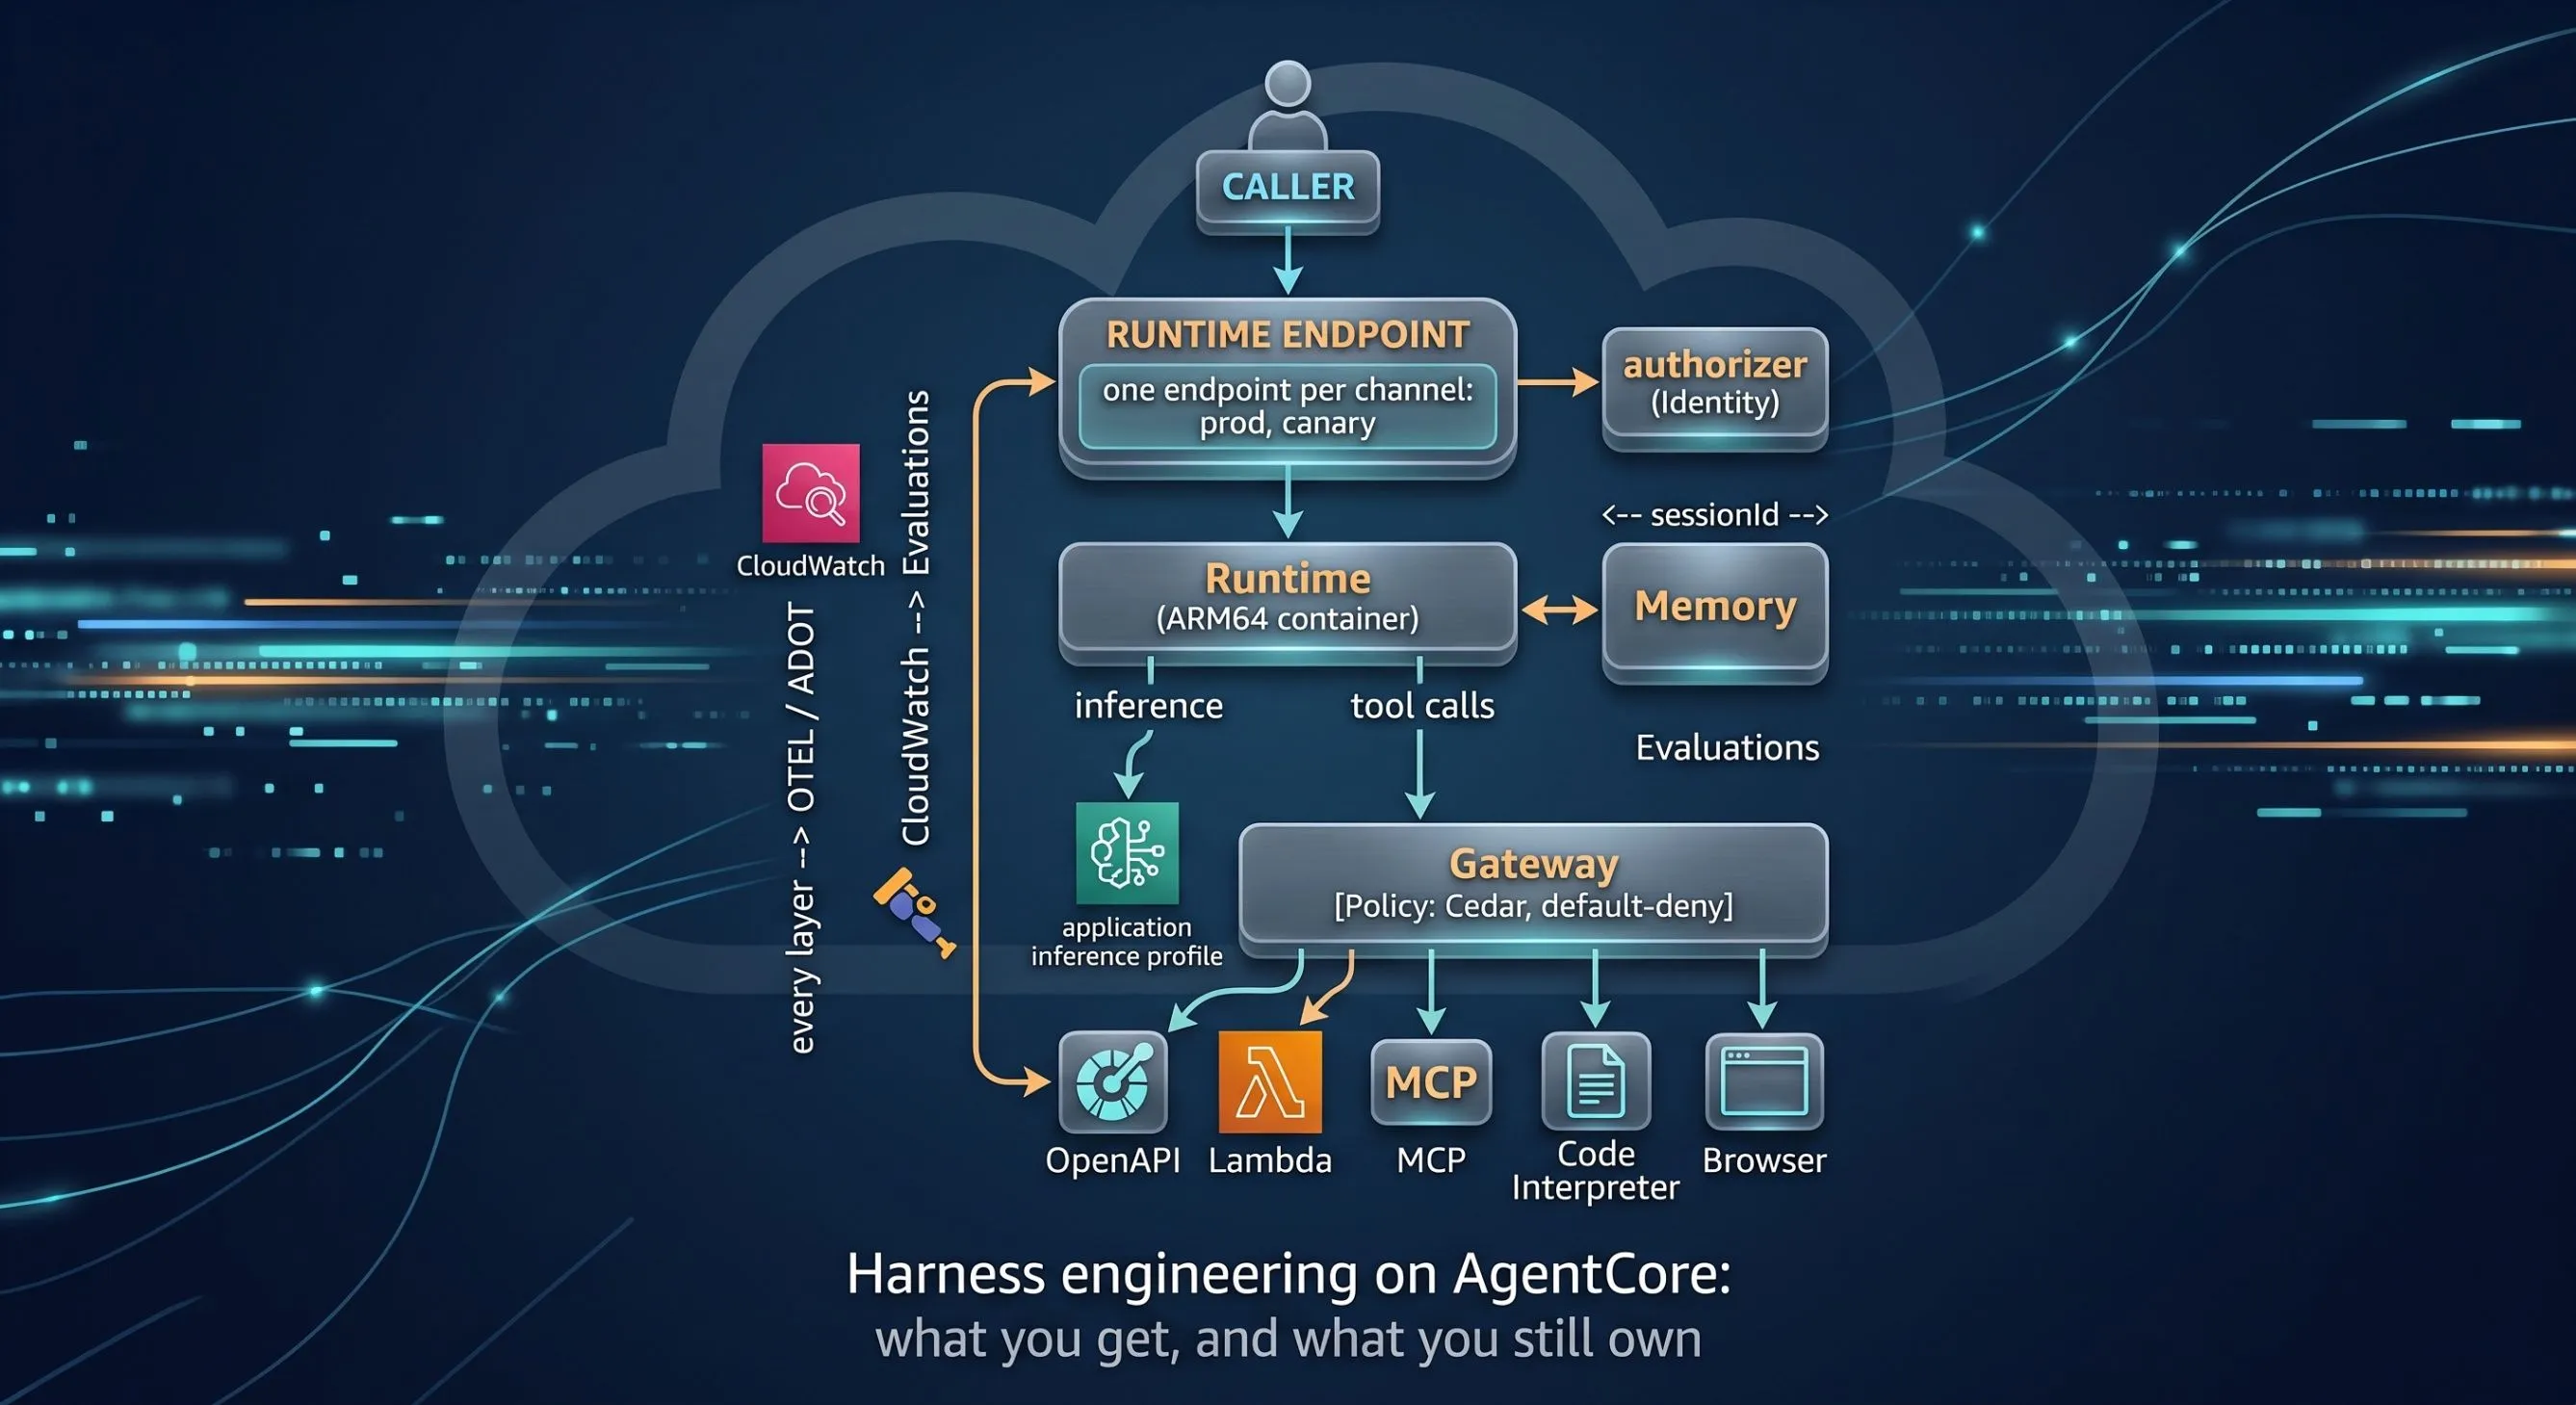
Harness engineering on AgentCore: what you get, and what you still own
Moving an autonomous AI agent into production shifts the core engineering challenge from prompt design to harness engineering—managing runtimes, tool permissions, memory, cost controls, and deployment safety. Drawing from real-world metered Bedrock runs, this post breaks down crucial runtime behaviors and the missing controls you must build yourself. It shares hard-learned lessons and practical strategies to optimize your architecture and prevent unexpected cost spikes before they hit your bill.
Harness engineering on AgentCore: what you get, and what you still own
When you build a production autonomous agent, the hard part moves quickly from prompting the model to harness engineering — the runtime, tool wiring, memory, cost controls and deployment path that surround the model and govern how it behaves. The prompt decides what your agent says. The harness decides whether it stays inside its permissions, whether you can afford it, and whether anyone finds out when it breaks.
I can tell you the exact moment I started caring about this. Twice, actually, six weeks apart, and both times I was the last person to find out.
The first: a config change made our agent end its session the moment it tried to write out its result. Sessions ran to completion, spent money, produced nothing, and every signal said they had succeeded. Sixteen results went in the bin over four days. Nobody reported it; I found it by going and looking.
The second: we changed models. The results got better, cost per session went from about $4.75 to $8.25, and it stayed there a week before anyone spotted it. I found that one in a spreadsheet, which is a humbling place to discover you have doubled your own bill.
Neither was a prompting problem. AgentCore now supplies most of the harness, and what follows is the part it leaves to you. The numbers come from 1,242 metered runs of one of our Bedrock agents.
The architecture

A couple of gochchas first: the container has to be ARM64 or it won't start, and a runtime with no
--authorizer-configuration is an open endpoint on the internet.Past that, two things about this architecture matter more than the boxes.
The tool path and the inference path are separate, and only one of them has a policy engine on it. Everything the agent does leaves through the Gateway, and Cedar evaluates it on the way out. It's default-deny, so a tool call nobody explicitly permitted doesn't happen, and a forbid rule beats any permit you add later.
That mattered to us more than I expected it to. We went through our own agent's permissions a while back, layer by layer, and most of the alarming things came back impossible — it can't push, can't merge, can't open a PR, can't delete a branch, because nothing it holds carries write access to repository contents. But it can close a pull request. The tool is in its allowlist, the token has the scope, and the only reason it has never done it is that the prompt tells it not to. I'd been counting that as a control. It isn't one: a model can be argued out of a prompt, and a bug in your own loop never reads it in the first place.
Nothing in that diagram bounds the loop. Runtime will let an agent iterate until its invocation times out, Memory will keep accumulating, and Bedrock will keep billing for all of it.
1. The 40× re-billing problem
That unboundedness is where the second incident came from. After upgrading from Claude Opus 4.8 to Opus 5 on Amazon Bedrock, our per-session cost doubled. We assumed the newer model simply thought more, and that thinking cost money.
We were wrong. Taking the bill apart across those runs showed where the money had actually gone:
| Component | Share of spend | Median per session |
|---|---|---|
| Cache read | 53% | 9.2M tokens |
| Output | 27% | 89k tokens |
| Cache write | 19% | 228k tokens |
| Fresh input | 0.2% | 2.0k tokens |
Genuinely new input accounted for just 2,000 tokens a session. Almost every dollar went on re-reading a transcript the model had already read.
Dividing cache reads by cache writes yields your context replay multiplier — how many times you re-pay for admitting the same context. After the upgrade, our median multiplier hit 40×, up from 29×.
One session, 83 turns. The left column is context accumulating; the sweep is all of it being re-read on the current turn. The bar on the right is what you actually pay for.
Because
cache_reads ≈ average context size × turns, both terms count — and turns were the one that moved: 83 per session on Opus 5 against 60 on Opus 4.8.On Bedrock, cache writes cost 1.25× the base input price, while reads cost 0.1×. With a 40× multiplier, admitting 1M tokens costs 1.25 for the initial write plus 4.0 for the reads, totalling 5.25× the base input price. Caching is saving you from a 40× bill, and a million tokens of context still costs five times what the input price alone would suggest.

None of this applies to a short agent. An agent that answers in three turns has almost nothing to replay: you pay 1.25× to write the context once and 0.1× on each of a handful of reads, which lands near 1.75× all in. Context is a rounding error at that point, and output is what to watch instead — output has no cache to discount it, so every token is billed at the full rate every time.
You don't have to guess which case you're in.
CacheReadInputTokens and CacheWriteInputTokens are both published to Amazon CloudWatch under the AWS/Bedrock namespace, so pull the two, divide, and you have your own multiplier. Down near 5, your cost lives in what the agent outputs, so tune the generation. Up near 40, it lives in what the agent re-reads, and the only thing that moves the number is fewer turns.2. Knowing which version produced what
The first incident belongs here. A config change shipped, every run came back healthy, and nobody knew for four days — there was no canary arm to compare against, and nothing anywhere recording which version had produced what.
We've shipped application code behind flags for years: canary it, watch the error rate, roll it back. Then we started editing the file that decides how the agent thinks, merging it, and letting it go live everywhere on the next invocation.
Evaluations closes part of that gap. On-demand evaluation can run a batch against a fixed dataset, which is regression testing for prompts. Online evaluation samples live traffic continuously — start at 5–10%, because every evaluation is itself a model invocation, and sampling everything means paying for a second model call on every run. You can score each run for helpfulness, faithfulness and harmfulness, and write custom evaluators at tool-call, trace or session level — useful for spotting that a recent change broke a tool's usage pattern or bloated the context.
Evaluations reads specific OTEL attributes — agent input, agent output, tool calls with their inputs and outputs, per-step latency. Miss those in your ADOT instrumentation and it won't be able to score anything.
What Evaluations does not do is record which version produced a given trace. You'll have to do that binding yourself. With AgentCore Runtime you can publish a beta endpoint and stamp the image version into your traces.
3. Attribution has to exist before the spend
Cost Explorer will tell you what Bedrock cost you last month. It won't tell you which agent spent it.
The fix: wrap the model in an application inference profile, tag it with the app or agent it belongs to, and call that profile's ARN from your agent instead of the bare model ID. Tags aren't retroactive, which is why this has to be in place before the spend you want to explain.
You can go a step further and enforce it, but not by denying direct model access outright — invoking a profile authorises the underlying foundation model too, so a blanket deny blocks your tagged path along with the direct one. Condition it instead:
bedrock:InferenceProfileArn lets you permit foundation-model invocation only when the call arrives through one of your profiles.Wrapping up
If you're standing up an agent on AgentCore now, the thing worth knowing is which parts can't be done later.
Give it a tagged inference profile before it makes a single call. Cost allocation tags only apply to spend recorded after you switch them on, so a profile added in month two tells you nothing about month one. Stamp the image version into your traces on the first deploy, for much the same reason — Evaluations will happily score a trace, but it won't tell you which version produced it, and a trace that didn't record that can't be told afterwards. While you're in the OTEL config, add the attributes Evaluations wants — agent input, output, tool calls, per-step latency — whether or not you plan to score anything yet.
Then divide cache reads by cache writes and put it on a graph. It'll be a flat, dull line until the week someone swaps the model, and that's the week you'll be glad it was already there.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article