
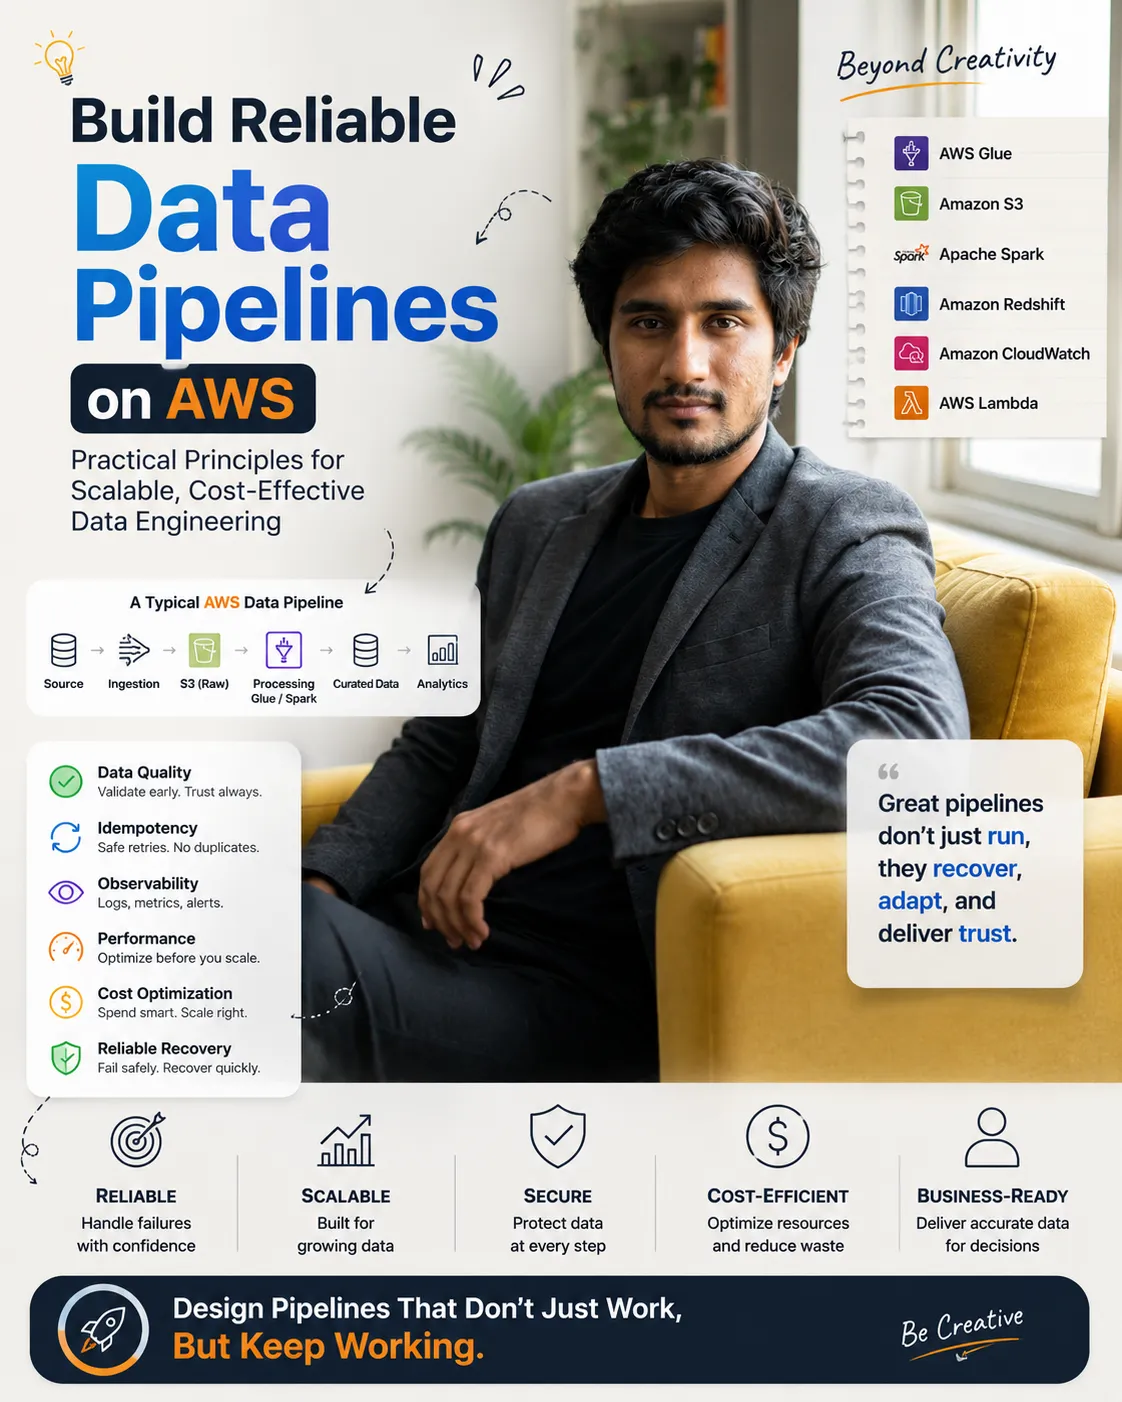
From Failed Jobs to Reliable Pipelines: A Practical Guide to AWS Data Engineering
Data pipelines rarely fail for just one reason. This article explains a practical approach to building reliable AWS data pipelines by focusing on data quality, monitoring, retries, performance, cost optimization, and operational best practices.

Data Engineer | AWS | Python | SQL | PySpark | AWS Glue | Redshift | Airflow | Snowflake
From Failed Jobs to Reliable Pipelines: A Practical Guide to AWS Data Engineering
Building a data pipeline is not only about moving data from one place to another.
A pipeline may work perfectly during development, but production brings a different set of challenges:
- Jobs start taking longer.
- Input data suddenly increases.
- Bad records break transformations.
- A downstream service becomes unavailable.
- A pipeline succeeds but produces incorrect data.
- Cloud costs increase without anyone noticing.
A reliable data pipeline needs to handle these situations gracefully.
In this article, we will look at a practical approach to building and operating reliable data pipelines on AWS.
1. Start With a Clear Pipeline Architecture
A typical AWS data pipeline can look like this:
Plain text
Source Systems|vAmazon S3|vIngestion / Processing|vAWS Glue / Apache Spark|vCurated Data|vAmazon Redshift / Athena|vBI / Analytics
It is useful to separate the pipeline into different layers:
- Raw layer → Store data as received from the source.
- Processed layer → Clean and transform the data.
- Curated layer → Store business-ready data.
- Consumption layer → Make data available for reporting and analytics.
This structure also makes debugging and reprocessing easier.
If a transformation fails, you can restart the processing from the raw data instead of requesting the source data again.
2. Add Data Quality Checks
A job can complete successfully while still producing incorrect data.
For example, a pipeline may process 10 million records successfully, but if 20% of the records have a null customer ID, the output may not be usable.
Common data quality checks include:
Plain text
Record countNull checksDuplicate checksSchema validationData type validationBusiness rule validationReferential integrity
For example:
Plain text
from pyspark.sql.functions import colinvalid_records = df.filter(col("customer_id").isNull())if invalid_records.count() > 0:raise Exception("Data quality check failed")
In production, avoid unnecessary actions such as repeated
count() operations because they can increase processing time.The purpose of these checks is to prevent incorrect data from reaching downstream systems.
3. Make Pipelines Idempotent
Idempotency is important when designing production pipelines.
Suppose a daily pipeline processes:
Plain text
2026-08-30
The job fails after writing some output.
If you restart the job and it simply appends the data again, duplicate records can be created.
One approach is to partition the data by business date:
Plain text
s3://data/processed/orders/date=2026-08-30/
When rerunning the pipeline, replace the affected partition instead of blindly appending the data.
This makes retries and recovery safer.
4. Handle Failures With Retries
Some failures are temporary and can be handled through retries.
Examples include:
Plain text
Network timeoutTemporary service unavailabilityThrottlingDatabase connection failure
A simple retry flow can look like this:
Plain text
Attempt 1|Failure|Wait|Attempt 2|Failure|Wait longer|Attempt 3|Failure|Alert + Stop
Retries should be limited.
For example, a temporary network timeout may be worth retrying, but a malformed input file will usually continue to fail until the underlying data is fixed.
5. Monitor More Than Job Status
Monitoring only whether a job succeeded or failed is not enough.
Useful pipeline metrics include:
Plain text
Job durationInput record countOutput record countFailed recordsData freshnessProcessing latencyCPU / memory utilizationShuffle volumeCloud cost
For example, if a Spark job normally takes 15 minutes but suddenly takes 60 minutes, the job may still finish successfully, but something has changed.
Possible causes include:
- Input data increased significantly.
- A join became more expensive.
- Data became skewed.
- Partitioning changed.
- An inefficient transformation was introduced.
- The cluster does not have enough resources.
Monitoring these metrics helps identify such changes early.
6. Optimize Spark Jobs Before Increasing Resources
When a Spark job becomes slow, increasing the cluster size should not always be the first step.
First check the execution plan and identify where the time is being spent.
Broadcast Joins
If one dataset is small enough, broadcasting it can reduce shuffle during a join.
Plain text
from pyspark.sql.functions import broadcastresult = large_df.join(broadcast(small_df),"customer_id")
This works well when the smaller dataset can fit comfortably in executor memory.
Select Only Required Columns
Instead of:
Plain text
df.select("*")
select only the columns needed for the next step:
Plain text
df.select("customer_id","order_id","amount")
Processing fewer columns reduces data transfer, memory usage, and I/O.
Reduce Unnecessary Shuffles
Large joins,
groupBy , and some aggregations can cause expensive shuffle operations.Checking the Spark execution plan can help identify these issues before increasing cluster resources.
7. Use Caching Carefully
Caching can help when the same DataFrame is reused multiple times.
For example:
Plain text
df = expensive_transformation(input_df)df.cache()df.count()df.filter(...).write(...)df.groupBy(...).count()
Caching is not useful for every DataFrame.
If the DataFrame is used only once, caching can consume memory without providing much benefit.
Use caching when the data is expensive to recompute and is reused multiple times.
8. Design for Observability
When a production job fails, the engineer should be able to identify the problem quickly.
A basic monitoring flow can look like this:
Plain text
Pipeline Status|vLogs|vMetrics|vAlerts|vRoot Cause
An alert should contain enough information to start the investigation:
Plain text
Pipeline: customer_daily_loadStatus: FAILEDExecution time: 02:15 UTCFailed stage: transformationInput date: 2026-08-30Error: Schema mismatch
Good alerts reduce the time required to find and fix production issues.
9. Control Cloud Costs
Performance and cost should be considered together.
Some practical ways to reduce unnecessary AWS costs include:
- Process only incremental data.
- Avoid unnecessary full-table scans.
- Use columnar formats such as Parquet.
- Compress large datasets.
- Remove unnecessary intermediate data.
- Right-size compute resources.
- Stop resources when they are not required.
- Monitor pipeline costs.
For example, if only one day's data changes, processing the entire historical dataset every day can result in unnecessary compute and storage costs.
10. Make Pipelines Easy to Recover
Production failures are unavoidable, so the pipeline should be designed for recovery.
Before deploying a pipeline, consider:
- What happens if the job fails halfway through?
- Which data is affected?
- Can only the failed partition be processed again?
- Will a rerun create duplicates?
- How will the recovered data be validated?
- How will downstream systems know that the data is ready?
A pipeline that can be safely restarted is easier to operate and maintain.
Final Thoughts
A reliable AWS data pipeline should focus on:
- Reliability → Handle failures safely.
- Data quality → Validate data before it reaches downstream systems.
- Observability → Make failures and performance issues easy to identify.
- Scalability → Handle increasing data volumes.
- Idempotency → Allow safe retries and reruns.
- Cost optimization → Avoid unnecessary processing and resource usage.
When designing a pipeline, don't focus only on getting the job to run successfully.
Also consider what happens when the data changes, the job fails, processing becomes slower, or the pipeline needs to be rerun.
That is what makes a pipeline easier to operate in production.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article