
CloudWatch Unified Data Management, Part 2: Correlate Network and Control-Plane Activity in One Query
Part 2 of a two-part series. Part 1 covered what the feature is, how logs get in, how they're normalized, and how to query a single source in place with Athena. This part is about querying across sources, the query languages, and metrics.
Series: CloudWatch Unified Agent (2 articles)
- 2CloudWatch Unified Data Management, Part 2: Correlate Network and Control-Plane Activity in One Query This article
In Part 1 the logs were in one store and queryable as Iceberg tables. That's the setup. The reason it matters is the question I opened the series with: an internal IP was making network connections it shouldn't, and I needed to know whether that same IP had also touched the AWS control plane. Two sources, one question, and the answer used to take an hour of exporting and spreadsheet work.
Here it's one query. This part shows two ways to run it and when to reach for each.
Querying: One Dataset, Your Choice of Language
Once the data is unified you query it without moving it. CloudWatch gives you a few ways in:
- Natural language, through an AI query generator that writes the query for you
- LogsQL, PPL, and SQL through a single interface, so you use whichever you already know
- Facets, a filtering panel that extracts fields (source, application, account, Region, log type) for the selected time window and lets you drill down by clicking instead of typing
Facets is the one to try first. It reads the shape of your data for the chosen time range and hands you the fields worth filtering on, which is faster than remembering field names across a dozen log types. You can save a facet-and-value selection as a query and reuse it.
The Correlation: Same IP, Network and Control Plane
Here's the question my incident needed answered: is an IP making suspicious network connections also performing control-plane actions like creating users or opening security groups? There are two good ways to ask it, and they suit different teams.
Option A: Cross-source SQL in Athena
Both sources land in the
aws-cloudwatch S3 Tables bucket as Iceberg tables: VPC Flow Logs as amazon_vpc__flow, CloudTrail management events as aws_cloudtrail__management. Once they're there, the correlation is a join on the shared IP:1
2
3
4
5
6
7
8
9
10
SELECT ct.eventname, ct.eventsource, count(*) AS calls
FROM "s3tablescatalog/aws-cloudwatch"."logs"."aws_cloudtrail__management" ct
JOIN (
SELECT DISTINCT srcaddr
FROM "s3tablescatalog/aws-cloudwatch"."logs"."amazon_vpc__flow"
WHERE srcaddr IS NOT NULL
) f ON ct.sourceipaddress = f.srcaddr
WHERE ct.sourceipaddress = '<suspect-ip>'
GROUP BY ct.eventname, ct.eventsource
ORDER BY calls DESC;This reads as: take the IP from the network logs, and show every control-plane action it took, grouped. The result is the suspect IP's API footprint in one list.
Two things to know about the query. The join key is
ct.sourceipaddress = f.srcaddr, not a tidy shared column name, because the two schemas name the field differently even after they're in the same store. And the join goes against a SELECT DISTINCT srcaddr subquery on purpose: a plain row-level join fans out to one row per flow-record times API-call pair, which buries the answer in duplicates. Grouping by event name collapses it back to the footprint you actually want to read.If you want the raw per-event rows instead,
SELECT ct.eventtime, ct.eventname, ct.useridentity.arn AS actor, f.action from the same join works. Confirm columns in your account with a SELECT * first, because the schema is the live Iceberg schema and flow-log columns materialize on a delay, as covered in Part 1.If you enabled OCSF normalization on the sources, both sides expose
src_endpoint.ip and you join on that instead. That's the whole point of normalization: the field means the same thing on both sides.
The correlation query in Athena: the suspect IP's control-plane calls grouped by event name and source

The full result list, from DescribeAlarms down through the observability and Glue calls made from that IP
Option B: The same question in Logs Insights
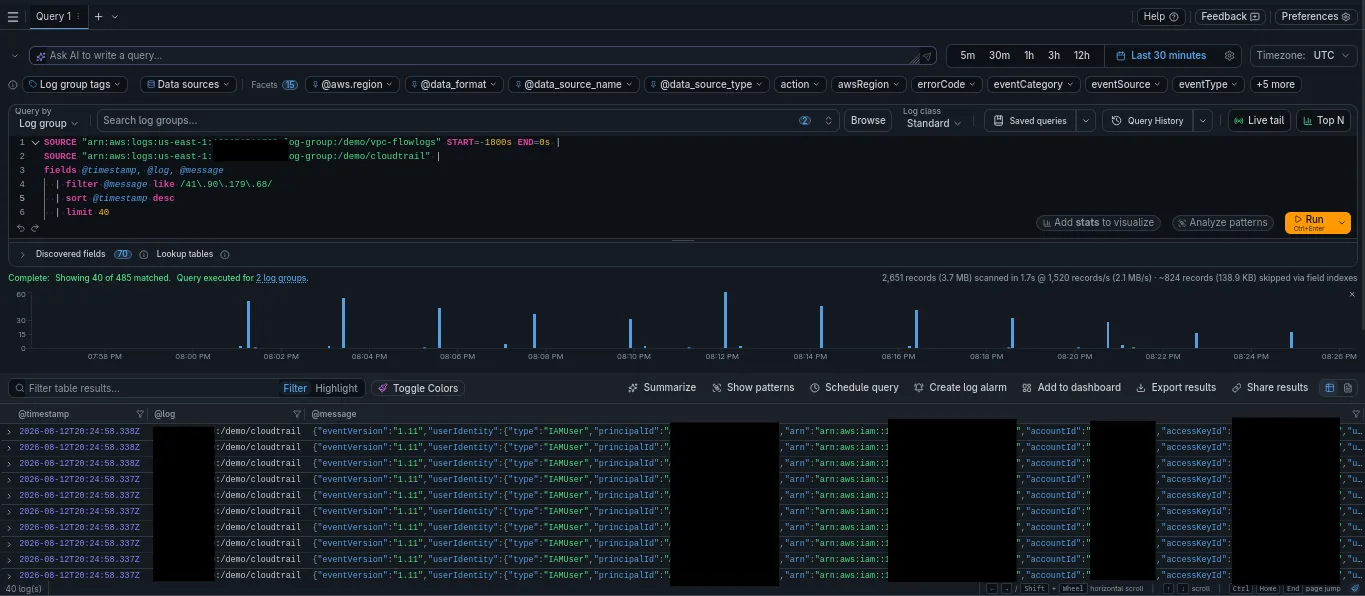
If you don't want to wait for Iceberg materialization, or you're already in the console, run it against the log groups directly. Logs Insights queries multiple log groups at once, so pointing it at both the flow-logs and CloudTrail groups and filtering on the IP surfaces every hit from both sources in one result:
1
2
3
4
fields @timestamp, @log, @message
| filter @message like /<suspect-ip>/
| sort @timestamp desc
| limit 40
The
@log column tells you which source each row came from. You'll see the flow-log lines where that IP hit your instance next to the CloudTrail events where it called the API. Same correlation, no catalog setup, available as soon as the logs arrive.
Logs Insights querying both the flow-logs and CloudTrail log groups at once, filtered to the suspect IP
Which to use: Athena when you want structured SQL, joins with business tables, or large time ranges. Logs Insights when you want an answer now and you're working interactively. Same data underneath either way.
Generating the activity safely
If you want to reproduce this, you need one IP to appear in both sources. Make a few network connections toward an instance and a couple of API calls from the same host:
1
2
3
4
for p in 22 80 443; do curl -s -m 3 -o /dev/null http://<instance-public-ip>:$p/; done

aws ec2 describe-instances --region <region> --max-items 1
aws iam list-users --region <region>
The blog-demo instinct is to reach for
create-user and opening SSH to 0.0.0.0/0 to make the CloudTrail events look "sensitive." Don't. Read-only calls like describe-instances and list-users are management events too, they show up in CloudTrail the same way, and they don't leave a real user or an internet-open port behind if you forget to clean up. The correlation works on the source IP, not on how alarming the action is.Metrics Get the Same Treatment
The unification isn't only about logs. On the metrics side, CloudWatch now takes OpenTelemetry metrics natively: you publish through the OTLP endpoint with no custom conversion layer, then combine your custom OTel metrics with AWS vended metrics from 70-plus services and query them together with PromQL.
If you've been running a separate Prometheus or an OTel collector pipeline just to get application metrics next to AWS metrics, that plumbing shrinks.
Where This Fits, and Where It Doesn't
Reach for it when:
- Your security and ops data live in different tools and correlation means manual export
- You're paying a SIEM per-gigabyte to ingest cloud and SaaS logs you already have
- You run multi-account, multi-Region and want org-level collection instead of per-account setup
- Different teams want different query tools over the same logs
Don't expect it to replace everything:
- It's ingestion, normalization, and query, not a full SIEM. Detection content, case management, and SOAR workflows still live in a dedicated security platform, though this can feed them cheaper, cleaner data.
- It's not in GovCloud (US) or the China Regions yet. Check
AWS Capabilities by Regionbefore you plan around it. - Cost still tracks CloudWatch Logs ingestion, storage, and query usage. "One store" reduces duplication, but high-volume ingestion is still a line item to model.
Things to Know Before You Build
Iceberg access is read-only. The
aws-cloudwatch S3 Tables bucket is for querying, not for writing back. Treat it as a serving layer for analytics engines.Athena needs the catalog registered. The Iceberg tables are invisible to Athena until you register the
aws-cloudwatch bucket as a federated Glue catalog. Skipping it is the most common reason a first query fails with Catalog not found. The command is in Part 1.Materialization lags and there's no backfill. Only events after association appear, and different sources commit at different speeds. CloudTrail showed up fast for me; the flow-logs per-flow columns took longer. Give it 15 to 30 minutes before trusting an empty result.
Normalization quality depends on the processor chain. OCSF conversion is managed for supported sources, but custom sources lean on Grok and field operations you configure. Budget time to get the parsing right for anything AWS doesn't map for you.
Org-level collection needs the AWS Organizations wiring. Cross-account, cross-Region ingestion assumes your accounts are under an organization with the right delegation. Standalone accounts get less of the automatic-collection benefit.
Who This Is For
The clearest fit is the team that has quietly become a data-integration shop without meaning to. If you maintain ETL jobs whose only purpose is copying logs from one store to another so they can be queried together, this deletes that work. If your incident response starts with "which tool has that log," this puts them in one.
Security teams get cloud, endpoint, and identity data in one normalized schema. Ops teams get logs and OTel metrics side by side. Compliance gets a queryable store without a bespoke export. The through-line is correlation: the value shows up the moment you join two sources that used to live apart.
Series: CloudWatch Unified Agent (2 articles)
- 2CloudWatch Unified Data Management, Part 2: Correlate Network and Control-Plane Activity in One Query This article
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article