
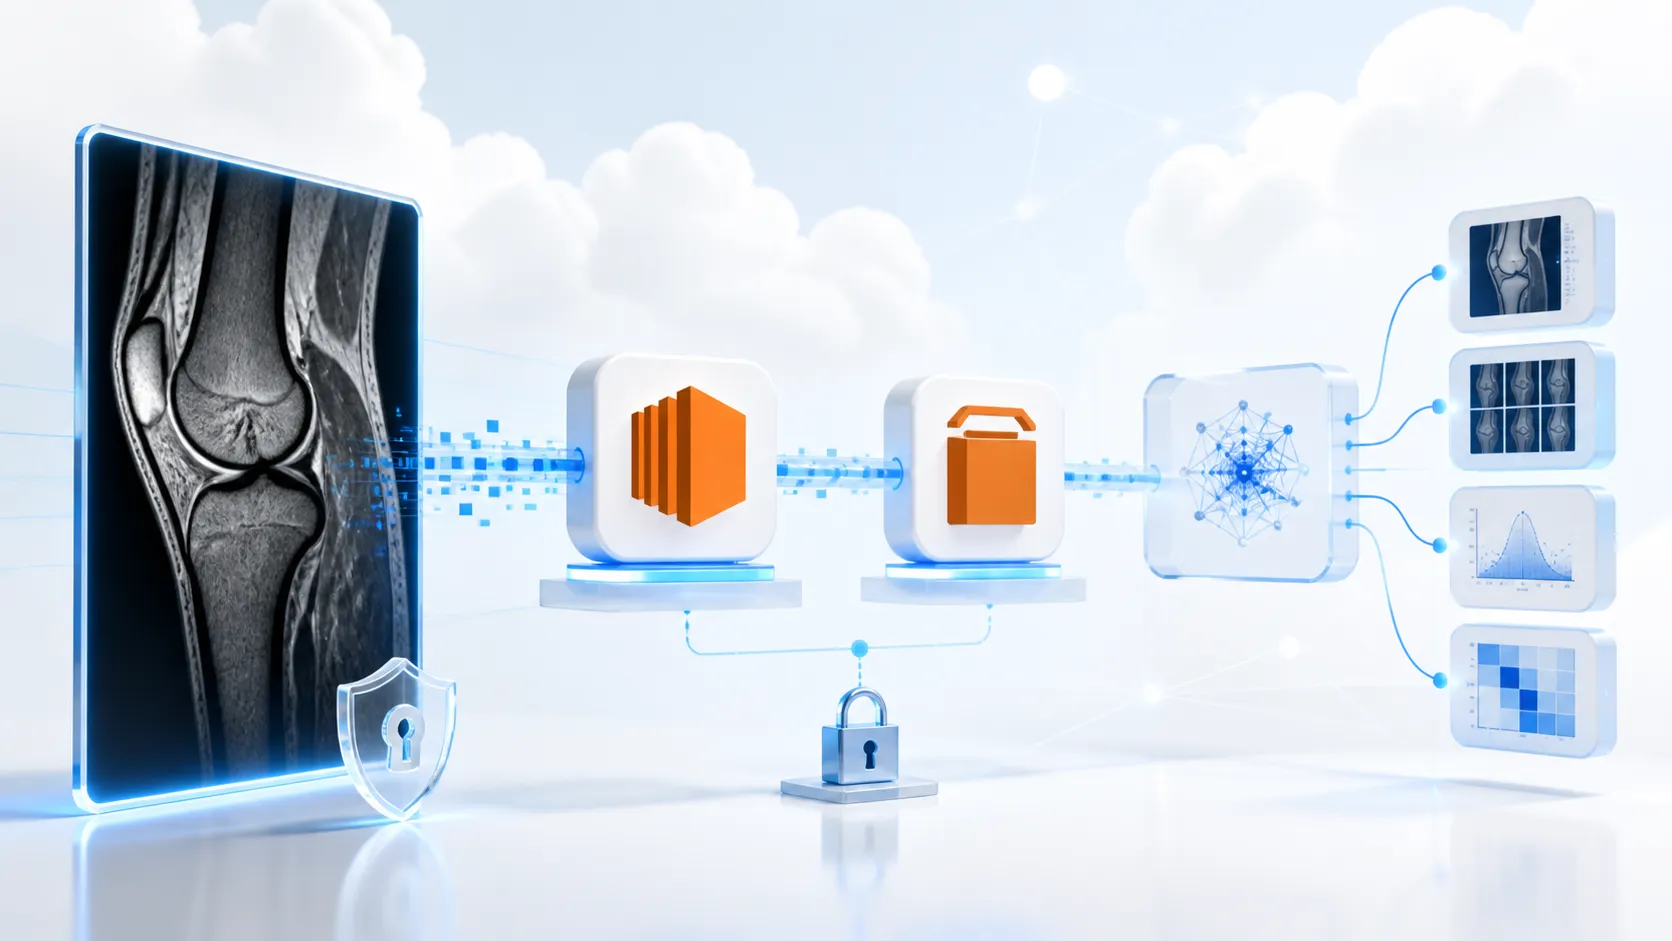
From a 247 GB Compressed Kaggle Archive to Training-Ready Knee MRI Data on AWS
How I built a secure, reproducible, fail-closed ingestion pipeline for multimodal knee MRI model development using Amazon EC2, Amazon S3, AWS Secrets Manager, AWS Systems Manager, and Amazon SageMaker AI.
The first expensive mistake in a medical-imaging competition is often made before the first model trains.
It happens when data preparation is treated as a collection of notebook cells instead of a controlled system. A partially downloaded archive is mistaken for a valid dataset. DICOM series are decoded differently between experiments. Patient studies leak across validation folds. Preprocessing is repeated during every epoch. A long-running machine is left online after a failure. Credentials find their way into notebook metadata.
For the RSNA Knee Abnormality Detection competition, I wanted the opposite: one reproducible path from the original competition archive to a validated, training-ready MRI cache. The result is an AWS-native, one-shot ingestion pipeline built around Amazon EC2, Amazon S3, AWS Secrets Manager, AWS Systems Manager, and Amazon SageMaker AI.
This article describes the design, the clinical and machine-learning decisions behind it, and the guardrails that make the pipeline safe to rerun.
The competition data is governed by its own rules and license. The architecture below is reusable, but access to any dataset must follow the applicable terms.
Why ingestion is part of model quality
The task is multilabel classification of twelve clinically important knee abnormalities from MRI examinations and their associated radiology reports. The evaluation metric is macro-averaged ROC AUC, which gives each target equal importance.
That creates several data-engineering requirements:
- Rare findings cannot be allowed to disappear from a validation fold.
- Missing labels cannot silently become negative labels.
- Multiple examinations from the same patient must not cross fold boundaries.
- Scanner, institution, field strength, and acquisition protocol can become hidden shortcuts.
- Slice order and physical pixel spacing matter when constructing an image representation.
- Preprocessing must stay identical across folds and experiments.
A fast model trained on a leaky split is not a strong model. It is a confident measurement error.
The architecture
The ingestion worker is deliberately separate from the training environment. Ingestion is CPU-, network-, and storage-heavy; training is GPU-heavy. Paying for a GPU while downloading, validating, and decompressing hundreds of gigabytes would be wasteful.
Pipeline at a glance
- Package Git-tracked source into a versioned Amazon S3 bundle.
- Download the Kaggle archive on a disposable Amazon EC2 worker using a token from AWS Secrets Manager.
- Validate the archive, preserve the immutable raw copy in Amazon S3, and extract metadata and DICOM files.
- Run the DICOM audit and build patient-safe folds.
- Build an eight-part, 320-pixel MRI cache with checksums and manifests.
- Approve the cache through a fail-closed gate before Amazon SageMaker AI training.
- Operate the worker through AWS Systems Manager, persist logs and status, and terminate it automatically.
The S3 layout is a contract rather than a miscellaneous bucket:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
s3://PROJECT_BUCKET/
├── metadata/
│   ├── source/GIT_SHA/
│   ├── dataset-v2/
│   └── audit-v2/
├── raw/
│   └── competition-v2/
├── prepared/
│   └── cache-v2/
│       ├── full-320/
│       └── manifests/
├── experiments/
│   └── ingest-v2/INSTANCE_ID/
├── checkpoints/
└── final/
Versioned prefixes are important. A cache is not "the data"; it is a derived artifact produced by a specific implementation. A new preprocessing contract gets a new prefix instead of silently overwriting the old one.
1. Package the exact source that will run
Before launching the worker, the repository is packaged from Git-tracked files only. The virtual environment, local data, credentials, Git history, and ignored artifacts are excluded. The bundle is named with the current commit SHA, hashed, and uploaded under
metadata/source/GIT_SHA/.The EC2 launch script refuses to start if that exact source bundle is not present. It also checks the target AWS account before creating compute. These two checks prevent surprisingly common failures: running uncommitted local code and launching expensive infrastructure in the wrong account.
This gives every ingestion run a reproducible answer to a basic question:
Which code produced these prepared objects?
2. Use a disposable worker with no inbound access
The production worker uses an on-demand, general-purpose Amazon EC2 instance with a 2 TiB encrypted gp3 volume. The volume is large enough to hold the compressed archive, extracted DICOM data, temporary cache objects, and operating-system headroom at the same time.
The security group has no inbound rules. There is no SSH key and no open administrative port. Operational access is provided through AWS Systems Manager Session Manager and Run Command. The instance requires IMDSv2, receives a least-privilege IAM role, and terminates when the pipeline exits.
The EBS volume is configured with
DeleteOnTermination=true, so temporary extracted medical images do not remain attached to an abandoned instance.The worker also receives a 48-hour scheduled shutdown backstop. Normal completion triggers termination much earlier, but the backstop protects against a process that hangs outside the expected error path.
3. Keep the Kaggle token out of code and notebooks
The competition token is stored in AWS Secrets Manager. The instance role can read only that secret and only the S3 prefixes required by the ingestion job.
At download time, the worker retrieves the token into an environment variable, invokes the Kaggle CLI, and immediately unsets the variable afterward. The token is never written to the source bundle, user data, S3 manifests, or logs.
The corresponding IAM policy is intentionally narrow:
- list only project prefixes;
- read the versioned source bundle and project inputs;
- write only the v2 raw, audit, cache, and ingestion-status prefixes;
- require server-side encryption on every write;
- read one named secret; and
- manage multipart uploads only for the large raw and cache destinations.
Least privilege is especially useful here because the worker is intentionally ephemeral. It should have enough authority to complete one job, not become a general-purpose data administrator.
4. Treat ingestion as an explicit state machine
The worker writes its current stage to a small local file. The implemented stages are:
1
2
3
4
5
6
7
8
9
10
11
install_dependencies
install_project
download_competition
download_validated_raw_from_s3  # when reusing the existing raw copy
verify_and_upload_raw
extract_competition
upload_dataset_metadata
rebuild_audit_and_folds
build_cache_v2
validate_cache_v2
complete
The shell entry point uses strict failure behavior:
1
set -euo pipefail
An exit trap runs for both success and failure. It records the final stage, exit code, timestamp, instance ID, and complete log under
experiments/ingest-v2/INSTANCE_ID/, then shuts the machine down.This structure makes failures actionable. "The pipeline failed" is vague. "The pipeline failed while validating cache part 6" tells us where to look and whether earlier durable artifacts can be reused.
5. Validate before preserving the raw archive
After the download completes, the worker requires exactly one competition ZIP. It runs a full archive integrity test before extracting or promoting anything.
The validated archive is uploaded to Amazon S3 using server-side encryption, SHA-256 checksum support, and the S3 Intelligent-Tiering storage class. The worker then compares the local file size with the remote object's content length. A mismatch fails the run.
Only after the remote raw copy passes validation does extraction begin. The local ZIP is deleted after successful extraction to recover working-disk headroom.
This ordering matters. The raw S3 object is the durable recovery point. If preprocessing changes later, the entire cache can be rebuilt without downloading the competition data again.
6. Audit DICOM headers before constructing folds
Medical-imaging validation has a failure mode that ordinary image classification often does not: one patient can have multiple studies, and one study can contain multiple series.
The audit reads one representative DICOM header per series without loading pixel data. It records acquisition descriptors such as manufacturer, scanner model, magnetic-field strength, series description, protocol, image type, matrix dimensions, pixel spacing, slice thickness, and transfer syntax.
Raw patient identifiers are not written to the audit output. Instead, a deterministic SHA-256-derived group key is created for patient grouping. Institution and scanner descriptors are also converted into stable site groups for stratification. If
PatientID is absent, the audit falls back conservatively to one group per study and records that limitation explicitly.At study level, the audit checks that every series agrees on the patient group. A disagreement is treated as an error rather than quietly choosing one value.
Patient-safe, partially labeled multilabel folds
The five-fold assignment is deterministic and group-safe. Its balancing objective considers four feature blocks:
- Positive counts for all twelve targets.
- Observed-label counts for all twelve targets.
- Site and demographic strata.
- Overall fold size.
Missing targets remain missing. They are never converted to zero.
Rare positive labels receive the strongest weight, followed by label coverage, acquisition strata, and fold size. All rows for the same patient group are assigned together. The result is a validation design that better reflects the real objective: generalization to unseen examinations, not memorization of patient or scanner identity.
7. Cache physical MRI volumes, not arbitrary screenshots
Repeated DICOM decompression during every training epoch is slow and creates more opportunities for preprocessing drift. The pipeline therefore builds one compact cache object per selected MRI series.
For every series, the cache builder:
- Orders the DICOM slices.
- Reads physical pixel spacing.
- Decodes and normalizes the volume.
- Resizes it to a physically informed square representation.
- Quantizes the normalized volume to unsigned 8-bit values.
- Stores the full slice stack in a compressed NumPy archive.
- Calculates a SHA-256 checksum.
- Uploads it to S3 with the checksum in object metadata.
- Deletes the local object only after a successful upload.
The cache retains the full slice axis. Training can still sample slices dynamically, but it no longer needs to parse and decompress the original DICOM files in every epoch.
The first production cache uses a 320-pixel spatial size and selects up to six series per study. Studies are deterministically partitioned into eight parts, which are processed concurrently on the same EC2 worker. This is local parallelism, not eight separate cloud machines.
Each partition is resumable. Before creating an object, the worker checks whether the corresponding S3 object already exists. Successfully uploaded objects can be reused after an interrupted run.
8. Make training wait for a positive cache gate
Object count alone is not proof that a cache is valid. When all eight partitions finish, their manifests are combined and checked.
The gate approves the cache only if:
- every expected partition manifest exists;
- each study-series pair is unique;
- every record was either uploaded successfully or safely reused remotely;
- every object has a SHA-256 checksum; and
- every object has a valid byte count.
The combined manifest records the number of studies, number of series, total bytes, upload status, object URI, and checksum. The resulting JSON gate contains an explicit boolean:
1
2
3
4
5
6
7
{
  "approve_cache_v2": true,
  "parts": 8,
  "studies": 0,
  "series": 0,
  "bytes": 0
}
The zero values above are illustrative placeholders; a real successful gate contains the observed totals.
This gate is the machine-readable precondition for the next phase. The SageMaker AI launch integration is not implemented yet; when it is added, it must refuse paid GPU work unless
approve_cache_v2 is present and true.9. Observe progress without SSH
Long downloads should be boring, but they should not be invisible. A small status command uses AWS Systems Manager to report:
- instance state and type;
- current pipeline stage;
- bytes downloaded so far;
- free disk space;
- whether the validated raw archive is present in S3; and
- the current cache object count and total bytes.
A typical early-stage snapshot looks like this:
1
2
3
4
STAGE=download_competition
DOWNLOADED_BYTES=132673175552
RAW_ARCHIVE_BYTES=0
CACHE_V2={"Objects": 0, "Bytes": 0}
Those zeros are not failures. They express the contract: the raw archive is not uploaded until download and validation complete, and the cache is not built until extraction and audit complete.
10. Put cost controls in both infrastructure and code
The project has a total budget guardrail of USD 650, divided into working envelopes:
| Category | Envelope |
|---|---|
| Storage | USD 70 |
| Data preparation | USD 40 |
| GPU training | USD 470 |
| Contingency | USD 70 |
For the initial ingestion run, the selected Mumbai-region EC2 price was recorded with its verification date. The instance has a maximum runtime, an estimated compute ceiling, a bounded EBS cost, automatic termination, and a scheduled shutdown backstop.
AWS Budgets is an alerting guardrail, not a guaranteed hard spending stop. Before every training launch, the current effective GPU price must be obtained and supplied to the project's separate
cost-plan command. That command estimates the proposed run and refuses plans that exceed the configured GPU or total-budget envelopes; it does not fetch pricing or launch training itself.For training, quota was requested for both Spot and on-demand
ml.g5.2xlarge jobs. Spot is preferred for cost efficiency; on-demand is the reliability fallback. Checkpointing and a bounded maximum run time are part of the training contract, not afterthoughts.What I would keep for the next medical-imaging project
Separate durable stages from temporary work
The source bundle, validated raw archive, audit outputs, folds, cache objects, manifests, logs, and model checkpoints are durable. Extracted DICOM files and intermediate cache files are temporary. Making that distinction early simplifies recovery and lifecycle policies.
Version derived data explicitly
If physical resizing, intensity normalization, series selection, or cache format changes, write to a new versioned prefix. Never make two different preprocessing implementations look like the same dataset.
Build validation before training
Patient grouping, label availability, rare-class balance, and scanner strata belong in ingestion. Waiting until model training to discover leakage can invalidate days of experiments.
Make success machine-readable
A human-readable log is useful. A boolean gate backed by checksums and manifests is enforceable. Use both.
Prefer disposable compute for bounded preprocessing
A one-shot EC2 worker with no inbound access, an instance role, encrypted temporary storage, terminal status artifacts, and automatic termination is easier to reason about than a long-lived manual workstation.
What comes next
Once the cache is approved, the modeling plan moves to Amazon SageMaker AI:
- self-supervised pretraining for the MRI slice encoder;
- a hierarchical model that aggregates slices into series and series into studies;
- a report model that learns from the accompanying radiology text;
- out-of-fold predictions for every component;
- per-target calibration and constrained ensembling; and
- an inference package designed for the competition's nine-hour notebook limit.
The most important output of the ingestion pipeline is not a folder of arrays. It is confidence that every subsequent experiment starts from the same validated clinical unit, the same leakage-safe folds, and the same reproducible transformation of the original data.
That confidence is part of the model.
A follow-up article covering the SageMaker AI training pipeline, validation strategy, calibration, and ensembling is coming soon.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article