
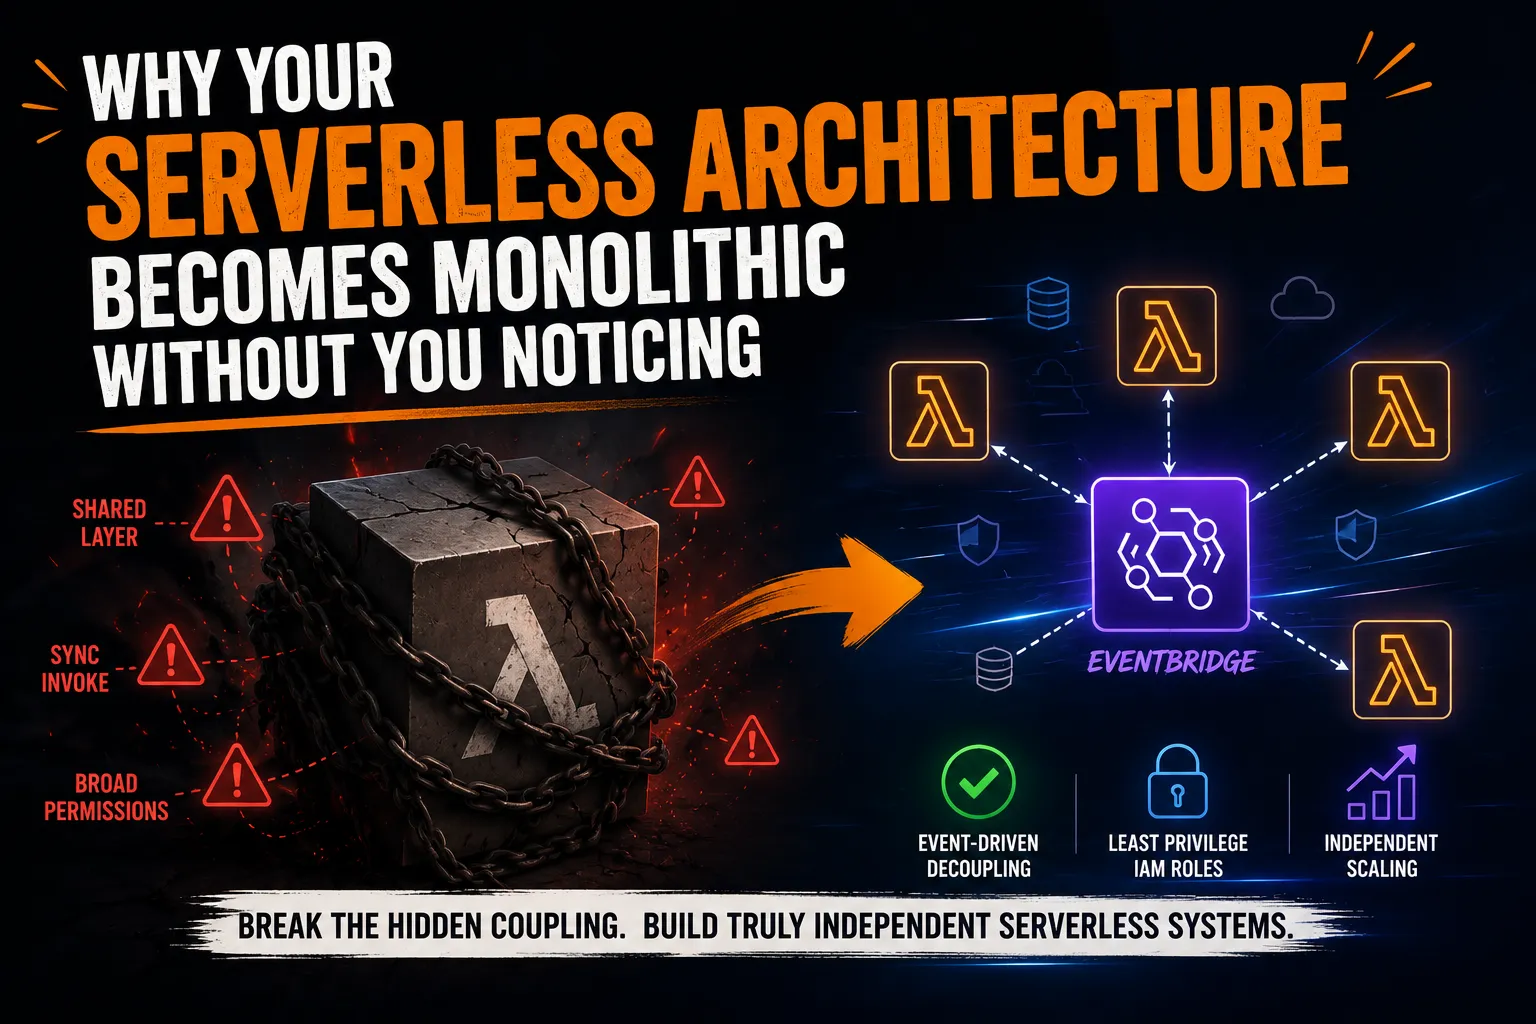
Why Your Serverless Architecture Becomes Monolithic Without You Noticing
Your Lambda functions look independent on the diagram but shared layers, sync invokes, and one IAM role can quietly turn them into a monolith.
I didn't realize my "serverless microservices" had quietly turned into a distributed monolith until I tried to deploy a one-line fix to a single Lambda function and had to redeploy eleven others just to make it safe to ship.
It's a moment almost every serverless engineer eventually hits: a change that should be isolated to one function instead ripples outward, and you're left tracing why a "small" fix suddenly needs a coordinated deploy across your entire stack.
That's the trap. Serverless doesn't force you into good boundaries; it just removes the servers that used to make bad boundaries visible. You can build something that looks like twelve independent Lambda functions on an architecture diagram and is, in practice, one tightly coupled application that happens to be split across twelve deployment units.

You get all the operational pain of a monolith (one broken piece takes down the rest, one bad deploy needs coordinated rollback) with none of the benefits (no shared runtime, no shared debugger, one log stream to grep instead of twelve). Here's how it happens, and it happens the same way almost every time.
1. The Shared Lambda Layer Becomes a Hidden Dependency Graph
Lambda layers are sold as a way to share code cleanly: put your common utilities, your DB client, your auth middleware in a layer, attach it to every function, done. Nobody talks about what happens six months later.

Every function that shares that layer now has a hidden coupling. Bump a dependency inside the layer to fix a bug in one function, and you've silently changed the runtime behavior of every other function attached to it without a single line of that function's own code changing. Your version control history says function A didn't change, but function A's behavior did change, because its dependency graph moved underneath it.
How to check if this is you — a quick audit script:
1
2
3
4
5
6
7
8
9
# list every function attached to each layer in your account/region
for layer_arn in $(aws lambda list-layers --query 'Layers[].LayerArn' --output text); do
echo "Layer: $layer_arn"
aws lambda list-functions --query \
"Functions[?contains(Layers[].Arn, \`$layer_arn\`)].FunctionName" \
--output text
echo "---"
done
If more than 3–4 functions across different bounded contexts (not just variations of the same feature) show up under one layer, you've built a shared library with extra deployment steps, not independent services.
2. Synchronous Invoke Chains ("Just Call It Directly")
Somewhere in your architecture there is probably a Lambda function that calls another Lambda function directly via
lambda:InvokeFunction, not through an event bus or a queue. It felt reasonable at the time: "it's just one call, why add EventBridge for that."
That single synchronous call is a direct runtime dependency. Function A now cannot succeed unless Function B is available, within Function A's timeout, with capacity to handle the invocation. Compare the two patterns directly:
1
2
3
4
5
6
7
8
9
10
11
12
# COUPLED: Function A blocks on Function B's availability, cold start, and timeout
import boto3, json

lambda_client = boto3.client("lambda")

response = lambda_client.invoke(
    FunctionName="function-b",
    InvocationType="RequestResponse",  # synchronous — A waits for B
    Payload=json.dumps({"order_id": order_id}),
)
result = json.loads(response["Payload"].read())
# If function-b is throttled, cold, or down — function-a fails too.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
# DECOUPLED: Function A publishes an event and returns immediately
import boto3, json

events = boto3.client("events")

events.put_events(
    Entries=[{
        "Source": "orders.service",
        "DetailType": "OrderCreated",
        "Detail": json.dumps({"order_id": order_id}),
        "EventBusName": "app-event-bus",
    }]
)
# function-a succeeds the moment the event is published.
# function-b's availability, cold start, or throttling is now its own problem.
A synchronous chain like this is easy to spot in X-Ray once you know to look for it: you'll see one function's trace segment fully containing another's, including its cold start. That nested segment is the tell it means the caller's latency and reliability are now hostage to the callee's, even though nothing in the code review flagged it as a dependency.
The fix isn't "never call another function directly." It's asking: is this an orchestration (use Step Functions, make the state machine explicit) or is this an event (use EventBridge/SQS and let the caller stop caring what happens next)? Direct invoke is almost always the wrong middle ground.
3. One IAM Role, Attached to Everything
This one is invisible because it doesn't show up in your architecture diagram at all it shows up in your
serverless.yml or SAM template, where it's easy to miss.1
2
3
4
5
6
7
8
9
10
# COUPLED: one role, broad permissions, attached to every function
provider:
iam:
role:
statements:
- Effect: Allow
Action:
- dynamodb:*
- s3:*
Resource: "*" # every function now has this blast radius
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
# DECOUPLED: each function gets exactly what it needs, nothing more
functions:
  ordersFn:
    handler: orders.handler
    iamRoleStatements:
      - Effect: Allow
        Action: [dynamodb:GetItem, dynamodb:PutItem]
        Resource: !GetAtt OrdersTable.Arn

  paymentsFn:
    handler: payments.handler
    iamRoleStatements:
      - Effect: Allow
        Action: [dynamodb:GetItem, dynamodb:UpdateItem]
        Resource: !GetAtt PaymentsTable.Arn
If every function in your service shares one execution role with broad permissions, you've collapsed your blast radius back down to monolith size. A single compromised or misbehaving function a bad deploy, a bug that writes to the wrong table, a dependency-confusion attack in a package you pulled in now has the permissions of your entire application, not just the slice it actually needs.
4. The Database Everyone Touches
Every function eventually needs to read or write state, and it's fastest to point them all at the same RDS instance or the same DynamoDB table. That's fine until two functions start disagreeing implicitly about what a row means. Function A writes a status field expecting one set of downstream consumers; Function B, built eight months later by someone who didn't read Function A's code, writes to the same field with different assumptions.
This is schema coupling, and it's the single most common way "independent" services turn into a monolith with extra network hops. The database becomes the de facto shared memory space, exactly what serverless was supposed to let you avoid by forcing services to talk through explicit contracts (events, APIs) instead of shared state.
5. One Pipeline That Deploys Everything, Together, Every Time
If your CI/CD pipeline builds and deploys all your Lambda functions as one unit in the same pipeline run, same
sam deploy or serverless deploy for the whole stack, no matter which function actually changed, you've made your deployment topology monolithic even if your runtime topology isn't.1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
# GitHub Actions: deploy only the function(s) that actually changed
name: deploy
on:
push:
paths:
- 'functions/**'
jobs:
detect-changes:
runs-on: ubuntu-latest
outputs:
functions: ${{ steps.filter.outputs.changes }}
steps:
- uses: actions/checkout@v4
- uses: dorny/paths-filter@v3
id: filter
with:
filters: |
orders: 'functions/orders/**'
payments: 'functions/payments/**'
notify: 'functions/notify/**'
deploy:
needs: detect-changes
if: needs.detect-changes.outputs.functions != '[]'
strategy:
matrix:
function: ${{ fromJSON(needs.detect-changes.outputs.functions) }}
runs-on: ubuntu-latest
steps:
- run: sam deploy --stack-name ${{ matrix.function }}-fn
A typo in one function's code now blocks a critical fix in an unrelated function until CI passes for the whole stack. This is the easiest problem to fix on this list, and the one most often ignored — because it doesn't fail loudly, it just quietly makes every deploy riskier and slower than it needs to be.
What Actually Decoupled Architecture Looks Like
None of this means "avoid sharing anything." Shared code, shared infrastructure, and orchestrated calls are sometimes the right answer; the mistake is doing them by default, without noticing the coupling you're accepting.

A genuinely decoupled serverless system usually has:
- Layers scoped to a single bounded context, not shared across unrelated features
- Async communication (events/queues) as the default; synchronous invoke as the deliberate exception, justified in a comment or ADR
- Per-function IAM roles scoped to exactly the resources that function touches
- Explicit ownership of each table/data store by one function or service, with everyone else going through its API or events
- Independent deploy pipelines per function or per bounded context, so a change to one doesn't gate a change to another
The Real Test
Ask yourself: if I deleted one Lambda function from my stack right now, would exactly one clearly-defined capability disappear or would three other functions start throwing errors they were never designed to handle?
If it's the second answer, you don't have twelve serverless functions. You have one monolith, running on twelve separate compute contexts, and paying Lambda's per-invocation pricing for the privilege.
None of these couplings show up in a
terraform plan or on an architecture diagram. They only show up when something breaks in a way that shouldn't have been possible, which is exactly why it's worth auditing for them before that happens, not after.Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article