
Supercharging DynamoDB with Bulk Executor: Large-Scale Operations Made Simple
Ever needed to load, transform, or manage large volumes of DynamoDB data without writing boilerplate code? In this episode, we introduce the Bulk Executor — an open-source tool that extends DynamoDB's native capabilities with powerful bulk operations. We'll walk through real commands live, showing you how to simplify large-scale imports, exports, deletes, and transformations with minimal effort, and we'll discuss how agentic AI can assist in this.


The episode introduced DynamoDB Bulk Executor, an open-source tool created by Jason Hunter and Ruskin Dantra that addresses a common gap in DynamoDB's capabilities. While DynamoDB excels at low-latency OLTP operations (gets, puts, queries), customers frequently need to perform large-scale, table-wide operations — extracting items matching arbitrary criteria, bulk deleting old data, copying tables cross-account, filling tables with synthetic data, or comparing two tables for quality assurance. Previously, each of these tasks required customers to build custom AWS Glue scripts, implement their own parallel execution logic, handle rate limiting, error management, and interruption control. Bulk Executor wraps all of this into a simple CLI tool that feels like running a local utility but actually drives hundreds of parallel Glue workers behind the scenes, capable of processing tables with trillions of items.
The tool follows a Unix-utilities philosophy — a core "harness" manages all the operational complexity (spinning up Glue jobs, rate limiting, CloudWatch live tail logging, error handling, interrupt control via Ctrl-C, cost estimation) while pluggable "commands" (called verbs) implement specific business logic. The architecture separates client-side validation (checking parameters, table existence) from server-side execution (the actual Glue jobs), ensuring fast feedback loops. Commands include
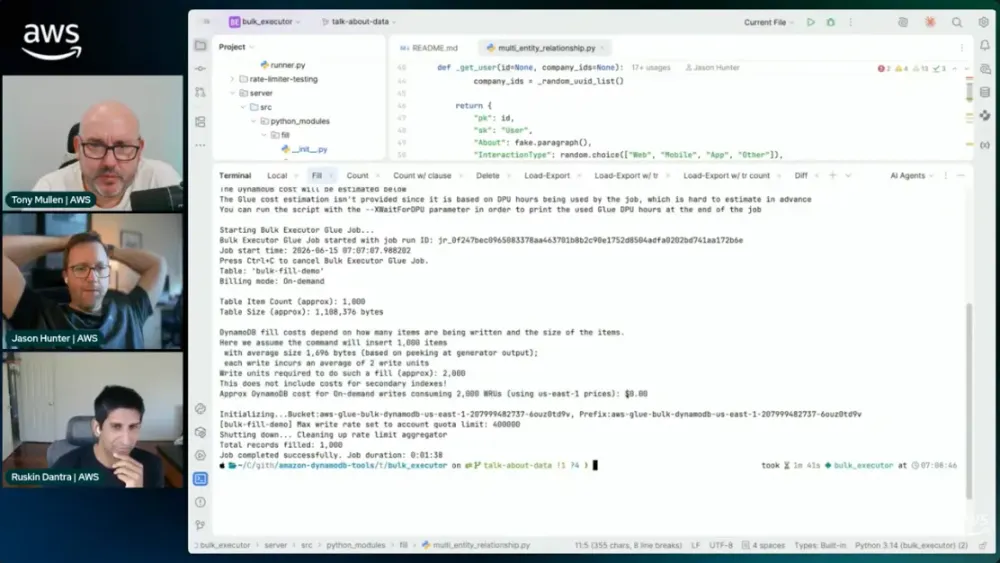
find (scan with arbitrary WHERE clauses), count, delete (with rate limiting for background cleanup), copy (cross-account, cross-region), fill (synthetic data generation using Faker), load-export (with transforms), update (Python hook per item for unlimited flexibility), and diff (comparing two tables for data quality). Security is handled through IAM roles attached to the Glue job, allowing fine-grained read-only or mutating permissions.Demos, Customer Impact & Future Direction: The live demo walked through real commands including filling a table with synthetic data, exporting with transforms (filtering records by criteria during import), counting items, and the tool's cost estimation output. Customers are particularly drawn to the
delete command for cost optimisation — removing old data with a rate limit running in the background to reclaim storage without impacting live traffic. The diff command is also popular for validating replication quality after migrations. The tool is fully open source on GitHub with extensibility for custom commands. Looking ahead, the team teased upcoming work on natural language querying — allowing users to describe transforms and queries in plain English with AI generating the logic dynamically, which will be covered in a future episode.Key Highlights:
- 🚀 Open-source CLI tool for large-scale DynamoDB operations — feels local but runs on hundreds of Glue workers
- ⚡ Supports trillions of items — not a toy; designed for enterprise-scale tables
- 🔧 Built-in commands: find, count, delete, copy, fill, update, diff, load-export
- 🔄 Cross-account and cross-region copy with optional transforms
- 🛡️ Harness handles: rate limiting, error handling, Ctrl-C interrupt control, CloudWatch live tail, cost estimation
- 🐍 Python hooks for custom logic —
updategives you each item to transform however you want - 💰 Popular use case: cost optimisation —
delete where timestamp < Xwith rate limiting to remove old data in the background - 🔍 diff command — compare two tables for data quality post-migration
- 🤖 Coming next: Natural language / AI-driven queries and transforms
- 📦 Extensible architecture — fork it, add your own commands, contribute back
Hosts of the show
Tony Mullen - Senior Database Specialist SA @AWS
Guests
Jason Hunter - Principal Solution Architect, DynamoDB@AWS
Ruskin Dantra - Solutions Architect @AWS
Links from today's episode
| Topic | Link |
|---|---|
| Bulk Blog | https://lets-talk-about-data-aws.com/s418-bulk-blog |
| Rate Limit Blog | https://lets-talk-about-data-aws.com/s418-rate-limit |
| Compare Blog | https://lets-talk-about-data-aws.com/s418-compare |
| Transform Blog | https://lets-talk-about-data-aws.com/s418-transform |
| Main project page | https://lets-talk-about-data-aws.com/s418-github |
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article