
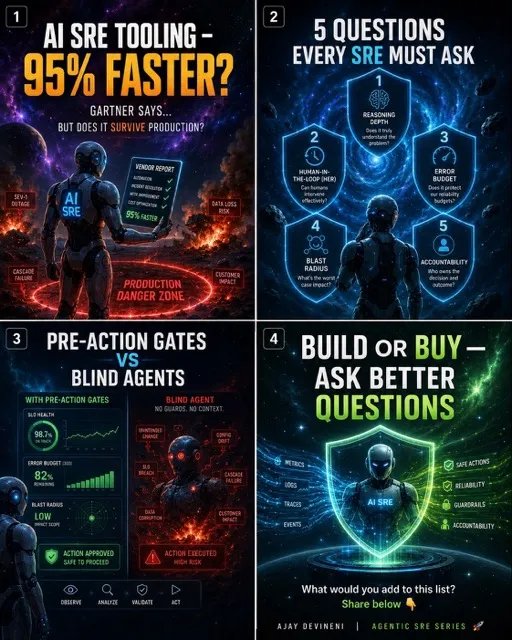
Evaluating AI SRE Tools on AWS — A CloudWatch-Backed Scorecard Using Your Own Telemetry
The best evaluation of an AI SRE tool isn't a vendor demo. It's running the tool in shadow mode against your own CloudWatch telemetry and measuring it with your own SLIs.
The best evaluation of an AI SRE tool isn't a vendor demo. It's running the tool in shadow mode against your own CloudWatch telemetry and measuring it with your own SLIs.
Here's the shadow mode evaluation pattern for AWS:
python
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
import boto3
import json
from datetime import datetime, timezone, timedelta

cw = boto3.client('cloudwatch', region_name='us-east-1')
logs = boto3.client('logs', region_name='us-east-1')

def shadow_mode_evaluation(tool_name: str,
                             agent_id: str,
                             evaluation_window_days: int = 14) -> dict:
    """
    Evaluate an AI SRE tool in shadow mode using your own CloudWatch
    telemetry and agentsre SLIs.

    Shadow mode: tool runs in observation-only mode alongside your
    existing incident response. Compare its recommendations to actual
    human decisions. Measure with your own SLIs.

    Args:
        tool_name: Tool being evaluated
        agent_id: Agent identifier in your ARO registry
        evaluation_window_days: Days of shadow mode data to analyze

    Returns:
        Evaluation summary with SLI measurements
    """
    end = datetime.now(timezone.utc)
    start = end - timedelta(days=evaluation_window_days)
    period = evaluation_window_days * 86400

    def get_metric_avg(metric_name: str, namespace: str) -> float:
        response = cw.get_metric_statistics(
            Namespace=namespace,
            MetricName=metric_name,
            Dimensions=[{'Name': 'AgentId', 'Value': agent_id}],
            StartTime=start, EndTime=end,
            Period=period, Statistics=['Average']
        )
        points = response.get('Datapoints', [])
        return round(points[0]['Average'], 3) if points else 0.0

    # Collect all five evaluation dimensions from your own telemetry
    her = get_metric_avg('HumanEscalationRate', 'AgentSRE/Reliability')
    rtd = get_metric_avg('ReasoningTraceDepth', 'AgentSRE/Reasoning')
    cur = get_metric_avg('ContextUtilizationPct', 'AgentSRE/ContextBudget')
    gate_blocks = get_metric_avg('GateBlocked', 'AgentSRE/PreActionGate')

    return {
        "tool": tool_name,
        "evaluation_period_days": evaluation_window_days,
        "your_telemetry_says": {
            "her_pct": her,
            "her_interpretation": (
                "tool escalates appropriately" if her < 15
                else "tool over-escalating or under-confident"
            ),
            "avg_rtd": rtd,
            "rtd_interpretation": (
                "reasoning stable" if rtd < 2
                else "excessive re-planning — tool struggling"
            ),
            "avg_context_utilization_pct": cur,
            "gate_block_rate": gate_blocks,
        },
        "shadow_mode_recommendation": (
            "Proceed to canary" if her < 15 and rtd < 2
            else "Extend shadow mode — SLIs not at baseline"
        ),
        "evaluated_at": end.isoformat()
    }
CloudWatch dashboard query — shadow mode SLI comparison:
1
2
3
4
5
6
7
fields @timestamp, agent_id, reasoning.rtd, outcome.human_escalated, outcome.latency_ms
| filter trace_type = 'agent_decision_trace'
| stats avg(reasoning.rtd) as avg_rtd,
        sum(outcome.human_escalated) / count() * 100 as her_pct,
        avg(outcome.latency_ms) as avg_latency_ms
  by bin(1d)
| sort @timestamp asc
Run this across your shadow mode window. If HER is above 15% or avg RTD is above 2 after two weeks, the tool is not operating within its reliable envelope in your environment — regardless of the vendor's benchmark numbers.
Your telemetry is the benchmark. Not theirs.
Ajay Devineni | AWS Community Builder | github.com/Ajay150313/agentsre
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article