
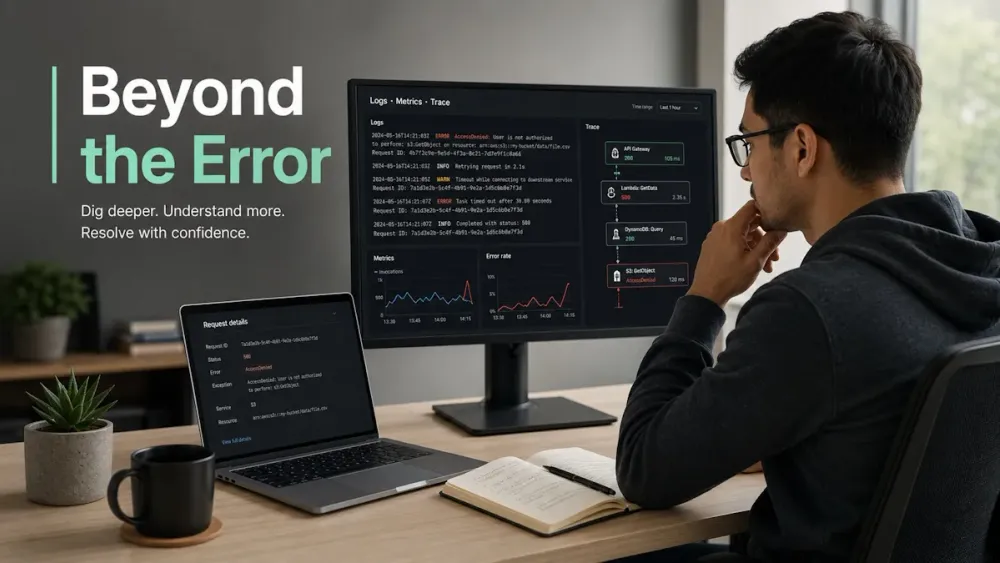
How to Debug AWS Issues When the Error Message Is Not Enough
Learn how to debug AWS issues when error messages are unclear. Follow a practical process using logs, metrics, traces, and smart checks.


AWS errors can be frustrating because they often tell you what failed, but not always why it failed.
You may see a message like “AccessDenied,” “Task timed out,” “Internal server error,” or “Resource not found.” At first, it looks simple. Then you open the console, check the service, scan a few logs, and realize the error message is only one small piece of the story.
That is normal.
Cloud systems have many moving parts. A request may pass through an API, a Lambda function, a database, a queue, a storage bucket, and several permission checks before it reaches the final result. When something breaks, the error message may point to the place where the failure appeared, not the place where it started.
That is why debugging AWS issues needs more than reading the final error.
You need a process.
Start by writing down what actually failed
Before opening ten browser tabs, pause for a minute.
Write down the exact failure in plain language.
For example:
The user cannot upload a file.
The Lambda function times out after 30 seconds.
The ECS task keeps stopping.
The API returns 403 for one user role.
The S3 object exists, but the app cannot read it.
This sounds basic, but it helps. Many debugging sessions go sideways because the team starts chasing symptoms before defining the real problem.
A vague problem creates vague checks.
A clear problem gives you direction.
Ask three simple questions first
What was expected to happen?
What happened instead?
Who or what was affected?
These questions cut through noise. If only one user is affected, the issue may be related to permissions, data, or account state. If every user is affected, it may be a service config, deployment, network rule, or shared resource issue.
Do not skip this part.
It saves time later.
Check the timeline before checking the code
Many AWS issues are tied to time.
Something changed. Then something broke.
That “something” could be a deployment, permission update, security group change, environment variable edit, scaling change, secret rotation, database change, or a new dependency.
Look at the timeline first.
When did the error start?
Was there a release near that time?
Did any config change happen?
Did traffic rise?
Did a scheduled job run?
Did a certificate expire?
Did a secret rotate?
A timeline helps you avoid random guessing. If the issue started five minutes after a deployment, check that release first. If it started during a traffic spike, check limits, queues, and latency. If it started after a permission update, check IAM.
It sounds obvious. In real debugging, people forget it all the time.
Use logs, but do not drown in them
Logs are usually the first place developers go. That makes sense. Logs show what happened inside an app or service.
But logs can also become a swamp.
If your logs are messy, missing request IDs, or filled with unclear messages, you can spend an hour scrolling and still not know what failed.
Amazon CloudWatch Logs can centralize logs from AWS services and applications, then let teams search, filter, query, and monitor them from one place. It also supports CloudWatch Logs Insights for querying log data.
That gives you a good starting point, but you still need a method.
Search with context, not panic
Start with the request ID, user ID, function name, endpoint, order ID, file name, or job ID tied to the issue.
Then widen the search.
Look five minutes before the error and five minutes after it.
Search for nearby warnings, retries, failed permission checks, timeout messages, missing config values, and dependency errors.
Do not only search for the final error text. The root cause may show up earlier.
A timeout in one Lambda function may be caused by a slow database call. A 500 error may be caused by a missing environment variable. A failed upload may be caused by a permission issue on the bucket.
The last error is not always the first problem.
Look at metrics when logs feel noisy
Logs tell stories. Metrics show patterns.
If the error message is not enough and logs are messy, metrics can give you a wider view.
Check the basics:
Request count
Error count
Latency
Throttles
CPU usage
Memory usage
Queue depth
Database connections
Cold starts
Timeouts
Retry count
A single failed request might not tell you much. A rising error rate tells you more. A latency spike before errors begin tells you even more.
AWS monitoring tools use data such as metrics, logs, and traces to track health, support incident response, and help teams find root causes across cloud workloads.
Metrics help answer one key question:
Is this one broken request, or is the system under stress?
That answer changes your next move.
Follow the request path
In modern AWS apps, one request may touch many services. That makes debugging harder.
The API may call Lambda. Lambda may read from DynamoDB. Then it may publish to SNS. Then another Lambda may process that event. Then data may land in S3. One weak link can make the user see one simple error.
This is why tracing matters.
AWS X-Ray collects data about application requests and can show details about calls made to downstream AWS resources, microservices, databases, and web APIs. It can also help identify latency spikes and bottlenecks through trace data.
Think of tracing like following footprints through the system.
Where did the request enter?
Which service handled it?
Which call was slow?
Which call failed?
Did the request reach the database?
Did it fail before or after a queue?
If you only look at the service that returned the error, you may miss the real cause.
Use correlation IDs when possible
A correlation ID is a shared ID passed across services for the same request.
It helps you connect logs from API Gateway, Lambda, containers, queues, and databases.
Without it, you may have to guess which log event belongs to which request. That gets messy fast.
A simple habit can make future debugging easier:
Generate a request ID at the edge.
Pass it through each service.
Log it in every key step.
Return it in error responses when safe.
This one habit can turn a confusing issue into a traceable path.
Do not assume IAM is fine
AWS permission issues can be sneaky.
A service may work in one environment but fail in another. A role may have permission to read one bucket but not another. A user may have console access but the app role may not. A resource policy may block access even when the IAM role looks correct.
When you see errors like 403, AccessDenied, unauthorized, or missing permissions, check IAM early.
Look at:
The role used by the running service
The policy attached to that role
The resource policy
The region
The account ID
The exact action being denied
The condition keys
The service principal
Small details matter here.
For example, s3:GetObject and s3:ListBucket are different permissions. Reading a secret and describing a secret may need different actions. A KMS key policy may block access even when the main service role looks fine.
Do not just ask, “Does it have access?”
Ask, “Does this exact identity have this exact permission on this exact resource under these exact conditions?”
That is less fun to say, but it works.
Check config before blaming AWS
A lot of cloud bugs are not AWS bugs. They are config bugs.
Wrong region.
Wrong environment variable.
Wrong subnet.
Wrong security group.
Wrong secret name.
Wrong endpoint.
Wrong runtime setting.
Wrong memory size.
Wrong timeout.
Wrong stage.
Wrong branch deployed.
It happens to everyone.
Before digging too deep, compare the working environment with the broken one. Dev may work while staging fails. Staging may work while production fails. That difference is a clue.
Look for config drift.
Did one environment get a new variable while another did not?
Are both using the same VPC settings?
Are both reading the same secret path?
Are both pointing to the same database type?
Are both using the same runtime version?
The error message may say “connection failed.” The real cause may be a security group rule added last week.
Read service limits and quotas when behavior feels random
Some AWS issues show up only under load.
Your app works during testing, then fails when traffic rises. A queue gets backed up. A function gets throttled. A database reaches connection limits. A service returns rate errors. Retries make the problem worse.
This can feel random, but it usually has a pattern.
Check service quotas and limits when:
Errors rise during traffic spikes
Retries increase sharply
Latency grows before failures
Some requests pass and some fail
Background jobs fall behind
Functions are throttled
Queues keep growing
Also check whether your retry logic is helping or hurting. Retrying too fast can add pressure to a system that is already struggling.
A calmer retry plan with backoff can reduce load while the system recovers.
Separate app bugs from cloud setup issues
When an AWS issue is unclear, teams may argue without proof.
“It is the code.”
“No, it is the infrastructure.”
“It worked yesterday.”
“Maybe AWS is down.”
That back-and-forth wastes time.
Separate the problem into two lanes:
Application behavior
Cloud setup
Application behavior includes code logic, input validation, dependency calls, error handling, and database queries.
Cloud setup includes IAM, networking, scaling rules, service config, secrets, DNS, load balancers, and deployment settings.
Test both lanes.
Can the app logic run locally with the same input?
Can the service reach its dependency from inside AWS?
Can the role access the resource through CLI?
Can the database be reached from the same subnet?
Can another service use the same permission?
This makes the debugging calmer. You stop guessing and start narrowing.
Reproduce the issue in the smallest way
A full production issue may be too big to understand at once.
Shrink it.
Try to reproduce the same failure with the smallest possible test.
Call the API with one known bad request.
Run the Lambda with one test event.
Use AWS CLI to read the same S3 object.
Send one message to the queue.
Query one database record.
Assume the same IAM role and repeat the failed action.
Small tests reduce noise.
They also help you prove where the issue lives. If the CLI action fails with the same role, the issue is likely permission or resource policy. If the CLI action works but the app fails, check code, config, runtime, or network path.
This is slow for five minutes, then fast for the next hour.
When the console is not enough, use the CLI
The AWS console is useful, but it can hide details.
The CLI can show exact responses, raw errors, and config values. It also helps you repeat the same action without clicking through pages.
For example, you can check whether a role can access a resource, inspect Lambda config, describe ECS tasks, view logs, test S3 access, or query service state.
You do not need to become a CLI wizard.
Just learn enough to ask direct questions.
What role is this function using?
What environment variables are set?
Which task stopped and why?
Which security group is attached?
Does this object exist?
Can this identity read it?
The CLI gives you cleaner evidence.
And debugging needs evidence.
Watch out for region and account mix-ups
This one sounds silly until it costs you two hours.
AWS accounts and regions can create confusion.
You may be checking logs in us-east-1 while the app runs in us-west-2. You may be looking at staging while the error happened in production. You may be logged into the wrong AWS account. You may be checking the old Lambda function after a new one was deployed.
Before going deep, confirm:
Account
Region
Environment
Service name
Resource name
Deployment version
Runtime role
These checks are boring.
They also catch real mistakes.
A lot of debugging is not genius work. It is patient checking.
Build better error messages for next time
Sometimes AWS gives you a vague error. Sometimes your own app does.
You can fix that.
Good error handling does not mean showing users every technical detail. That can be unsafe and confusing. But your internal logs should give enough context for the team to debug.
A useful error log may include:
Request ID
User or tenant ID when safe
Service name
Action attempted
Resource name
Status code
Upstream service called
Retry count
Time taken
Clean error reason
Avoid logging private data. Do not dump secrets, tokens, full payment data, or sensitive user content.
The goal is to give developers clues without creating security risk.
Bad log:
Upload failed.
Better log:
File upload failed for request_id abc123 at S3 PutObject step. Bucket: app-prod-docs. Status: AccessDenied. Role: upload-service-prod.
That kind of message can cut debugging time sharply.
Know when to ask for help
Some AWS issues need more than one person.
If the problem crosses code, networking, IAM, deployment, and data flow, bring in the right people. A backend developer may know the app logic. A DevOps engineer may spot a subnet or role issue. A security engineer may catch a policy condition. A database engineer may see slow queries or connection pressure.
Getting help is not failure.
It is often the fastest path.
For teams that handle cloud apps at scale, working with people who understand cloud and DevOps consulting services can also help when recurring issues keep coming back through weak deployment habits, unclear monitoring, or fragile infrastructure choices.
The key word is recurring.
If the same class of issue appears again and again, you do not just have a bug. You have a system problem.
Create a debugging checklist your team will actually use
A good checklist should be short.
Nobody wants a 40-step document during an incident.
Here is a practical AWS debugging checklist:
Define the exact failure.
Check who is affected.
Find when it started.
Compare that time with recent changes.
Check logs with request IDs.
Review metrics for spikes or drops.
Trace the request path.
Verify IAM permissions.
Check region, account, and environment.
Compare working and broken configs.
Reproduce the issue with a small test.
Use CLI when console details are unclear.
Write down the root cause.
Add one prevention step.
That last step matters.
Every resolved issue should make the next issue easier.
Turn each bug into a better system
After the issue is fixed, do a short review.
Not a blame session.
A learning session.
Ask:
What made this hard to debug?
Which signal was missing?
Did logs show the right details?
Did metrics reveal the pattern?
Was there a trace across services?
Did the error message help or confuse?
Could a test have caught this?
Could a deployment check have caught this?
Could an alarm have warned us sooner?
This is where teams get better.
The real value of debugging is not just fixing today’s issue. It is reducing tomorrow’s confusion.
Maybe you add a missing alarm. Maybe you improve logs. Maybe you pass correlation IDs. Maybe you tighten IAM naming. Maybe you document a service dependency. Maybe you break a large Lambda into clearer parts.
Small changes stack up.
Common AWS debugging mistakes to avoid
Chasing the first error too hard
The first visible error may be a symptom. Always look a little earlier in the timeline.
Ignoring recent changes
If something broke after a release, check the release. It is not rude. It is practical.
Looking only at one service
Cloud failures often cross service lines. Follow the request path.
Forgetting IAM details
Permissions fail in specific ways. Check the exact identity, action, resource, and condition.
Skipping metrics
Logs show events. Metrics show patterns. You need both.
Not saving what you learned
If the same issue happens again and the team starts from zero, the process is broken.
A sample debugging flow
Let’s say users report that file uploads are failing.
The app shows a simple error: “Upload failed.”
Not helpful.
Here is how you might debug it:
First, define the failure. Users can select a file, but the upload fails after clicking submit.
Next, check scope. Is it all users or one account? Suppose it is only production users.
Then check time. The issue started around 10:15 a.m.
Look for changes. A deployment happened at 10:05 a.m. A new S3 bucket policy was also applied.
Check logs. The API logs show a failed upload step. The Lambda logs show AccessDenied during PutObject.
Check IAM. The Lambda role has s3:PutObject, but the bucket policy allows a different role name.
Check region and account. The app is using the production bucket in the correct region.
Reproduce with CLI using the same role. The PutObject request fails.
Now the cause is clear. The bucket policy blocks the correct role.
Fix the policy. Test the upload. Watch metrics and logs. Add a better log message and a deployment check for bucket policy changes.
That is a clean debugging path.
No guessing needed.
Build systems that are easier to debug
The best debugging starts before the bug.
You can make AWS apps easier to support by designing for visibility from the start.
Use clear service names.
Keep environment names obvious.
Pass request IDs through services.
Log key actions with safe context.
Track important metrics.
Use tracing for multi-service flows.
Keep IAM roles specific and readable.
Document service dependencies.
Keep deployment changes small.
Add alarms that point to real user impact.
These habits do not make bugs disappear. They make bugs less confusing.
That matters.
A clear system is faster to fix.
The real skill is narrowing the problem
When the error message is not enough, do not panic.
Narrow the problem.
Start with what failed. Check when it started. Review recent changes. Look at logs, metrics, and traces. Verify permissions. Compare configs. Reproduce the issue in a small way. Then fix the root cause, not just the symptom.
AWS debugging is not about knowing every service by heart.
It is about asking better questions.
Where did the request go?
Where did it slow down?
What changed?
Which identity made the call?
Which resource blocked it?
What does the data say?
Those questions will take you further than any vague error message.
The next time AWS gives you a short error and a long headache, treat the message as the starting point, not the answer. Your real answer is hiding in the timeline, the request path, the permissions, and the signals your system is already giving you.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article