
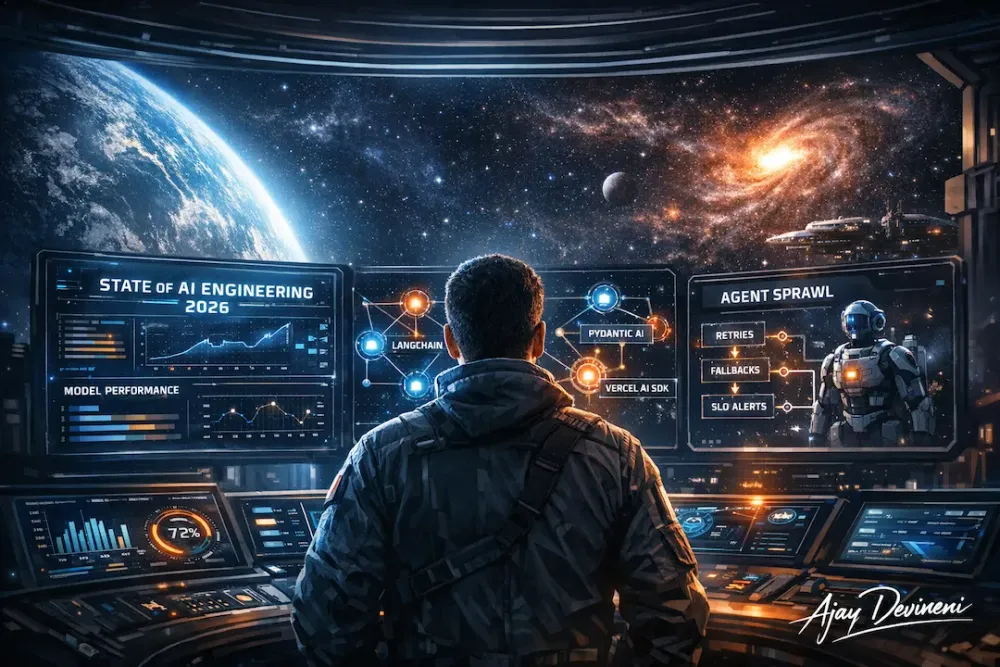
Governing Agent Sprawl on AWS: Fleet Inventory, Framework Canary, and Deprecation Alerting for Multi-Model Bedrock Deployments
Datadog's State of AI Engineering 2026 reports that more than 70% of organizations now run three or more AI models in production, with framework adoption doubling year over year. For teams running Amazon Bedrock Agents, this means one thing: you are operating a model fleet, not a single agent. And almost certainly, you do not have SLO owners assigned to every model in that fleet
Senior DevOps & SRE | IEEE Senior Member | AI Observability & Cloud Resilience
Governing Agent Sprawl on AWS: Fleet Inventory, Framework Canary, and Deprecation Alerting for Multi-Model Bedrock Deployments
Datadog's State of AI Engineering 2026 reports that more than 70% of organizations now run three or more AI models in production, with framework adoption doubling year over year. For teams running Amazon Bedrock Agents, this means one thing: you are operating a model fleet, not a single agent. And almost certainly, you do not have SLO owners assigned to every model in that fleet.
This article documents the AWS infrastructure for governing what I call Agent Sprawl — the condition where AI agent complexity grows faster than your ability to measure and govern its reliability. No proprietary data is referenced; all patterns are drawn from publicly documented AWS architecture guidance and research across multi-agent production deployments.
Why Standard Bedrock Instrumentation Creates Agent Sprawl Blind Spots
Amazon Bedrock Agents support multiple orchestration strategies and built-in retry and fallback logic. When you instrument at the Lambda action group level — the most common approach — you miss the calls Bedrock's orchestration layer adds:
- Retries on tool call failures
- Fallback invocations when the primary action group returns an error
- Parallel tool calls added by the orchestration engine
- Context management steps between invocations
Your CloudWatch
InvocationCount on Lambda action groups undercounts actual tool invocations. Your TIE baseline is measuring a floor, not the real call graph.The fix: instrument at the Bedrock model invocation logging layer.
Enable Bedrock model invocation logging to CloudWatch:
Bash
aws bedrock put-model-invocation-logging-configuration \--logging-config '{"cloudWatchConfig": {"logGroupName": "/aws/bedrock/model-invocations","roleArn": "arn:aws:iam::ACCOUNT_ID:role/BedrockLoggingRole"},"textDataDeliveryEnabled": true}'
A Lambda subscribed to this log group extracts every tool invocation from the orchestration trace — including framework-added calls — and publishes a corrected TIE metric with a
ModelId dimension:Python
def process_bedrock_trace(trace):if trace.get('type') != 'ORCHESTRATION':returntask_class = trace.get('metadata', {}).get('task_class', 'unknown')# tool_calls here includes ALL calls — including framework-added retriestool_calls = len(trace.get('toolUses', []))cloudwatch.put_metric_data(Namespace='AgentReliability',MetricData=[{'MetricName': 'ToolInvocationEfficiency','Dimensions': [{'Name': 'AgentId', 'Value': trace.get('agentId')},{'Name': 'TaskClass', 'Value': task_class},{'Name': 'ModelId', 'Value': trace.get('modelId', 'unknown')},],'Value': float(tool_calls),'Unit': 'Count',}])
The
ModelId dimension is critical — it enables per-model TIE tracking, the foundation of multi-model SLO governance.
The Agent Fleet Inventory on AWS — DynamoDB
The agentsre library's fleet inventory maps directly to a DynamoDB table:
Table:
agent-fleet-inventory Python
# Python using agentsre — the library handles the data modelfrom agentsre.sprawl import AgentFleetInventory, FleetComponent, ComponentTypeinventory = AgentFleetInventory()inventory.register(FleetComponent(component_id="anthropic.claude-sonnet-4-6",component_type=ComponentType.MODEL,agent_id="payment-processor",task_classes=["payment-routing"],slo_owner="owner@team.com",baseline_established_at="2026-04-01",deprecation_date="2027-06-01",current_tie_baseline=2.4,current_dqr_baseline=91.2,last_slo_review="2026-04-01",))# Governance health score for every componentreport = inventory.quarterly_review_report()
For production persistence, serialize each FleetComponent to DynamoDB:
Python
import boto3from decimal import Decimalimport jsondynamodb = boto3.resource('dynamodb')table = dynamodb.Table('agent-fleet-inventory')def persist_component(component: FleetComponent):item = component.to_dict()# DynamoDB requires Decimal for floatsitem['current_tie_baseline'] = Decimal(str(item.get('current_tie_baseline', 0)))item['current_dqr_baseline'] = Decimal(str(item.get('current_dqr_baseline', 0)))item['pk'] = component.agent_iditem['sk'] = component.component_idtable.put_item(Item=item)
Deprecation Alerting — EventBridge + SNS
A daily EventBridge rule triggers a Lambda that checks every model's deprecation date and fires tiered SNS alerts at 60, 30, and 7 days:
Python
def lambda_handler(event, context):# Load inventory from DynamoDBresponse = table.scan()for item in response['Items']:component = FleetComponent(**item)# agentsre handles the alert threshold logicalerts = AgentFleetInventory()alerts.register(component)pending = alerts.pending_deprecation_alerts()for alert in pending:sns.publish(TopicArn=DEPRECATION_ALERT_TOPIC,Subject=f"[{alert.days_remaining}d] Model deprecation: {alert.component_id}",Message=json.dumps({'component_id': alert.component_id,'days_remaining': alert.days_remaining,'slo_owner': alert.slo_owner or 'UNASSIGNED — assign immediately','task_classes': alert.task_classes,'action_required': 'Begin migration or extension request now',}))
An unassigned SLO owner on a deprecating model is a P0 — the SNS message surfaces it explicitly.
Framework Upgrade Canary — CodePipeline Integration
Integrate the
FrameworkVersionGovernance canary into your Bedrock agent deployment pipeline:Python
from agentsre.sprawl import FrameworkVersionGovernance, UpgradeDecisiondef deployment_gate(agent_id, task_class, old_version, new_version):"""CodePipeline approval action — returns True to promote, False to block."""gov = FrameworkVersionGovernance(tie_drift_threshold=1.15,dqr_drift_threshold=0.85,min_shadow_samples=50,)# Snapshot is captured by a pre-deploy Lambda before the new version ships# Shadow results are recorded by the traffic-split Lambda during canary periodresult = gov.evaluate_upgrade(agent_id=agent_id,task_class=task_class,production_version=old_version,shadow_version=new_version,)if result.decision == UpgradeDecision.BLOCK:# Fail the CodePipeline approval actioncodepipeline.put_job_failure_result(jobId=JOB_ID,failureDetails={'type': 'JobFailed','message': f"Framework upgrade blocked: {result.block_reason}",})return Falsereturn True
This makes framework upgrades subject to the same gate as any other production deployment — they cannot bypass TIE/DQR validation.
The Quarterly Review — SSM Automation
Automate the quarterly multi-model SLO review with an SSM Automation Document:
- Load fleet inventory from DynamoDB
- Run
quarterly_review_report()via a Lambda
- Generate governance health PDF via Lambda → S3
- Send PDF to all SLO owners via SNS 14 days before quarter end
- Components scoring below 70 trigger a 30-day remediation ticket in your issue tracker
The review output surfaces four action item categories:
- P0: Orphaned components (no SLO owner)
- P1: Imminent deprecations (< 30 days)
- P2: Stale baselines (> 90 days)
- P3: Overdue SLO reviews (> 90 days)
Connecting the Full Stack
This agent sprawl governance layer builds on:
- Single-agent SLI instrumentation (DQR, TIE, HER, AQDD)
- A2A multi-agent semantic boundary validation and circuit breaker
- Agent Sprawl governance (this article): fleet inventory + framework canary + deprecation alerting
Together: the complete reliability engineering stack for production AI on AWS — from the first agent to the governed multi-model fleet.
Open-source library: https://github.com/Ajay150313/agentsre
LinkedIn discussion: https://www.linkedin.com/posts/ajay-devineni\_agenticai-sre-reliability-ugcPost-7455786901673902080-BCRM?utm\_source=share\&utm\_medium=member\_desktop\&rcm=ACoAACIp55QBRGVmAcEbf0D-1PaR5vEbm2yMcJU
DEV Community article (conceptual): https://dev.to/ajaydevineni/agent-sprawl-is-your-next-production-incident-an-sre-response-to-datadogs-state-of-ai-engineering-3k83
What's the hardest agent sprawl problem in your AWS environment?
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article