
SLO Design for Agentic AI Systems on AWS: Beyond Uptime Metrics
Service Level Objectives work well for stateless APIs and microservices. They break — quietly and dangerously — when applied without modification to agentic AI systems. This post documents the reliability signal framework I've developed over the past quarter running agentic AI pipelines in a regulated cloud-native environment on AWS. It is intended for SRE teams and platform engineers deploying AI agents that interact with production infrastructure.
Senior DevOps & SRE | IEEE Senior Member | AI Observability & Cloud Resilience
SLO Design for Agentic AI Systems on AWS: Beyond Uptime Metrics
Category: AI/ML, Reliability Engineering, Cloud Architecture
Services referenced: Amazon CloudWatch, AWS X-Ray, Amazon Bedrock, Amazon EventBridge, AWS Step Functions
Overview
Service Level Objectives work well for stateless APIs and microservices. They break — quietly and dangerously — when applied without modification to agentic AI systems.
This post documents the reliability signal framework I've developed over the past quarter running agentic AI pipelines in a regulated cloud-native environment on AWS. It is intended for SRE teams and platform engineers deploying AI agents that interact with production infrastructure.
Why traditional SLO metrics are insufficient for agents
Standard SLO signals — availability, latency, error rate — measure whether a system responds. They do not measure whether the system's decisions are correct, safe, or degrading.
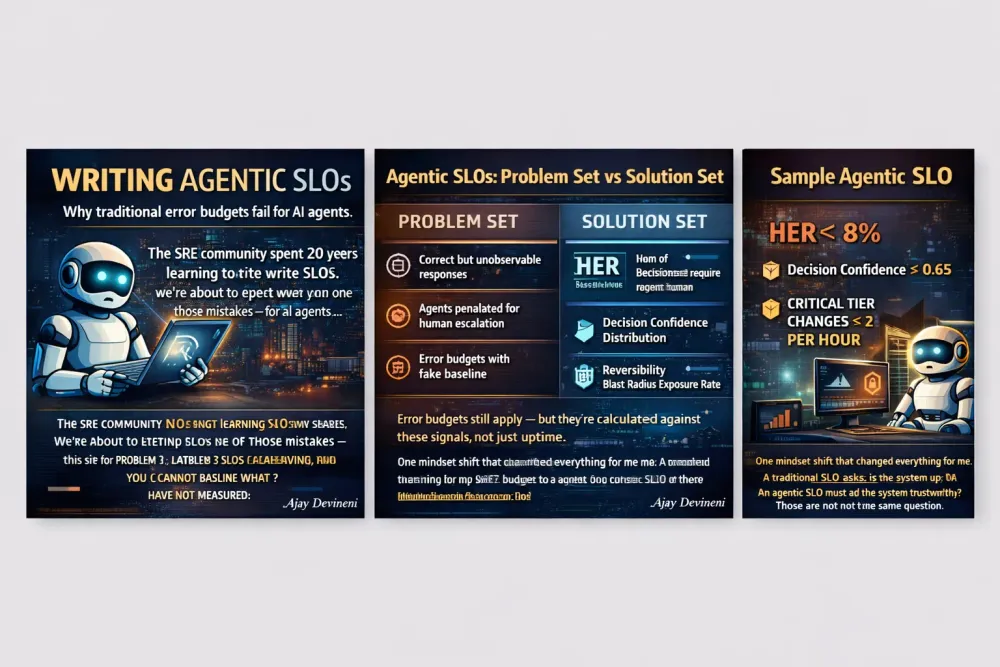
Agentic systems introduce three failure modes that traditional SLOs cannot observe:
- Silent correctness failure An agent can produce a well-formed, schema-valid response that is semantically wrong. No 5xx is thrown. CloudWatch alarms stay quiet. The downstream impact accumulates.
- Safety-penalizing latency targets An agent that escalates an ambiguous decision to a human, pauses for context verification, or refuses a potentially poisoned tool output is behaving correctly. A p99 latency SLO penalizes it for doing so.
- Premature SLO commitment Without a behavioral baseline built on real production traffic, any committed SLO number is a guess. Guesses burn error budgets in the first real incident.
Three reliability signals for agentic SLOs on AWS
Signal 1: Human Escalation Rate (HER)
Emit a custom CloudWatch metric on every agent decision:
Python
cloudwatch.put_metric_data(Namespace='AgentReliability',MetricData=[{'MetricName': 'HumanEscalationRate','Value': 1 if escalated else 0,'Unit': 'Count','Dimensions': [{'Name': 'AgentId', 'Value': agent_id},{'Name': 'DecisionClass', 'Value': decision_class}]}])
Create a CloudWatch alarm on the rolling 24-hour HER ratio. Wire it to an SNS topic connected to your on-call rotation. This single metric is your earliest observable signal of model drift, context degradation, or prompt decay.
Target: HER ≤ 8% over any 24-hour rolling window
Signal 2: Decision confidence distribution (p10)
Emit confidence scores as a CloudWatch metric and use the p10 statistic — not the average. An average masks the collapse of the low end of the distribution, which is where dangerous decisions live.
Python
cloudwatch.put_metric_data(Namespace='AgentReliability',MetricData=[{'MetricName': 'DecisionConfidence','Value': confidence_score,'Unit': 'None','Dimensions': [{'Name': 'AgentId', 'Value': agent_id}]}])
Set a CloudWatch alarm on the p10 statistic with a 1-hour evaluation period. A collapse in p10 is a leading indicator, not a lagging one.
Target: Decision confidence p10 ≥ 0.65
Signal 3: Blast radius exposure rate (BRER)
Every AI-proposed infrastructure change should be classified by blast radius tier before execution. Emit tier as a metric and alarm on the rate of CRITICAL-tier changes.
Python
TIER_VALUES = {'LOW': 1, 'MEDIUM': 2, 'HIGH': 3, 'CRITICAL': 4}cloudwatch.put_metric_data(Namespace='AgentReliability',MetricData=[{'MetricName': 'BlastRadiusTier','Value': TIER_VALUES[change_tier],'Unit': 'None','Dimensions': [{'Name': 'AgentId', 'Value': agent_id}]}])
Use an EventBridge rule to automatically route CRITICAL-tier change events to a Step Functions approval workflow before execution. This creates a hard gate independent of the monitoring layer.
Target: CRITICAL tier changes ≤ 2/hour without approval gate clearance
Baseline requirement
No agentic SLO should be ratified without a 30-day behavioral baseline under real production traffic. The baseline period must include at least one tool failure simulation and one controlled prompt drift scenario. Synthetic load is not a substitute.
Use AWS X-Ray to trace the full agent decision chain during the baseline period. The baseline trace data becomes the reference distribution for ongoing anomaly detection.
Architecture pattern
Plain text
Agent Decision│├─► CloudWatch Custom Metrics (HER, Confidence, BRER)│ ││ └─► CloudWatch Alarms ──► SNS ──► PagerDuty / On-call│├─► X-Ray Trace (full decision lineage)│└─► EventBridge Rule│├─► [LOW/MEDIUM] → Execute└─► [CRITICAL] → Step Functions approval workflow → Execute or Quarantine
Key takeaway
A traditional SLO asks: is the system available?
An agentic SLO must ask: is the system trustworthy?
Uptime is necessary but not sufficient. The reliability signals that matter for agents — correctness, safety behavior, blast radius velocity — require purpose-built instrumentation on top of your existing observability stack.
The good news: if you're already running CloudWatch, X-Ray, EventBridge, and Step Functions, the infrastructure is already there. What's missing is the signal definition and the 30-day discipline to baseline before you commit.
Related reading in this series
- Decision-lineage observability for MCP-based agentic pipelines
- Blast radius classification framework for AI-generated infrastructure changes
- Human Escalation Rate (HER) as a production reliability signal
Built and validated in a regulated cloud-native environment. All metric targets reflect 30-day baselines from production traffic, not synthetic benchmarks.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article