
Memory Consolidation Daemon for AI Agents with Bedrock
Open-source daemon that uses Amazon Bedrock to extract and consolidate AI agent memory from session files. Covers architecture, prompt caching, and guardrails.
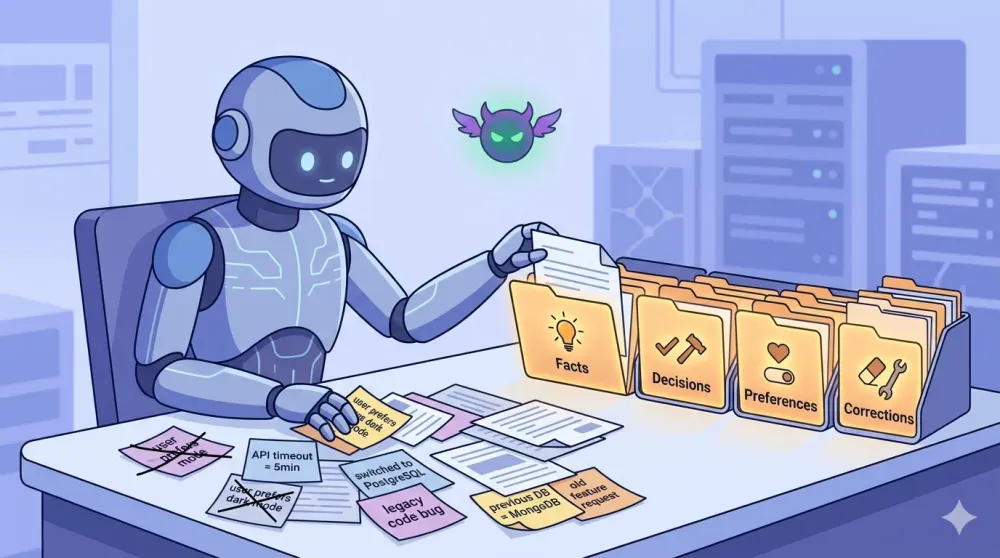
AI agents that operate over multiple sessions face a persistent challenge: memory management.
Session transcripts accumulate, facts contradict each other, and the agent's context window fills with redundant or stale information. Most agent frameworks provide memory storage, but few provide memory curation — the ongoing process of organizing, deduplicating, and pruning what the agent remembers.
agent-memory-daemon is an open-source TypeScript daemon that runs alongside any agent framework and uses Amazon Bedrock to automatically extract knowledge from session files and consolidate it into structured, size-budgeted memory.
This article covers the architecture, the Bedrock integration patterns, and how to deploy it alongside agent workloads.
Architecture overview
The daemon operates in two complementary modes within a single process:
Plain text
┌─────────────────────────────────────────────────┐│ Daemon Process ││ ││ ┌──────────────┐ ┌─────────────────────┐ ││ │ Extraction │ │ Consolidation │ ││ │ │ │ │ ││ │ Session files │ │ Memory directory │ ││ │ → LLM pass │ │ → orient → gather │ ││ │ → New memory │ │ → consolidate │ ││ │ files │ │ → prune → index │ ││ └──────┬───────┘ └──────────┬──────────┘ ││ │ Shared lock │ ││ └──────────┬───────────────┘ ││ │ ││ ┌───────▼────────┐ ││ │ PID-based │ ││ │ mutual │ ││ │ exclusion │ ││ └────────────────┘ │└─────────────────────────────────────────────────┘│ │┌────▼─────┐ ┌─────▼──────┐│ Session │ │ Memory ││ directory│ │ directory ││ (input) │ │ (output) │└──────────┘ └────────────┘
Extraction watches for new session content using a per-session cursor (file offset + mtime tracking), builds a prompt containing the current memory manifest and new session content, and calls Bedrock to identify facts, decisions, preferences, and error corrections worth persisting.
Consolidation runs on a three-gate trigger system (time elapsed + session count + lock acquisition), executing a four-phase LLM pass that orients on the current state, gathers related content, merges and deduplicates, then prunes stale entries. The
MEMORY.md index is kept within a configurable line and byte budget.Both modes share a PID-based lock file for mutual exclusion. Consolidation takes priority when both triggers fire simultaneously.
Amazon Bedrock integration
Converse API
The daemon uses the Bedrock Converse API via
@aws-sdk/client-bedrock-runtime , which provides a model-agnostic interface. This avoids model-specific payload formats and allows switching between Anthropic Claude, Amazon Nova, or other models by changing a single configuration value.TypeScript
const command = new ConverseCommand({modelId: this.modelId,messages,system: systemBlocks,inferenceConfig: {maxTokens: 8192,temperature: 0.2,},});
Prompt caching with cachePoint
Both consolidation and extraction split their prompts into a stable system prefix (instructions, classification rules, response format) and a variable user message (memory manifest, session content). The system prefix is placed before a
cachePoint block:TypeScript
const systemBlocks: SystemContentBlock[] = [];if (options?.systemPrompt) {systemBlocks.push({ text: options.systemPrompt });// Anthropic prompt caching: cache everything up to this pointsystemBlocks.push({ cachePoint: { type: 'default' } });}systemBlocks.push({text: 'You are a memory consolidation assistant...',});
For Anthropic models on Bedrock, this means the ~2K character instruction prefix is cached across calls. In consolidation's multi-chunk mode (where a large memory directory is processed in multiple LLM calls), chunks 2+ get a cache hit on the shared instruction prefix. Non-Anthropic models silently ignore the
cachePoint block.Credential handling
The daemon uses the SDK's default credential provider chain, supporting environment variables,
~/.aws/credentials , SSO, ECS container credentials, and EC2 instance metadata. An optional profile configuration allows specifying a named AWS profile:toml
[llm_backend]name = "bedrock"region = "us-east-1"profile = "my-profile"model = "us.anthropic.claude-sonnet-4-20250514-v1:0"
Credentials are verified at startup by resolving them before the first API call, providing a clear error message if resolution fails.
Timeout configuration
Large memory directories can produce prompts exceeding 40K characters. The default SDK timeout is insufficient for these workloads. The daemon configures
NodeHttpHandler with a 10-second connection timeout and a 5-minute request timeout:TypeScript
requestHandler: new NodeHttpHandler({connectionTimeout: 10_000,requestTimeout: 300_000,}),
Transient failures (network errors, 429 rate limits, 5xx server errors) are retried with exponential backoff up to 3 attempts. Client errors (4xx except 429) fail immediately.
Memory file structure
Each memory file is a markdown document with YAML frontmatter:
Markdown
---name: "Bedrock request timeout"description: "SDK default timeout insufficient for large prompts"type: reference---BedrockRuntimeClient requires NodeHttpHandler with requestTimeoutof 300000ms (5 min) for prompts over 30K characters. The defaulttimeout causes ECONNABORTED errors on large consolidation passes.
Memory types (
user , feedback , project , reference ) are assigned by the LLM during extraction and used for manifest formatting. The memory manifest includes age information ("today", "yesterday", "N days ago") so the LLM can prioritize updating stale entries over creating duplicates.Guardrails
Without limits, extraction can create files exponentially — each pass sees new files from the previous pass, producing an ever-growing manifest that prompts the LLM to create even more files. The daemon enforces several caps:
Guardrail | Default | Purpose |
|---|---|---|
max_memory_files | 50 | Hard cap on total files in the memory directory |
max_files_per_batch | 10 | Maximum creates per extraction pass |
max_prompt_chars | 40,000 | Total prompt budget with progressive truncation |
Per-session cursor | — | Tracks file offset + mtime to avoid reprocessing |
Update and delete operations are not subject to creation caps, ensuring consolidation can always reorganize existing content.
Prompt budget enforcement uses progressive truncation: session blocks are removed from the end first, then the manifest is truncated at line boundaries. A final safety-net truncation ensures the prompt never exceeds the budget.
Deployment patterns
Alongside Strands agents
Point
session_directory at the directory where your Strands agent writes session artifacts. At agent startup, read MEMORY.md and relevant topic files into the system prompt:toml
memory_directory = "/app/memory"session_directory = "/app/sessions"extraction_enabled = true[llm_backend]name = "bedrock"region = "us-east-1"model = "us.anthropic.claude-sonnet-4-20250514-v1:0"
On ECS or EC2
The daemon runs as a long-lived Node.js process. It handles SIGTERM and SIGINT for graceful shutdown, rolling back any in-progress lock. The credential chain automatically picks up ECS task role credentials or EC2 instance profile credentials.
Bash
npx agent-memory-daemon start /app/memconsolidate.toml
Dry-run mode
Set
dry_run = true to preview what the daemon would do without writing any files. All operations are logged with their content lengths and paths, allowing validation before enabling writes.Observability
The daemon emits structured JSON logs to stderr:
JSON
{"timestamp": "2026-04-07T14:23:01.234Z","level": "info","event": "extraction:complete","data": {"created": 3,"updated": 1,"durationMs": 4521,"promptLength": 39102,"operationsRequested": 5,"operationsApplied": 4,"operationsSkipped": 1}}
Key events include
daemon:extraction-start , daemon:extraction-complete , daemon:consolidation-complete , extraction:max-memory-files-reached , and extraction:max-files-per-batch-reached . These can be piped to CloudWatch Logs, parsed with jq , or ingested by any log aggregation system.Testing approach
The project uses property-based testing with fast-check extensively. Rather than example-based tests that check specific inputs, property tests generate random inputs and verify invariants:
- Guardrail properties: for all generated extraction scenarios, post-extraction file count never exceeds
maxMemoryFiles
- Preservation properties: for all valid update operations, updates are applied regardless of creation caps
- Round-trip properties: building a prompt and parsing a conforming JSON response always produces valid
FileOperationobjects
This approach caught the exponential file creation bug during development — the property test generated a scenario where 200+ files were created in a single pass, which would have been missed by hand-written examples.
Getting started
Bash
npm install agent-memory-daemonnpx agent-memory-daemon init# Edit memconsolidate.toml with your Bedrock configurationnpx agent-memory-daemon start
The project is MIT-licensed and available on GitHub . Contributions are welcome — see CONTRIBUTING.md for development setup and guidelines.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article