
Building Open Data Lakes on AWS with Apache Iceberg and Dataddo
➔ Apache Iceberg enables open, flexible analytics architectures ➔ Dataddo manages reliable ingestion of data into Iceberg ➔ AWS Glue provides transformation and governance ➔ Together, AWS and Dataddo enable flexible, scalable data lakes on AWS
By: Len Gomes, Partner Solutions Architect - AWS
By: Andreas Kitsios, AWS Partner Solutions Architect - AWS
By: Juraj Slota - Head of Partnership - Dataddo
Apache Iceberg has become a foundational open table format for analytics on Amazon S3 . It enables reliable, scalable, and transferable data assets that can be accessed by a growing ecosystem of analytics services. By separating storage from compute and standardising table metadata, Iceberg allows organisations to evolve how data is processed and queried over time without rearchitecting their data lake.
AWS provides comprehensive native support for Apache Iceberg across its analytics portfolio, including Amazon S3 for storage, AWS Glue for serverless data integration and cataloguing, Amazon Athena for interactive SQL queries, and Amazon EMR for large-scale data processing. This integrated ecosystem enables organisations to build open, flexible data lake architectures that separate storage from compute and support multiple analytics engines simultaneously.
While AWS services excel at transformation, governance, and analytics, many organizations encounter persistent operational challenges when ingesting data from hundreds of disparate source systems. Dataddo complements the AWS analytics ecosystem including AWS Glue by providing a fully managed ingestion layer for Apache Iceberg on AWS, focusing on connectivity, operational reliability, and ongoing pipeline management.
Dataddo brings data from ERPs, SaaS applications, databases, and APIs into Iceberg tables on Amazon S3. It handles incremental loading, schema evolution, ingestion-level metadata, and business-level context as source systems change over time. By handling ingestion complexity upstream, Dataddo reduces the engineering effort required to reliably populate Iceberg tables and allows AWS Glue to be used where it delivers the most value data transformation, enrichment, and orchestration.
Together, Dataddo and AWS Glue enable organisations to adopt Apache Iceberg more quickly, reduce engineering overhead in data pipeline operations, and build open, scalable data lake architectures on AWS that evolve alongside changing business requirements.
1. Apache Iceberg on AWS: A Brief Overview
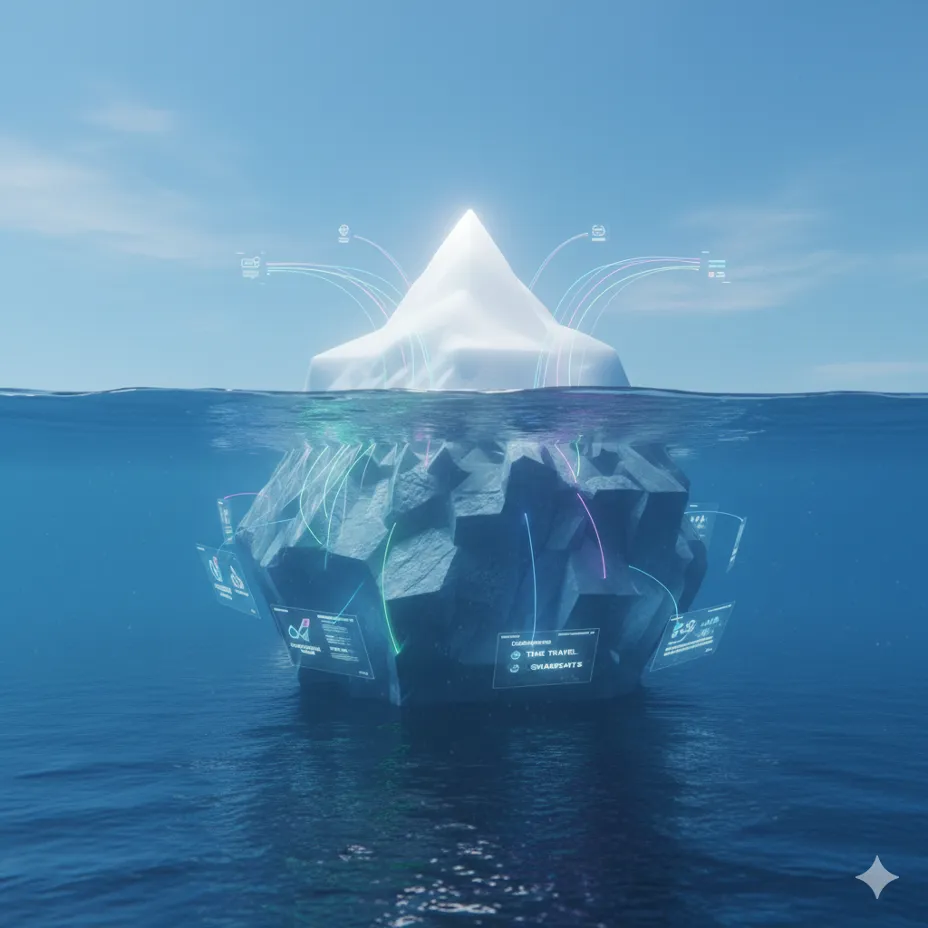
Apache Iceberg is a distributed, community-driven, Apache 2.0-licensed, 100% open-source table format designed for managing large analytic datasets stored in object storage systems such as Amazon S3. Rather than defining how data is queried, Iceberg standardises how data is organised, versioned, and accessed, enabling consistent and reliable analytics at scale. The name "Iceberg" reflects the architecture's design philosophy: the table abstraction that users interact with represents only the visible surface, while sophisticated metadata management and versioning systems handle the complexity beneath.
On AWS, Apache Iceberg serves as the foundational layer for building modern transactional data lakes centralized repositories that not only store structured and unstructured data at any scale but also support transactional operations with guaranteed data accuracy and consistency. Iceberg enables data lakes to provide ACID properties (Atomicity, Consistency, Isolation, and Durability), bringing database-grade reliability to cloud object storage:
- Atomicity: Guarantees that each transaction is a single event that either succeeds or fails completely; there is no partial completion state
- Consistency: Ensures that all data written is valid according to defined rules, maintaining data accuracy and reliability across all operations
- Isolation: Enables multiple transactions to occur simultaneously without interfering with each other, ensuring that each transaction executes independently
- Durability: Guarantees that data is not lost or corrupted once a transaction is committed, with recovery capabilities in the event of system failures.
Iceberg is designed to be independent of any single query engine, data stored in Iceberg tables on Amazon S3 can be accessed by multiple analytics services. This includes Amazon Athena for interactive SQL querying, Amazon EMR for large-scale Spark processing, AWS Glue for serverless ETL, and Amazon Redshift for data warehousing. Furthermore, third-party business intelligence tools like Power BI and Tableau can seamlessly connect to Iceberg tables by querying them through services such as Amazon Athena.
By separating storage from compute and using open table metadata, Iceberg enables organisations to build durable, transferable data assets. Teams can evolve how data is transformed, queried, and consumed over time (adopting new services or analytics tools), without rearchitecting the underlying data lake.
This flexibility makes Apache Iceberg an ideal architectural fit for environments where scalability, interoperability, and future-proof agility are key priorities.
2. AWS Glue: The Data Transformation and Governance Layer
AWS Glue is a serverless data integration service that plays a central role in Apache Iceberg architectures on AWS by providing managed services for data transformation, orchestration, and governance. As a fully managed service, AWS Glue eliminates infrastructure provisioning and maintenance, allowing teams to focus on data transformation logic using Apache Spark-based workflows.
AWS Glue Data Catalog : A key component of this architecture is the AWS Glue Data Catalog, which serves as a centralised metadata repository and shared metadata layer for Iceberg tables. By registering Iceberg table metadata in the Data Catalog, multiple AWS services including Amazon Athena, Amazon EMR, and AWS Lake Formation , can consistently discover and access the same datasets. This shared catalog ensures that schema changes and table evolution are handled in a controlled and transparent way, providing a single source of truth for all data assets.
Auto Scaling and Performance: AWS Glue automatically adjusts the number of workers based on workload demands, optimising both cost and performance. This dynamic resource allocation ensures efficient job execution without over-provisioning resources.
AWS Glue is particularly well suited for transformation-heavy workloads, such as data enrichment, normalisation, aggregation, and dimensional modelling. Glue jobs can operate directly on Iceberg tables, enabling teams to apply complex business logic while benefiting from Iceberg's transactional guarantees and schema evolution capabilities.
By separating transformation and governance concerns from ingestion, AWS Glue allows organisations to scale data processing independently of how data is sourced. This makes Glue a foundational service for building maintainable, production-grade Iceberg pipelines on AWS, especially as data volumes, teams, and use cases grow over time.
3. The Ingestion Challenge in Iceberg Architectures
While Apache Iceberg and AWS Glue provide a strong foundation for managing and transforming data on AWS, many teams encounter their first and most persistent challenges earlier in the pipeline: data ingestion.
Modern analytics environments rely on data from a growing number of operational systems, including ERPs, SaaS applications, business platforms, custom APIs, and transactional databases. Ingesting this data reliably requires more than simply extracting and loading records into storage. Teams must manage authentication, API limits, incremental updates, schema changes, and data consistency often across dozens or hundreds of sources. For instance, a typical enterprise may need to ingest data from Salesforce (REST API with OAuth), SAP (BAPI connections), and internal databases each requiring different authentication mechanisms, error handling strategies, and schema mapping approaches.
These challenges persist over time. Source systems evolve continuously, introducing new fields, deprecating existing ones, or changing API behaviour. Without active management, ingestion pipelines can become brittle, leading to data gaps, broken downstream jobs, and increased operational overhead.
While AWS Glue excels at transformation and enrichment, using it primarily for source system connectivity requires additional engineering effort, infrastructure management, and ongoing monitoring especially as the number of sources scales. Setting up ingestion-focused jobs demands expertise in rate limiting management, connection pooling, retry logic, checkpointing for fault tolerance, and metadata management for incremental loads.
As a result, many organisations benefit from a dedicated ingestion layer that abstracts connectivity and operational complexity, allowing Iceberg tables to be populated reliably while downstream services focus on transformation, governance, and analytics.
4. Dataddo: Managed Ingestion into Apache Iceberg
Dataddo is an AWS Advanced Partner and holder of the AWS Data & Analytics ISV Competency. It provides a fully managed ingestion layer purpose-built to populate Apache Iceberg tables on Amazon S3 reliably and at scale. With 400+ connectors covering SaaS applications, ERPs and databases, Dataddo focuses on the solving the challenges of ingesting from large, constantly evolving source environments: connectivity across systems, schema evolution, operational reliability, pipeline observability, and preserving business-level context as data moves into Iceberg tables.
AWS Glue Integration for Apache Iceberg: Dataddo's integration with AWS Glue for Apache Iceberg enables direct writing to Iceberg tables with automatic registration in the AWS Glue Data Catalog. Dataddo writes data in Apache Parquet format Iceberg's default file format and manages Iceberg metadata files, snapshots, and manifests automatically, ensuring compatibility with all Iceberg-compatible query engines on AWS.
At the core of Dataddo’s approach is deep connector expertise. Dataddo offers 400+ prebuilt connectors, with new sources added on an ongoing basis, covering SaaS applications, ERPs, operational databases, and public or custom APIs. These connectors are built to deliver analytics-ready data into Iceberg tables with minimal configuration and without requiring custom ingestion code.
Unlike one-time integrations, Dataddo connectors are actively managed over time. This includes adapting to API version changes, handling schema evolution, introducing newly available fields, and responding to field deprecations or breaking changes in source systems. By continuously maintaining connectors, Dataddo helps ensure that ingestion pipelines remain stable as upstream systems evolve.
Dataddo maintains ingestion-level metadata to support reliable pipeline operation. This includes tracking schema changes, load state, and pipeline health, enabling observability and operational control as ingestion scales across many sources and datasets.
In addition to technical ingestion metadata, Dataddo preserves business-level context for ingested data. This includes human-readable, source-native descriptions of metrics and attributes such as how “Clicks” are defined in Facebook Ads or what constitutes a “Lead” in HubSpot. This source-native context is preserved as column-level metadata in Iceberg tables, making it accessible to downstream users querying through Amazon Athena or analysing data with business intelligence tools.
Dataddo also provides purpose-built capabilities for operating ingestion pipelines in production environments, including support for incremental loading, historical backfills, and high-frequency or high-volume synchronisation. Built-in controls for sensitive data handling, compliance requirements, and monitoring allow teams to operate ingestion pipelines confidently at scale.
Deployment Model: Dataddo operates as a managed SaaS service, with data written directly to customer-owned Amazon S3 buckets, ensuring data residency and security requirements are met.
5. Dataddo and AWS Glue: Complementary by Design
Dataddo and AWS Glue address different stages of the data pipeline and are designed to work together in Apache Iceberg architectures on AWS. This architectural pattern follows AWS best practices for separation of concerns: purpose-built services for each stage of the data pipeline enable better scalability, maintainability, and operational efficiency.
Dataddo focuses on connectivity and ingestion, providing a managed layer for reliably bringing data from a wide range of operational systems into Iceberg tables on Amazon S3. By absorbing the ongoing complexity of source integration, schema evolution, and pipeline operation, Dataddo ensures that Iceberg tables are consistently populated with analytics-ready data.
AWS Glue complements this by serving as the transformation, orchestration, and governance layer. Once data is available in Iceberg tables, AWS Glue ETL jobs can apply enrichment, normalisation, aggregation, and modeling logic at scale, using the AWS Glue Data Catalog as the authoritative metadata layer for table discovery and schema management.
As part of ingestion, Dataddo delivers data into Apache Iceberg tables on Amazon S3 and ensures those tables are registered in the AWS Glue Data Catalog with complete schema metadata, partition information, and table properties making them immediately queryable through Amazon Athena and accessible to AWS Glue ETL jobs without additional configuration. This allows Glue workflows to operate on up-to-date data without requiring additional ingestion logic or custom integrations.
This separation of responsibilities allows each service to be used where it delivers the most value. Dataddo preserves business context and operational reliability upstream, reducing the complexity of downstream transformation logic. AWS Glue, in turn, can focus on high-value processing and governance without being burdened by source-specific connectivity concerns.
Together, Dataddo and AWS Glue enable teams to accelerate time to first analytics use case, operate ingestion and transformation pipelines more efficiently, and maintain flexible Iceberg-based architectures that can evolve alongside changing data sources and analytics requirements.
6. Reference Architecture: From Source to Analytics
The following reference architecture illustrates how Dataddo and AWS Glue work together to support Apache Iceberg–based analytics on AWS, with clear separation between ingestion, transformation, and consumption.
Data Flow: Operational sources → Dataddo (extraction & schema handling) → Apache Iceberg tables on Amazon S3 → AWS Glue Data Catalog (metadata registration) → AWS Glue (transformation) → Updated Iceberg tables → Amazon Athena/EMR (query & analytics).
Dataddo sits upstream as a managed ingestion layer, connecting to a wide range of operational data sources such as SaaS applications, ERPs, databases, and APIs. This includes both prebuilt connectors and custom connectors for proprietary or less common systems. Using its managed connectors, Dataddo ingests data into Apache Iceberg tables stored in Amazon S3, handling incremental updates, schema evolution, operational reliability, ingestion-level metadata, and business-level context.
As part of ingestion, Iceberg tables are registered in the AWS Glue Data Catalog, which serves as the authoritative metadata layer for table discovery and governance across AWS analytics services. AWS Lake Formation can be layered on top of the AWS Glue Data Catalog to provide fine-grained access control, ensuring that users and applications only access data they're authorized to see, with full audit logging for compliance requirements.
AWS Glue then operates downstream, using Spark-based jobs to transform, enrich, and model data stored in Iceberg tables. These transformed datasets can be queried and consumed using Amazon Athena for interactive SQL queries, Amazon EMR for large-scale batch processing, and other AWS-native analytics services.
Monitoring and Observability: The architecture includes comprehensive observability through Amazon CloudWatch for monitoring AWS Glue job execution and resource utilization, Dataddo's built-in pipeline monitoring for ingestion health, and AWS CloudTrail for auditing data access and modifications across all components.
Versioning: Because Iceberg maintains complete version history, teams can query historical snapshots for auditing, reproduce previous analysis results, or rollback problematic data loads all through standard SQL time travel queries in Amazon Athena.
Security: Data is encrypted at rest using AWS KMS (for Amazon S3) and in transit using TLS. IAM roles and policies control access to AWS resources, while the AWS Glue Data Catalog integrates with AWS Lake Formation for table and column-level permissions.
This architecture enables teams to ingest data reliably at scale, apply transformations where needed, and maintain flexible, open data lake foundations that evolve alongside analytics requirements.

7. Getting Started with Iceberg on AWS
Getting started with Dataddo and Apache Iceberg on AWS is designed to be simple and straightforward, helping teams move quickly from initial setup to production-ready analytics.
Prerequisites:
- AWS account with appropriate IAM permissions for Amazon S3, AWS Glue, and Amazon Athena
- Amazon S3 bucket designated for Iceberg table storage
- AWS Glue Data Catalog database created for table registration
Note: Take advantage of Iceberg-specific settings such as:
| 1 | 2 |
|---|---|
| Snapshot Retention Policy | Manages Iceberg's core time-travel functionality: retaining historical table versions, which is essential for audit and rollback while controlling data volume. |
| Partitioning Strategy | Iceberg facilitates flexible partitioning through hidden partitioning and partition evolution, allowing architects to update schemas for query patterns without costly data rewrites. |
| Write/Sort Ordering | An Iceberg-native optimization sort-based data skipping, significantly reducing query engines data scans for improved performance and cost. |
| Metadata File Cleanup | Transactional garbage collection on unreferenced metadata, optimizing the AWS Glue Data Catalog and speeding up table operations. |
| Data Compaction Strategy | Iceberg performs file compaction transactionally (ACID) by safely rewriting metadata pointers, making the necessary file merging process reliable and efficient. |
Implementation steps:
1. Provision Dataddo via AWS Marketplace .
Dataddo is an AWS Partner and can be provisioned through AWS Marketplace, enabling customers to use the same procurement, billing, and vendor onboarding process they already use for other AWS services and partner solutions. The deployment process takes minutes and includes automatic IAM role configuration for secure access to your Amazon S3 buckets and AWS Glue Data Catalog. Billing is consolidated through your AWS account for simplified vendor management.
2. Connect your source systems.
Use Dataddo’s prebuilt (or custom) connectors to connect SaaS applications, ERPs, databases, and APIs. Dataddo manages authentication and ongoing connector maintenance as source systems evolve.
3. Connect them to your Iceberg destination on Amazon S3.
Configure Dataddo to write into Apache Iceberg tables stored in the customer’s Amazon S3 environment, aligned to desired dataset structure and refresh cadence.
4. Register tables in the AWS Glue Data Catalog.
Ensure Iceberg tables are registered and kept up to date in the AWS Glue Data Catalog so they are discoverable and usable across AWS analytics services. Verify registration by running SHOW TABLES in Amazon Athena or checking the AWS Glue Data Catalog console to confirm table metadata, schema, and partitions are visible.
5. Transform and model with AWS Glue.
Use AWS Glue jobs to enrich, aggregate, and model data stored in Iceberg tables, applying business logic and producing curated datasets for downstream consumption.
6. Validate and Monitor
- Use AWS Glue Data Quality to validate data completeness and accuracy
- Set up Amazon CloudWatch alarms for job failures or performance degradation
- Review Dataddo's pipeline dashboards for ingestion metrics and data quality indicators
7. Query and consume with AWS analytics services.
Access Iceberg tables using Amazon Athena, Amazon EMR, and other AWS-native or third-party services to support interactive analytics, batch processing, and downstream applications.
Dataddo provides expert onboarding assistance to help teams design ingestion pipelines, configure Iceberg destinations, and align with AWS best practices accelerating time to value and ensuring a smooth setup from day one.
8. Conclusion: Building Open, Scalable Iceberg Pipelines on AWS
Apache Iceberg provides a durable foundation for analytics on Amazon S3, enabling organisations to build data lake architectures that remain reliable, scalable, and adaptable as analytics needs evolve. AWS services such as AWS Glue, Amazon Athena, and Amazon EMR form a powerful native ecosystem for transforming, governing, and querying Iceberg-based datasets.
As Iceberg adoption grows, the complexity of ingesting data from operational systems becomes a critical consideration. By introducing a dedicated ingestion layer, teams can simplify pipeline operations while preserving the flexibility and openness that Iceberg enables.
Dataddo complements AWS Glue by addressing ingestion complexity upstream, providing managed connectivity, schema-aware ingestion, operational reliability, and business context for data arriving in Iceberg tables. Together, Dataddo and AWS Glue enable organisations to move more quickly from raw data to analytics-ready datasets, while maintaining clear separation of responsibilities across the data pipeline.
This combined approach allows teams to adopt Apache Iceberg without building custom ingestion infrastructure, eliminates ongoing maintenance of source-specific integration code, and provides production-ready reliability for enterprise-scale operations. As data volumes continue to grow and analytics requirements become more sophisticated, the partnership between Dataddo and AWS positions organisations to meet evolving demands while maintaining agility to adopt new technologies as they emerge
Dataddo is available now through AWS Marketplace , enabling you to provision a fully managed ingestion layer for Apache Iceberg in minutes. Whether you're building your first Iceberg-based data lake or scaling existing analytics workloads, the combination of Dataddo and AWS Glue provides the foundation for flexible, reliable, and future-proof data architectures on Amazon S3. For more information on implementing Apache Iceberg on AWS, visit the AWS Prescriptive Guidance for Apache Iceberg documentation. To learn more about Dataddo's AWS Glue integration, visit AWS Marketplace.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article