
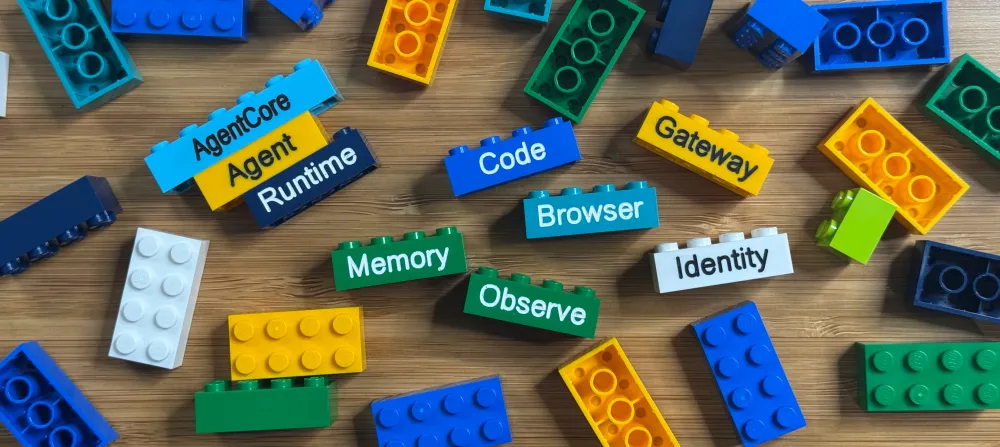
Turn Your AI Script into a Production-Ready Agent
Deploy production AI agents on Amazon Bedrock AgentCore in minutes. Add features like persistent memory, secure code execution, and automatic scaling.
You've built an AI agent that works perfectly on your laptop. And when you try to deploy it to production, you hit a wall of infrastructure complexity. You need persistent memory, secure code execution, automatic scaling, and enterprise-grade observability. Building this from scratch takes months.
This guide gets you from zero to a deployed production AI agent in under 10 minutes. You'll start with a simple agent and deploy it to Amazon Bedrock AgentCore Runtime immediately, then explain what just happened and progressively add advanced capabilities.
Quick Start: Deploy Your First Agent Now
⚠️ Prerequisites: You'll need AWS credentials configured anduv(Python package manager) installed. If you need help with setup, you can skip the Quick Start and head to the Tutorial section below.
Here's a complete AI agent with calculation capabilities ready for AgentCore. (It uses the Strands Agents framework, but you can use any framework as you'll see later):
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
"""
Production-Ready AI Agent for Amazon Bedrock AgentCore
"""
from strands import Agent
from strands_tools import calculator
from bedrock_agentcore.runtime import BedrockAgentCoreApp
app = BedrockAgentCoreApp()
MODEL_ID = "us.anthropic.claude-3-7-sonnet-20250219-v1:0"
def invoke(payload, context):
"""AgentCore Runtime entry point"""
agent = Agent(
model=MODEL_ID,
system_prompt="You are a helpful assistant that can perform calculations. Use the calculate tool for any math problems.",
tools=[calculator]
)
prompt = payload.get("prompt", "Hello!")
result = agent(prompt)
return {
"response": result.message.get('content', [{}])[0].get('text', str(result))
}
if __name__ == "__main__":
app.run()Deploy to production:
1
2
3
4
5
6
7
8
9
# 1. Create project and install dependencies
mkdir agentcore-tutorial && cd agentcore-tutorial
uv init --no-workspace && uv add bedrock-agentcore-starter-toolkit

# 2. Create a deployment folder and add the pyproject.toml file needed:
mkdir agent_deployment
uv init --bare ./agent_deployment && uv --directory ./agent_deployment add strands-agents bedrock-agentcore strands-agents-tools

# 3. Save the agent code above in to the agent_deployment folder as tutorial_agent.py
🐍 It's just a Python agent You can run this code directly in your environment withuv run python quick_agent.pyand it should greet you with "Hello!"
1
2
3
4
5
6
7
8
# 3. Configure and deploy
# Use all default answers for now:
uv run agentcore configure -e ./agent_deployment/tutorial_agent.py

uv run agentcore launch

# 4. Test your deployed agent
uv run agentcore invoke '{"prompt": "What is 25 * 4 + 10?"}'
Congratulations! You just deployed a production AI agent to the cloud with automatic scaling, managed infrastructure, and built-in observability. It's running on AWS at enterprise-grade.
Want to test the container before deployment? If you have Docker or similar container technology in your environment, you can run this agent locally in an AgentCore container by runninguv run agentcore launch --local.
What Just Happened?
You deployed an agent to Amazon Bedrock AgentCore Runtime - a managed hosting service and part of AgentCore.
AgentCore is an enterprise-grade framework for building, deploying, and operating generative-AI agents securely at scale. It provides the primitives and runtime infrastructure to connect models with tools, APIs, and data sources, all while enforcing isolation, observability, and compliance. With built-in scalability, auditability, and AWS-level security, AgentCore enables developers to move from prototype to production confidently — without managing underlying infrastructure.
In your example the
@app.entrypoint decorator is the only difference between a local script and a cloud-deployed agent. AgentCore handles containerization, deployment, and scaling automatically.Tutorial
Understanding AgentCore Components
Amazon Bedrock AgentCore consists of multiple independent services that can be used separately or together. You just used AgentCore Runtime, but there are several other powerful services available:
| Service | Purpose | When to Use |
|---|---|---|
| Runtime ✅ | Managed hosting environment for AI agents | Deploy any agent for automatic scaling and observability |
| Memory 📚 | Persistent conversation storage and intelligent fact extraction | Need conversation history or cross-session user preferences |
| Gateway ⭐ | Fully managed service for hosting Model Context Protocol (MCP) tools | Connect agents to existing business systems and APIs |
| Code Interpreter 🐍 | Secure Python execution sandbox with pre-installed libraries | Agent needs calculations, data analysis, or visualizations |
| Browser Tool 🌐 | Secure, cloud-based browser for agents to interact with websites | Web scraping, automated testing, legacy system integration |
| Identity 🔐 | Secure identity and access management for agents | Agents acting on behalf of users with proper authentication |
| Observability 📊 | Comprehensive monitoring and debugging for agent workflows | Need visibility into agent performance and debugging |
This Tutorial's Focus: You'll progressively add Memory, Code Interpreter, and Observability to your deployed agent. Each AgentCore capability works independently or together based on your needs.
Prerequisites and Setup
⚡ If you already have an AWS account configured with Bedrock access and the AWS CLI setup, you can skip to the Install Required Tools section.
AWS Account and Permissions
You'll need an AWS account with appropriate permissions. If you're using admin access, you can skip the detailed permissions setup. Otherwise, you'll need the IAM policy detailed in the AgentCore documentation.
Enable Bedrock Model Access
You will also need to enable access to at least Claude 3.7 Sonnet in your AWS region:
- Go to AWS Console → Amazon Bedrock → Model access
- Click "Enable specific models"
- Find and enable "Claude 3.7 Sonnet"
- Wait for the status to show "Access granted"
Install Required Tools
⚡ If you already have
uv installed and configured, you can skip to the Create Project Environment section.What is uv?
You'll use
uv as your Python package manager throughout this tutorial. uv is a modern, extremely fast Python package and project manager written in Rust, it's 10-100x faster than pip for package installation, handles virtual environments and dependencies automatically, and provides deterministic dependency resolution that prevents "works on my machine" issues.This tutorial will step you through what you need to do, but if you're new to
uv, think of it like this: uv init creates a new Python project with pyproject.toml (similar to requirements.txt), uv add package adds dependencies to your project (similar to running pip install), uv run command runs commands in the project's virtual environment without manual activation, and uv sync ensures your environment matches the lock file.For this tutorial, you'll primarily use
uv run to execute commands, which automatically manages the virtual environment for you.Install uv
macOS/Linux:
1
curl -LsSf https://astral.sh/uv/install.sh | sh
Windows:
1
powershell -ExecutionPolicy ByPass -c "irm https://astral.sh/uv/install.ps1 | iex"
Alternative (using pip):
1
pip install uv
Verify Installation:
1
uv --version
Configure AWS CLI
⚡ If you already have the AWS CLI configured with valid credentials, you can skip this step.
1
2
3
4
5
6
# Install AWS CLI if you haven't already
uv tool install awscli

# Configure your credentials
aws configure
# Enter your AWS Access Key ID, Secret Access Key, region (e.g., us-west-2), and output format (json)
For detailed instructions on setting up AWS credentials, see the AWS CLI Quick Start Guide .
Create Project Environment
Tip: If you did this already in the quick start then you can skip to Understanding How to Work with AgentCore.
1
2
3
4
5
6
7
# Create a new directory for our project
mkdir agentcore-tutorial
cd agentcore-tutorial

# Initialize Python environment with uv for development tools
uv init
uv add bedrock-agentcore-starter-toolkit
Create Agent Deployment Directory
For AgentCore deployment (using the Starter Toolkit - more details later), it's best to create a separate directory containing only the dependencies required by your agent code (without the development tools like the starter toolkit etc):
1
2
3
4
5
# Create and initialize deployment directory for our agent code
mkdir agent_deployment

# (Note: We add in all the dependencies here, including the ones we use later on.)
uv init --bare ./agent_deployment && uv --directory ./agent_deployment add strands-agents bedrock-agentcore strands-agents-tools
📁 Why Two Directories?* Main project: Contains your development tools (starter toolkit, testing tools) for managing and deploying your agents* agent_deployment: Contains only your agents runtime dependencies that get packaged into your deployed container* This separation keeps your deployed container lean and secure while providing access to your development capabilities
Understanding How to Work with AgentCore
Let's understand how you interact with Amazon Bedrock AgentCore. There are three layers that provide different levels of abstraction:
The Three Layers of AgentCore
| Layer | Component | Purpose | How You'll Use It |
|---|---|---|---|
| 3 | AgentCore Starter Toolkit / CLI | Command-line interface for deployment and management that automates infrastructure setup, containerization, and deployment while handling complex orchestration of multiple AgentCore services | You'll use this throughout the tutorial with commands like agentcore configure and agentcore launch |
| 2 | AgentCore SDK | Python-specific SDK providing convenience methods and integrations with helper functions for quickly creating and managing AgentCore resources that spans both Control and Data Planes with simplified interfaces | You'll use this in your agent code for memory and runtime integration |
| 1 | Control Plane API | Resource management operations | Low-level access via standard AWS SDKs (boto3, AWS CLI) for maximum flexibility and control |
| 1 | Data Plane API | Runtime operations | Low-level access via standard AWS SDKs (boto3, AWS CLI) for maximum flexibility and control |
In your project setup, you installed both the AgentCore SDK and Starter Toolkit via the
bedrock-agentcore-starter-toolkit package. This gives you access to both the programmatic SDK features and the CLI management tools you'll use in the following steps.Agent Framework Flexibility
Amazon Bedrock AgentCore works with pretty much any agent framework. Whether you're using LangChain for building LLM applications, LlamaIndex as a data framework, CrewAI for multi-agent orchestration, your own custom code, or Strands Agents as an open-source framework, AgentCore provides the managed runtime, memory, and tools while your chosen framework handles the conversation logic and orchestration.
For this tutorial, you'll use Strands Agents, an open-source framework developed by AWS that emphasizes model-driven orchestration (leveraging LLM reasoning for planning and task execution), works with any LLM provider (Bedrock, OpenAI, Anthropic, local models), and provides simple multi-agent primitives with built-in support for handoffs, swarms, and graph workflows.
🚀 Already Have an Agent? You can apply the same principles demonstrated here to migrate any existing agent to cloud-scale production. The key patterns work with any agent implementation.
Deploy Your First Agent (Detailed Tutorial)
Now that you have your development environment properly set up with the structured project directories, let's deploy your first agent using the detailed approach. If you completed the Quick Start earlier, we're essentially starting fresh here with a more thorough setup that will support the advanced features we'll add later.
Create Your Agent
In your
agent_deployment directory, create tutorial_agent.py:1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
"""
Production-Ready AI Agent for Amazon Bedrock AgentCore
"""
from strands import Agent
from strands_tools import calculator
from bedrock_agentcore.runtime import BedrockAgentCoreApp
app = BedrockAgentCoreApp()
MODEL_ID = "us.anthropic.claude-3-7-sonnet-20250219-v1:0"
def invoke(payload, context):
"""AgentCore Runtime entry point"""
agent = Agent(
model=MODEL_ID,
system_prompt="You are a helpful assistant that can perform calculations. Use the calculate tool for any math problems.",
tools=[calculator]
)
prompt = payload.get("prompt", "Hello!")
result = agent(prompt)
return {
"response": result.message.get('content', [{}])[0].get('text', str(result))
}
if __name__ == "__main__":
app.run()Deploy to AgentCore Runtime
IMPORTANT: When prompted for the pyproject.toml file, navigate and select the toml file in the agent_deployment directory. Select the default answers for the other questions.
1
2
3
4
5
6
7
8
9
# From your main project directory (agentcore-tutorial)
# Configure the agent:
uv run agentcore configure -e agent_deployment/tutorial_agent.py

# Deploy to production
uv run agentcore launch

# Test your deployed agent
uv run agentcore invoke '{"prompt": "What is 25 * 4 + 10?"}'
Understanding Your Deployed Agent
The agent you just deployed uses the @app.entrypoint decorator that makes your agent deployable to AgentCore Runtime.
The
@app.entrypoint decorator is the only difference between a local script and a cloud-deployed agent. It tells AgentCore Runtime how to invoke your agent with structured input (payload) and return structured output.Check Your Deployment
1
uv run agentcore status
This shows your agent's status, endpoint information, and observability dashboard URLs.
💡 Deep Dive: Invoking from Production Applications: The Starter Toolkit is great for testing, but how do you invoke your agent from production applications? Use the AWS SDK (e.g. boto3) to call your deployed agent directly:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
import boto3
import json

# Initialize the AgentCore client
client = boto3.client('bedrock-agentcore', region_name='us-west-2')

# Get your agent ARN from: uv run agentcore status
agent_arn = "arn:aws:bedrock-agentcore:us-west-2:123456789012:runtime/your-agent-name"

# Invoke the agent
response = client.invoke_agent_runtime(
    agentRuntimeArn=agent_arn,
    runtimeSessionId="production_session_2024_user456_webapp_xyz123",
    payload=b'{"prompt": "What is 25 * 4 + 10?"}'
)

# Parse the response
result = json.loads(response['response'].read())
print(result['response'])
Key Points for Production Use:* Agent ARN: Get this fromuv run agentcore statusoutput* Session IDs: Must be 33+ characters* Authentication: Uses your AWS credentials (IAM roles, access keys, etc.)* Streaming: AgentCore supports streaming responses for real-time applicationsThis is how you'd integrate your agent into web applications, mobile backends, or other AWS services like Lambda functions.
Adding Memory
Your agent running on AgentCore Runtime already provides some memory capabilities included. When you deploy to Runtime, your agent gets a dedicated container instance for every session that can run for up to 8 hours and stays pinned to that session ID. This means that within a single session, your agent can maintain conversation history and state as long as the container stays alive (up to 8 hours or 15 minutes of inactivity).
However, some production AI agents may need additional memory capabilities. What happens when the container restarts? What about remembering user preferences across different sessions days or weeks apart? What about extracting and storing important facts from conversations for long-term use?
This is where AgentCore Memory comes in. It provides both short-term memory (persistent conversation history that survives container restarts) and long-term memory (extracted facts and preferences that work across sessions and time periods).
Update your
tutorial_agent.py file to add memory, (I will step through all the changes in a moment):1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
"""
Production-Ready AI Agent with Memory
Remembers conversations and user preferences across sessions
"""
import os
from strands import Agent
from strands_tools import calculator
from bedrock_agentcore.runtime import BedrockAgentCoreApp
from bedrock_agentcore.memory.integrations.strands.config import AgentCoreMemoryConfig, RetrievalConfig
from bedrock_agentcore.memory.integrations.strands.session_manager import AgentCoreMemorySessionManager
app = BedrockAgentCoreApp()
MEMORY_ID = os.getenv("BEDROCK_AGENTCORE_MEMORY_ID")
REGION = os.getenv("AWS_REGION", "us-west-2")
MODEL_ID = "us.anthropic.claude-3-7-sonnet-20250219-v1:0"
# Global agent instance
_agent = None
def get_or_create_agent(actor_id: str, session_id: str) -> Agent:
"""
Get existing agent or create new one with memory configuration.
Since the container is pinned to the session ID, we only need one agent per container.
"""
global _agent
if _agent is None:
# Configure memory with retrieval for user facts and preferences
memory_config = AgentCoreMemoryConfig(
memory_id=MEMORY_ID,
session_id=session_id,
actor_id=actor_id,
retrieval_config={
f"/users/{actor_id}/facts": RetrievalConfig(top_k=3, relevance_score=0.5),
f"/users/{actor_id}/preferences": RetrievalConfig(top_k=3, relevance_score=0.5)
}
)
# Create agent with memory session manager
_agent = Agent(
model=MODEL_ID,
session_manager=AgentCoreMemorySessionManager(memory_config, REGION),
system_prompt="You are a helpful assistant with memory. Remember user preferences and facts across conversations. Use the calculate tool for math problems.",
tools=[calculator]
)
return _agent
def invoke(payload, context):
"""AgentCore Runtime entry point with lazy-loaded agent"""
if not MEMORY_ID:
return {"error": "Memory not configured. Set BEDROCK_AGENTCORE_MEMORY_ID environment variable."}
# Extract session and actor information
actor_id = context.request_headers.get('X-Amzn-Bedrock-AgentCore-Runtime-Custom-Actor-Id', 'user') if context.request_headers else 'user'
session_id = context.session_id or 'default_session'
# Get or create agent (lazy loading)
agent = get_or_create_agent(actor_id, session_id)
prompt = payload.get("prompt", "Hello!")
result = agent(prompt)
return {
"response": result.message.get('content', [{}])[0].get('text', str(result))
}
if __name__ == "__main__":
app.run()Understanding Memory Integration and Lazy Loading
The key additions for memory:
In this code we make use of several AgentCore SDK convenience methods for Memory and Strands Agents:
- AgentCoreMemoryConfig: Configures how memory works for this agent.
- RetrievalConfig: Defines what information to retrieve (user facts and preferences)
- AgentCoreMemorySessionManager: Provides a Strands Agents Session Manager object that works with AgentCore Memory
The memory system provides two types of storage: Short-term Memory (STM) that stores exact conversation history within sessions, and Long-term Memory (LTM) that extracts and stores facts, preferences, and summaries across sessions.
Why Lazy Loading? Understanding AgentCore Runtime Lifecycle
Notice the
get_or_create_agent() function in our code. This "lazy loading" pattern is crucial for how AgentCore Runtime works, and understanding it will help you build more efficient agents.Runtime Spawning and Session Management:
AgentCore Runtime works like AWS Lambda but with some important differences. While Lambda functions are ephemeral and run for a single invocation, AgentCore Runtime instances are longer-lived, running up to 8 hours compared to Lambda's 15-minute maximum. Each session gets its own dedicated runtime instance, and that instance can handle multiple invocations while maintaining state between calls. This makes it perfect for conversational agents that need to remember context throughout a session. The runtime also supports streaming responses for real-time interactions and automatically cleans up after 15 minutes of inactivity or when it hits the 8-hour limit.
The Configuration Challenge:
When you use Memory, you need to configure it with the user's ID (the actor_id) and the session ID to connect to the right memories in storage. However, you don't know these values until the agent is actually invoked - they're not available when your Python module first loads. At the same time, you want to reuse the same agent instance for subsequent invocations to maintain conversation continuity and avoid the performance cost of recreating the agent every time. This creates a timing challenge: you need the session and actor information to create the agent, but you only get that information at runtime, not at startup.
Lazy Loading Solution:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
# Global agent instance - survives across invocations within the same runtime
_agent = None

def get_or_create_agent(actor_id: str, session_id: str) -> Agent:
    global _agent

    if _agent is None:
        # First invocation: create the agent
        memory_config = AgentCoreMemoryConfig(
            memory_id=MEMORY_ID,
            session_id=session_id,  # Available only at invocation time
            actor_id=actor_id       # Available only at invocation time
        )
        _agent = Agent(...)

    # Subsequent invocations: reuse the same agent
    return _agent
Why This Approach Works:
This lazy loading pattern works because on the first invocation, the agent is created with proper memory configuration using the session and actor information that's now available. For all subsequent invocations, the same agent instance is reused, which maintains conversation context and avoids the performance cost of recreating agents on every request. The agent's session manager maintains conversation state throughout the container's lifetime.
This design leverages AgentCore's container isolation model: since each session ID gets its own dedicated runtime instance, having one agent per container is both sufficient and secure. That's also why session IDs must be 33+ characters and should be complex - they serve as the key for spawning dedicated containers, prevent session hijacking, ensure isolated runtime environments, and scope memory operations properly.
Deploy with Memory
⚙️ Memory Configuration Prompts:
When you run the configure command, you'll see several prompts. Pay close attention to the memory setup:
- If you see "Existing memory resources found:" → Press Enter to create a new memory (don't select an existing one)
- "Enable long-term memory extraction? (yes/no)" → Type
yesand press Enter- This enables both short-term memory (conversation history) and long-term memory (extracted facts and preferences)
- For the
pyproject.tomlfile → Navigate to and select thepyproject.tomlfile in theagent_deploymentfolder - For all other prompts → Press Enter to accept the defaults (execution role, ECR repository, etc.)
⚠️ Important: Don't skip the memory configuration! If you accidentally select "no" for memory or miss these prompts, you'll need to reconfigure later (see troubleshooting section below).
1
2
# Configure with memory
uv run agentcore configure -e agent_deployment/tutorial_agent.py
The memory system will be configured to create both:
- Short-term Memory: Stores exact conversation history within sessions
- Long-term Memory: Extracts and stores user preferences, facts, and session summaries across sessions
1
2
3
4
5
# Deploy
uv run agentcore launch

# Check status - memory takes 2-3 minutes to provision
uv run agentcore status
Wait until you see:
- Memory: STM+LTM (3 strategies) displayed in green (indicating ACTIVE status)
- The memory information will be color-coded: green for ACTIVE, yellow for provisioning, red for errors
Troubleshooting: Memory Not Configured
If you don't see any Memory information in the status output, it means memory wasn't configured during setup. This is a common issue if you missed the memory prompts or selected "no" for memory configuration.
To fix this, reconfigure your agent:
1
2
# Reconfigure with memory
uv run agentcore configure -e agent_deployment/tutorial_agent.py
During configuration, you'll see these prompts:
- "Existing memory resources found:" (if you have existing memories)
- You'll see a numbered list of existing memories
- Recommendation: Press Enter to create a new memory instead of selecting an existing one
- This ensures the memory is properly attached to your agent configuration and will be included in cleanup
- "Enable long-term memory extraction? (yes/no)"
- Type
yesand press Enter to get both short-term and long-term memory - This enables the full memory capabilities demonstrated in this tutorial
- Type
- For all other prompts → Press Enter to accept defaults
Why create a new memory instead of using existing?
- New memories are automatically attached to your agent configuration
- They work seamlessly with this tutorial's examples
- They're included when you run
uv run agentcore destroyfor cleanup - Existing memories might have different configurations that could cause confusion
After reconfiguring, run
uv run agentcore launch again and check the status.Test Memory Across Sessions
Let's test the memory by storing information in one session and retrieving it in another:
1
2
# Session 1: Store user preferences
uv run agentcore invoke '{"prompt": "Remember that I absolutely love hot tea, especially Earl Grey, and I prefer it with a splash of milk and one sugar"}' --session-id 12345-12345-12345-12345-12345-12345-A --headers "Actor-Id:user123"
Wait 20 seconds for the long-term memory extraction to process:
1
sleep 20
Now test retrieval in a completely different session:
1
2
# Session 2: Different session, retrieve the preferences
uv run agentcore invoke '{"prompt": "What kind of hot drinks do I like and how do I prefer them prepared?"}' --session-id 12345-12345-12345-12345-12345-12345-B --headers "Actor-Id:user123"
The agent should respond: "You love hot tea, especially Earl Grey, and you prefer it with a splash of milk and one sugar."
This demonstrates cross-session memory persistence - the agent remembered information from a completely different conversation!
Adding Secure Code Execution
Now let's add secure code execution. While LLMs are incredibly powerful at understanding and generating text, they have limitations when it comes to precise calculations, complex data analysis, or creating visualizations. They're great at reasoning about problems but can struggle with tasks like "calculate the compound interest on $10,000 over 15 years with varying rates" or "analyze this dataset and create a statistical model."
This is where giving your agent the ability to write and execute code becomes transformative. Instead of trying to do math in its "head," your agent can write Python code to solve complex problems step by step. For example, when you ask about your tea consumption patterns, the agent can write code to calculate statistics, identify trends, and even create charts - tasks that would be error-prone or impossible with text generation alone.
Update your
tutorial_agent.py file to add secure code execution:1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
"""
Complete Production AI Agent
Memory + Secure Code Execution + Full Observability
"""
import os
from strands import Agent
from strands_tools.code_interpreter import AgentCoreCodeInterpreter
from bedrock_agentcore.runtime import BedrockAgentCoreApp
from bedrock_agentcore.memory.integrations.strands.config import AgentCoreMemoryConfig, RetrievalConfig
from bedrock_agentcore.memory.integrations.strands.session_manager import AgentCoreMemorySessionManager
app = BedrockAgentCoreApp()
MEMORY_ID = os.getenv("BEDROCK_AGENTCORE_MEMORY_ID")
REGION = os.getenv("AWS_REGION", "us-west-2")
MODEL_ID = "us.anthropic.claude-3-7-sonnet-20250219-v1:0"
# Global agent instance
_agent = None
def get_or_create_agent(actor_id: str, session_id: str) -> Agent:
"""
Get existing agent or create new one with memory configuration and code interpreter.
Since the container is pinned to the session ID, we only need one agent per container.
"""
global _agent
if _agent is None:
# Configure memory with retrieval for user facts and preferences
memory_config = AgentCoreMemoryConfig(
memory_id=MEMORY_ID,
session_id=session_id,
actor_id=actor_id,
retrieval_config={
f"/users/{actor_id}/facts": RetrievalConfig(top_k=3, relevance_score=0.5),
f"/users/{actor_id}/preferences": RetrievalConfig(top_k=3, relevance_score=0.5)
}
)
# Create agent with memory and code interpreter
_agent = Agent(
model=MODEL_ID,
session_manager=AgentCoreMemorySessionManager(memory_config, REGION),
system_prompt="You are a helpful assistant. Use tools when appropriate.",
tools=[AgentCoreCodeInterpreter(region=REGION).code_interpreter]
)
return _agent
def invoke(payload, context):
"""AgentCore Runtime entry point with lazy-loaded agent"""
if not MEMORY_ID:
return {"error": "Memory not configured. Set BEDROCK_AGENTCORE_MEMORY_ID environment variable."}
# Extract session and actor information
actor_id = context.request_headers.get('X-Amzn-Bedrock-AgentCore-Runtime-Custom-Actor-Id', 'user') if context.request_headers else 'user'
session_id = context.session_id or 'default_session'
# Get or create agent (lazy loading)
agent = get_or_create_agent(actor_id, session_id)
prompt = payload.get("prompt", "Hello!")
result = agent(prompt)
return {
"response": result.message.get('content', [{}])[0].get('text', str(result))
}
if __name__ == "__main__":
app.run()Understanding Code Interpreter Integration
The key change is replacing the simple calculator tool with
AgentCoreCodeInterpreter:1
tools=[AgentCoreCodeInterpreter(region=REGION).code_interpreter]This provides a secure Python sandbox where code runs in AWS's managed environment, pre-installed libraries including NumPy, Pandas, and Matplotlib, session management where code execution state persists within sessions, and automatic cleanup of sessions.
Complete Production Agent
Now you have a complete production agent with multiple AgentCore capabilities. Deploy it:
1
2
3
4
5
6
7
# Configure and deploy
uv --directory ./agent_deployment add strands-agents-tools[agent_core_code_interpreter]
uv run agentcore configure -e agent_deployment/tutorial_agent.py
uv run agentcore launch

# Check status and note the observability dashboard URL
uv run agentcore status
Test Complex Scenarios
Now let's test the complete agent with memory and code execution:
1
2
# Store tea consumption data
uv run agentcore invoke '{"prompt": "My daily tea consumption this week: [3, 5, 4, 6, 2, 4, 7] cups per day. Monday was light, Friday was crazy busy!"}' --session-id 12345-12345-12345-12345-12345-12345-C --headers "Actor-Id:user123"
1
2
# Perform complex analysis with detailed text output
uv run agentcore invoke '{"prompt": "Calculate the mean, median, and standard deviation of my tea consumption. Create a detailed ASCII bar chart showing daily patterns and provide statistical insights about my consumption trends. Present everything as formatted text - no image files needed."}' --session-id 12345-12345-12345-12345-12345-12345-C --headers "Actor-Id:user123"The agent should respond with a detailed analysis, including a bar chart and statistical insights. This demonstrates the agent's ability to perform complex calculations.
Observability and Monitoring
One of the key benefits of AgentCore is AgentCore Observability - a comprehensive monitoring service that has been automatically enabled when you deploy the agent with the Starter Toolkit. Let's explore what's available:
AgentCore Observability Dashboard
AgentCore Observability creates a comprehensive monitoring dashboard in CloudWatch. Get your dashboard URL:
1
uv run agentcore status
Look for the "GenAI Observability Dashboard" URL and open it in your browser. You'll see a comprehensive view of your agent's performance including a service map that visually shows your agent's connections to Memory and Code Interpreter services, request metrics displaying latency, throughput, and error rates, and detailed trace analysis with end-to-end request tracing powered by X-Ray.
Viewing Logs
1
2
3
4
5
# Get the exact log command from status output
uv run agentcore status

# Copy and run the log command shown, for example:
aws logs tail /aws/bedrock-agentcore/runtimes/AGENT_ID-DEFAULT --log-stream-name-prefix "2024/01/15/[runtime-logs]" --since 1h
Understanding Traces
In the CloudWatch dashboard, click on individual traces to see:
- Agent Invocation: The main request processing
- Memory Operations: Retrieval and storage operations
- Code Interpreter Sessions: Code execution timing
- Model Calls: LLM inference latency
This gives you complete visibility into your agent's performance and behavior.
Cleanup
When you're done experimenting, clean up all resources:
1
uv run agentcore destroy
This removes:
- AgentCore Runtime deployment
- Memory resources (STM + LTM)
- ECR repository and images
- Auto-created IAM roles
- CloudWatch log groups (optional)
Getting Help
- AWS Documentation: Bedrock AgentCore Developer Guide
- Strands Framework: Strands Agents Documentation
Conclusion
AI agents are rapidly becoming the next major computing paradigm. We're moving from applications that respond to explicit commands to intelligent systems that can reason, remember, and act autonomously. Unlike traditional applications, agents need persistent memory that spans conversations, secure environments for dynamic code execution, and sophisticated observability to understand their reasoning processes.
The agent you built demonstrates these emerging infrastructure patterns. Agent platforms like AgentCore provide these capabilities as managed infrastructure, letting you focus on agent logic rather than rebuilding foundational patterns. Whether you use AgentCore or build similar capabilities yourself, understanding these patterns will be crucial as agents become central to how we interact with software.
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article