
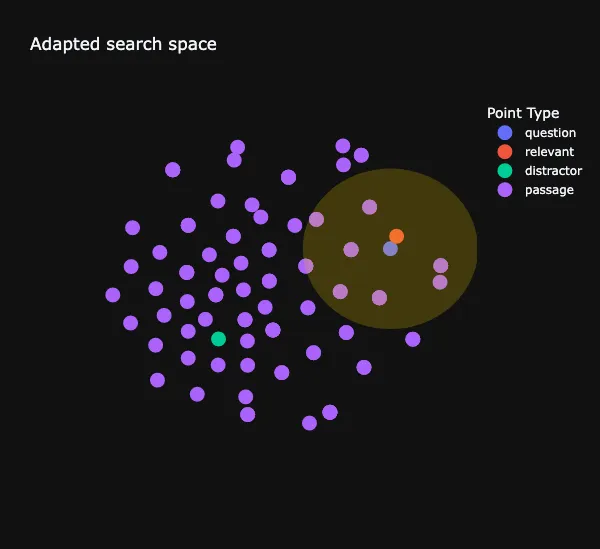
Enhancing Document Analysis with Embedding Adapters on AWS
How can we adapt the best FM on AWS with cost-effective adapters?
Hello AWS Community fellows!
I'm excited to announce a new blog series exploring how AWS services and innovative AI techniques can transform the analysis of complex corporate documents.
## "Decoding Corporate Reports: Embedding Adapters for Precise Question Answering"
This series demonstrates how to use AWS services to implement cutting-edge AI methods, focusing on advanced Retrieval-Augmented Generation (RAG) techniques and embedding adapters.
What We'll Cover
- The Challenge: Extracting insights from lengthy, complex documents.
- The Approach: Adapting language models for specialized tasks without full fine-tuning.
- The Technique: Implementing embedding adapters to adjust off-the-shelf embeddings.
Why It Matters
- For Analysts: Learn to accelerate document analysis and improve accuracy.
- For AI/ML Practitioners: Explore a real-world case study in domain-specific adaptation of RAG.
Series Outline:
- Part 1: Synthetic Data Generation with AWS Bedrock
- Using Anthropic's Claude and AWS Bedrock's Converse API - Part 2: Designing & Implementing Embedding Adapters
- Working with Cohere's embedding models
- Integrating adapters into the RAG pipeline - Part 3: Performance Evaluation and visualization (Coming Soon)
- Part 4: RAG System Showdown (Stay Tuned!)
Getting Started
The first two parts are now available:
I'm eager to engage with the AWS community on this topic. How do you see these technologies shaping document analysis across various industries?
#AWSCommunity #AI #MachineLearning #AWSBedrock
Enjoyed reading this content? Let the author know!
Your likes, comments, shares, and saves help creators reach more builders.

Loading recommendations
Loading article